AI Coding Live News

F
Fudan NLP@FudanNLPยท
๐Ÿ‘€0
๐Ÿ”ฅ98

WorkRover: Fudan Unveils Recursive Environment Evolution for Cowork Agents, Surging JobBench by 26.27%

Training long-horizon cowork agents via reinforcement learning requires scalable, iteratively refined interactive environments. Researchers from Fudan University NLP Lab introduced WorkRover, a framework enabling recursive environment evolution. Featuring Factorial Compatibility Replay (FCR) to maintain alignment across work contexts, tasks, and verifiers, and Verifier-to-Turn Credit Assignment (VTCA) to route progress signals to causal prerequisite turns, WorkRover-35B-A3B outperforms baseline checkpoints by 26.27% on JobBench, 29.32% on OfficeQA Pro, and 413.25 Elo on GDPval v2.

Key Takeaways

  • Recursive environment evolution: empowers construction agents to iteratively adapt work contexts, tasks, and verifiers from workspace execution feedback
  • FCR and VTCA algorithms: Factorial Compatibility Replay selects minimal valid repairs; Verifier-to-Turn Credit Assignment credits causal prerequisite turns
  • Massive empirical leaps: WorkRover-35B-A3B achieves +26.27% on JobBench, +29.32% on OfficeQA Pro, and +413.25 Elo on GDPval v2
Linked Models & Agents:

AutoEnvScaling: Microsoft and Stanford Automate RL Environment Design via Terminal Agents, Unlocking 25x Data Flywheel

Microsoft Research and Stanford University have unveiled AutoEnvScaling, an automated data flywheel that frames RL environment creation itself as a terminal execution task. A proposer agent builds diverse environments directly from solver rollouts, slashing cost per valid environment by 75% while achieving a 25x higher valid environment yield over prompt-only baselines. Crucially, unifying environment design and solving within a single model enables Recursive Self-Improvement (RSI), yielding +12.2 points on Terminal-Bench 2.1 and doubling scores on Terminal-Bench 4.0.

AutoEnvScaling: Microsoft and Stanford Automate RL Environment Design via Terminal Agents, Unlocking 25x Data Flywheel

Key Takeaways

  • Environment design as a terminal task: shifts RL environment synthesis from manual curation to automated terminal execution, boosting valid yield by 25x
  • Unlocks Recursive Self-Improvement (RSI): enables a single backbone to co-evolve as both environment architect and task solver without human bottlenecks
  • Broad cross-domain generalization: yields a 12.2-point surge on Terminal-Bench 2.1 and doubles Terminal-Bench 4.0 for Qwen3.6-35B-A3B across kernel coding and OS tasks

ClawLoop Debuts: Harness-Native Self-Improving Training Loop Enables Teacher-Free Autonomous Agent Evolution

While LLM agents are rapidly deployed into sandbox workspaces with direct shell and filesystem access, post-training methods remain predominantly one-shot and bound by external teacher models. ClawLoop introduces a self-improving, harness-native training loop that operates without external teachers. Through a self-sustaining cycle of task synthesis with difficulty growth, SFT/RL training, and automated behavioral diagnosis, ClawLoop demonstrates consistent empirical gains across SkillsBench, Claw-Eval-Live, and ClawGym-Bench on Qwen3.6-27B, while successfully transferring data to 4B and 9B models.

ClawLoop Debuts: Harness-Native Self-Improving Training Loop Enables Teacher-Free Autonomous Agent Evolution

Key Takeaways

  • Harness-native self-improvement: couples task synthesis, SFT/RL, and behavioral diagnosis in a self-sustaining cycle for shell/sandbox agents
  • Diagnosis-conditioned difficulty growth: leverages failure analysis reports to progressively synthesize challenging yet verifiable workspace tasks
  • Cross-scale data transferability: boosts Qwen3.6-27B across SkillsBench and ClawGym-Bench, while transferring cleanly to 4B and 9B checkpoints
O
OpenAI@OpenAIยท
๐Ÿ‘€2
๐Ÿ”ฅ88

OpenAI will remove GPT-4o, GPT-4o mini, GPT-4.1 and GPT-4.1 mini from the API on January 14, 2027, recommending gpt-6-luna

On Oct 14 OpenAI's API deprecations page announced that GPT-4o (2024-08-06 and 2024-11-20 snapshots), GPT-4o mini (2024-07-18), GPT-4.1 and GPT-4.1 mini (2025-04-14) will be removed from the API on January 14, 2027. Fine-tunes built on them shut down the same day, and the recommended replacement for all four is gpt-6-luna, listed at $0.10 input / $0.50 output per 1M tokens versus $2.50 / $10 for GPT-4o.

OpenAI will remove GPT-4o, GPT-4o mini, GPT-4.1 and GPT-4.1 mini from the API on January 14, 2027, recommending gpt-6-luna

Key Takeaways

  • Shutdown: January 14, 2027 (about 3 months' notice) for gpt-4o-2024-08-06, gpt-4o-2024-11-20, gpt-4o-mini-2024-07-18, gpt-4.1-2025-04-14 and gpt-4.1-mini-2025-04-14
  • Fine-tuned versions follow the base model's shutdown date; existing customers already lose new fine-tuning jobs on Jan 6, 2027
  • Standard price per 1M tokens (input/output): gpt-6-luna $0.10/$0.50, GPT-4o $2.50/$10, GPT-4.1 $2.00/$8.00, GPT-4.1 mini $0.40/$1.60, GPT-4o mini $0.15/$0.60
  • Monitor programmatically via the shutdown_date field on GET /v1/models
  • Second October deprecation wave: older snapshots such as gpt-4o-2024-05-13 and o4-mini shut down Oct 23; gpt-5.3-codex and gpt-5.1 go on Apr 1, 2027
Linked Models & Agents:
ADSponsored

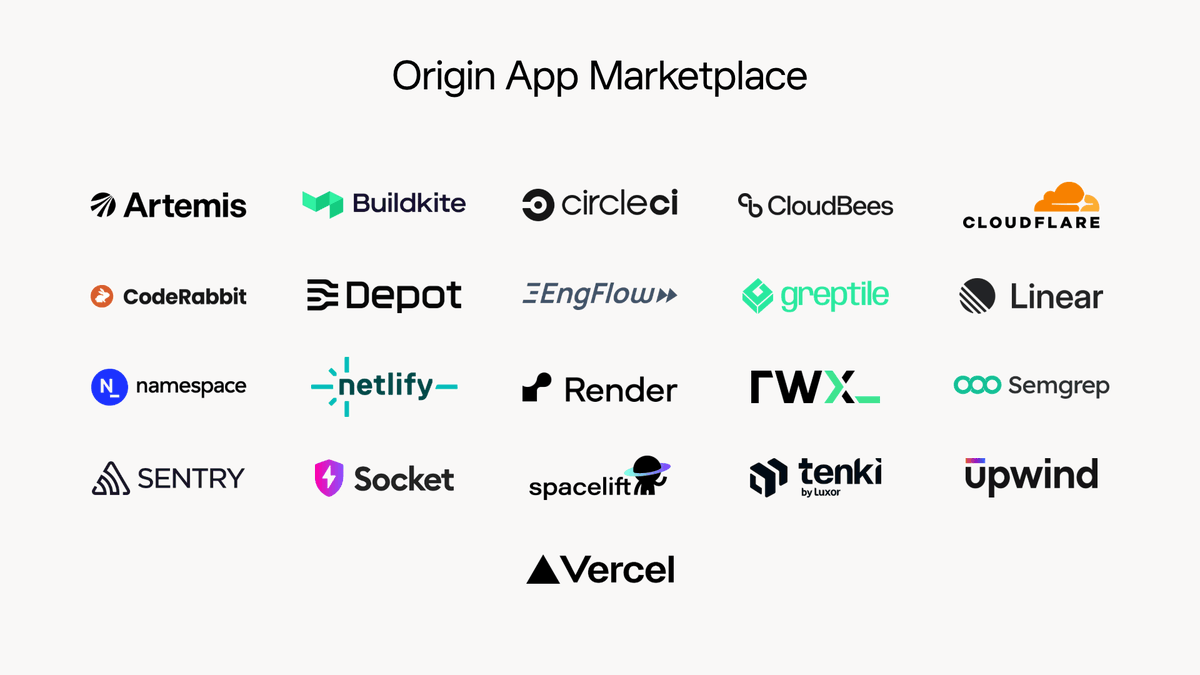
Cursor launches the Origin App Marketplace with 20+ CI, deploy, code-review and security integrations, open to public submissions

On Oct 13 Cursor launched the Origin App Marketplace: its code hosting platform Origin now connects to 20+ apps across deployments (Cloudflare, Vercel and more), CI (CircleCI, Buildkite and more), code review (CodeRabbit, Greptile, Tenki), security (Semgrep, Socket and more), monitoring (Sentry) and project management (Linear), and the marketplace is open to public submissions from any developer-tool team.

Cursor launches the Origin App Marketplace with 20+ CI, deploy, code-review and security integrations, open to public submissions

Key Takeaways

  • 21 launch apps in 6 categories: deploy (5), CI (7), code review (3), security (4), monitoring (1), project management (1)
  • Public submissions: build privately in your namespace, make it public, submit with slug, tags and a demo video, then Cursor reviews and lists it
  • Apps authenticate with an app JWT plus installation access tokens, receive webhooks, and write back check runs, PR comments and reviews
  • The official origin-apps plugin answers questions from live Origin API docs and plans ports of existing apps
  • Launch post: ~1,356 likes and ~68K views as of Oct 14 morning
a
arXiv CS@arXiv_CSยท
๐Ÿ‘€4
๐Ÿ”ฅ96

Multi-Stream Attention Residuals (MSAR): Multi-Head Depth Attention Delivers 1.58x Compute Speedup for Deep LLMs & MoEs

Researchers from Shanghai Jiao Tong University have introduced Multi-Stream Attention Residuals (MSAR), extending Attention Residuals (AttnRes) to multi-head attention along the network depth axis. By integrating multi-scale causal convolutions to retrieve distinct contextual views and combining them via adaptive mixing, MSAR achieves multi-stream capacity without persistent communication or memory overhead. Evaluated across 18B and 28B MoE scales, MSAR delivers a 1.58x iso-loss compute speedup over standard residual baselines.

Multi-Stream Attention Residuals (MSAR): Multi-Head Depth Attention Delivers 1.58x Compute Speedup for Deep LLMs & MoEs

Key Takeaways

  • Residual connection breakthrough: generalizes multi-head attention along the transformer depth axis, overcoming single-stream retrieval limitations
  • Zero persistent memory footprint: generates multi-stream contextual views on demand and fuses them into single-stream activations without persistent tensor cache overhead
  • 1.58x pretraining compute speedup: achieves consistent gains across 12 downstream benchmarks on 18B and 28B MoEs, providing a 1.58x iso-loss training acceleration
Linked Models & Agents:

Prospective Hindsight: Self-Calibrating Reinforcement Learning for Long-Horizon Agents Resolves Miscalibration

Salesforce AI Research has introduced Prospective Hindsight (PH), a self-calibrating training framework for long-horizon autonomous agents. Addressing the fundamental limitation of standard RL where credit assignment occurs strictly after environmental feedback, PH exploits the gap between the agent's pre-action prospective prediction and post-action retrospective evaluation. By weighting gradients with this surprise residual, PH eliminates overconfident failures in single-turn tasks and underconfident successes in multi-turn interactions across GRPO and on-policy distillation.

Prospective Hindsight: Self-Calibrating Reinforcement Learning for Long-Horizon Agents Resolves Miscalibration

Key Takeaways

  • Transcends retrospective credit assignment: captures the surprise residual between pre-action prospective expectations and post-action environmental realities
  • Calibration as an emergent byproduct: minimizing surprise provides an intrinsic descent pathway on agent miscalibration without auxiliary penalty loss terms
  • Resolves dual failure modes: successfully eliminates overconfident failures in single-turn verifiable tasks and underconfident hesitation in multi-turn agent environments

GroundingPI Debuts: 4B Grounding Foundation Model for Physical Intelligence Outperforms GPT-6 Astra Across 34 Benchmarks

Robotic manipulation and physical intelligence systems suffer when relying on general-purpose vision backbones that struggle with dense clutter, tiny objects, and closed-loop control speeds. GroundingPI establishes a dedicated 4B grounding foundation model that unifies points and bounding boxes as quantized coordinates within a shared vocabulary. Outperforming 44 baselines across 34 benchmarks with an average of 73.68% (surpassing GPT-6 Astra at 71.54%), GroundingPI sets a new standard for embodied robotic visual backbones.

GroundingPI Debuts: 4B Grounding Foundation Model for Physical Intelligence Outperforms GPT-6 Astra Across 34 Benchmarks

Key Takeaways

  • Perceptual foundation for physical AI: 4B parameters, unifying visual points and boxes as quantized coordinates for real-time closed-loop control
  • Dominates 34 benchmarks: achieves 73.68% average score across 11 perceptual capabilities, surpassing the larger GPT-6 Astra (71.54%)
  • Empowers robotics and autonomous driving: outperforms existing backbones by up to 24.8% on RoboTwin 2.0 OOD and cuts required training demonstrations by half on RoboCasa-GR1
a
arXiv CS@arXiv_CSยท
๐Ÿ‘€3
๐Ÿ”ฅ95

BranchOPD: Branching On-Policy Distillation Overcomes Trajectory Bottlenecks via Adaptive Decision-Point Forking

On-policy distillation (OPD) is critical for reasoning and agent alignment, yet conventional methods realize only a single continuation per decision, severely restricting supervision under finite compute budgets. Researchers have introduced BranchOPD (Branching On-Policy Distillation), an algorithm that dynamically identifies high-uncertainty and teacher-student disagreement decision nodes to branch and resample continuations from shared prefixes. BranchOPD slashes generation costs by 19%โ€“31% on agent benchmarks while boosting math reasoning accuracy by 18.55 percentage points.

BranchOPD: Branching On-Policy Distillation Overcomes Trajectory Bottlenecks via Adaptive Decision-Point Forking

Key Takeaways

  • Overcomes single-trajectory bottlenecks: BranchOPD dynamically detects high-uncertainty decision points to branch and resample continuations
  • Up to 31% compute reduction: shared-prefix reuse cuts student token generation costs by 19% on ALFWorld and 31% on WebShop compared to multi-rollouts
  • Massive empirical gains: delivers an 18.55 percentage point leap in mathematical reasoning accuracy and a 13.8-point boost in agent task success

PR-OPD: Privileged Representation On-Policy Self-Distillation Supercharges Agentic RL Without External Teachers

Reinforcement learning for language model agents is constrained by sparse episodic rewards and inefficient surface token alignment. Researchers have introduced PR-OPD (Privileged Representation On-policy Self-Distillation), discovering that injecting hindsight skills alters less than 25% of token probabilities while reconfiguring over 80% of internal hidden states. By aligning multi-layer projected representations against a stop-gradient self-teacher, PR-OPD boosts WebShop accuracy by 14.0 points and ALFWorld by 4.7 points with zero inference overhead.

PR-OPD: Privileged Representation On-Policy Self-Distillation Supercharges Agentic RL Without External Teachers

Key Takeaways

  • Overturning token probability assumptions: privileged skills lift agent success by 14 points while altering <25% of token probabilities, yet shift >80% of hidden states
  • PR-OPD framework: aligns layer-wise projected representations against hindsight self-teachers, requiring zero external models and zero inference overhead
  • Benchmark dominance: achieves a 14.0-point leap on WebShop and 4.7 points on ALFWorld, converging 3.2x faster than surface token KL distillation
Linked Models & Agents:
ADSponsored

Thinking Inertia: Stanford and Oxford Reveal Why LLMs Keep Reasoning When Explicitly Told Not To

Researchers from Stanford University and the University of Oxford have published an empirical study examining 'no-thinking' behavior in reasoning LLMs. While developers frequently prompt models to disable explicit thinking to reduce latency and token consumption, the authors discover pervasive 'Thinking Inertia': models persist in generating explicit inference traces even under strict negation instructions, revealing an inherent trade-off between answer-only compliance and task accuracy.

Thinking Inertia: Stanford and Oxford Reveal Why LLMs Keep Reasoning When Explicitly Told Not To

Key Takeaways

  • First systematic study on Thinking Inertia: Stanford and Oxford show explicit prompt negations cannot reliably eliminate reasoning in open-ended tasks
  • Three-tier evaluation framework: introduces Empty-Thinking Rate, Question-Pre-answer Relevance, and Explicit Inference Rate to replace flawed heuristics
  • Compliance vs. accuracy dilemma: enforcing answer-only responses severely degrades open-ended problem solving, while discrete options increase compliance by >40%

Physical Intelligence opens the Pi API beta: upload robot data, fine-tune ฯ€ models on managed compute, and run hosted inference

On Oct 13 Physical Intelligence opened a beta of the Pi API: teams upload robot demonstrations, fine-tune Pi's latest robot foundation model on Pi-managed compute, and serve the result to their robots through a hosted inference gateway. Showcased deployments range from an operator-less wheel loader to strawberry harvesting and server assembly; early-access customer Almond got a deburring policy for its Axol dual-arm robot after four days of iteration. Access is by application and pricing/API parameters are not published; self-hosters can still use the Apache-2.0 openpi repo (ฯ€0/ฯ€0.5 base checkpoints).

Physical Intelligence opens the Pi API beta: upload robot data, fine-tune ฯ€ models on managed compute, and run hosted inference

Key Takeaways

  • Three-step loop: upload data โ†’ fine-tune a ฯ€ model on Pi-managed compute โ†’ run it on your robot via hosted inference, using eval data to plan the next collection round
  • Early-access customer Almond iterated with the API for 4 days to get a policy that lets its Axol dual-arm robot deburr its own assembly parts
  • ~20 named partners/early users (Actor, Chef Robotics, Formic, Ultra, etc.) across Japan, Switzerland and the US; most ran cloud-hosted inference, and Pi flags network connectivity as a known issue
  • Self-host alternative: openpi (Apache-2.0, ~14k stars) ships ฯ€0 / ฯ€0-FAST / ฯ€0.5 base checkpoints pre-trained on 10k+ hours of robot data; inference needs >8 GB VRAM, LoRA fine-tuning >22.5 GB, full fine-tuning >70 GB
  • Beta access is by application; pricing, endpoints and parameters are not published
Linked Models & Agents:
โšก ฯ€0โšก ฯ€0-FASTโšก ฯ€0.5๐ŸŒ Physical Intelligence

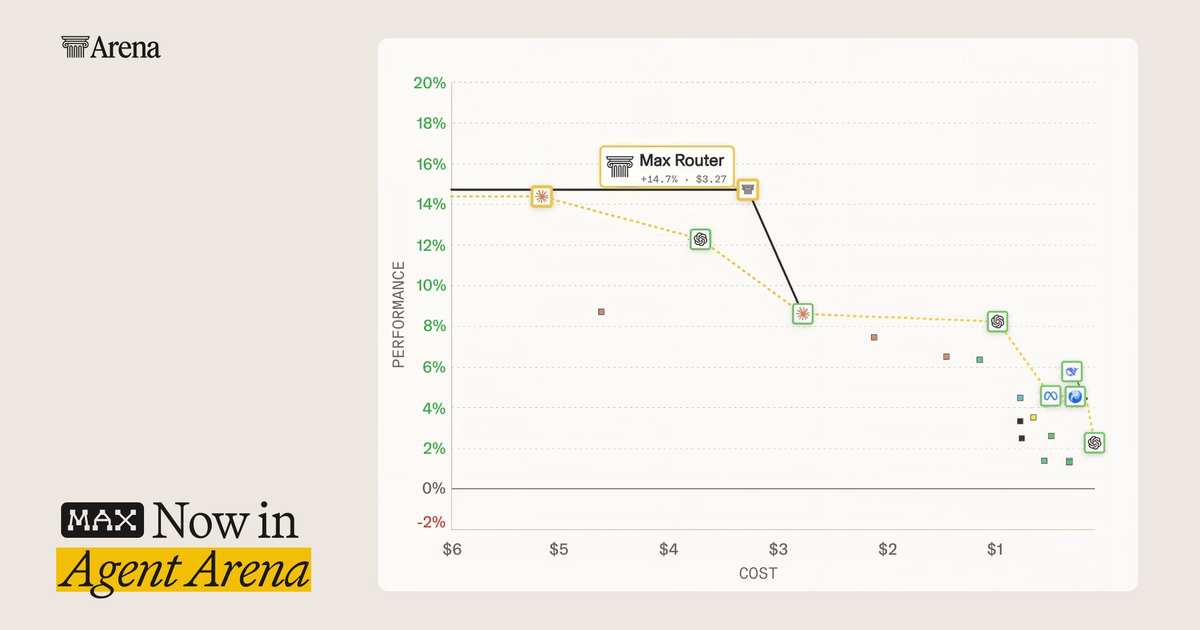
Arena's agentic Max router, trained on 2.5M Agent Arena sessions, tops Agent Arena at a $3.27 median task cost โ€” 37.5% below Fable 5.1 (Max)

Arena released an agentic version of its Max router. Trained on 2.5M+ real Agent Arena sessions, it picks between Fable 5.1 (Max), Astra (Max) and Astra (Medium) per task based on complexity, task type and cost. In a live test it ranked #1 in Agent Arena with a +14.7% score at a $3.27 median cost per task โ€” 0.3% better than the top public model, Fable 5.1 (Max), at 37.5% lower cost โ€” and sent 67% of coding sessions to the cheaper Astra (Medium). It is free to try in Agent Mode for a limited time; API access is via a signup form.

Arena's agentic Max router, trained on 2.5M Agent Arena sessions, tops Agent Arena at a $3.27 median task cost โ€” 37.5% below Fable 5.1 (Max)

Key Takeaways

  • Training data: 2.5M+ real Agent Arena sessions; Arena tested 60+ agentic models over the past 4 months
  • Live test: #1 in Agent Arena with +14.7% score and a $3.27 median cost per task โ€” 0.3% above Fable 5.1 (Max) at 37.5% lower cost
  • Routing mix: code 67% โ†’ Astra (Medium); chat Astra (Max) 49% / Fable 5.1 (Max) 42%; work Fable 5.1 (Max) 49% / Astra (Medium) 43%
  • Model-agnostic: an earlier Fable 5 + Kimi K3 router hit +10.7% net at a $1.06 median cost, 0.6 pp above Fable 5 (High) at 54% lower cost
  • Caveats: trained on data collected before Sept 17 (pre-Opus 5.5); Agent Mode only for now, API via signup
a
arXiv CS@arXiv_CSยท
๐Ÿ‘€5
๐Ÿ”ฅ95

Deconstructing Overconfident Failures in Code LLMs: Instruction Tuning Inflates Confidence on Failing Code

Researchers have conducted the first systematic empirical study characterizing overconfident failures in code LLMs across HumanEval+, MBPP+, and BigCodeBench. Analyzing CodeLlama, DeepSeek-Coder, Qwen2.5-Coder, and OpenCoder, the paper reveals that instruction tuning significantly inflates confidence on erroneous code without improving discrimination between correct and failing programs.

Key Takeaways

  • Disconnect between confidence and execution correctness: erroneous programs exhibit token- and program-level confidence comparable to correct code
  • Side effects of instruction tuning: post-training inflates certainty on failing generations without improving discriminative calibration
  • Latent representations hold hidden signals: exploratory internal state probing shows hidden layers encode correctness indicators suppressed at the output level
Linked Models & Agents:
โšก CodeLlamaโšก DeepSeek-Coderโšก Qwen2.5-Coderโšก OpenCoder๐Ÿค– Code Generation๐Ÿค– Autonomous Programming๐ŸŒ Open Source Research๐ŸŒ arXiv
C
CAS ICT@CAS_ICTยท
๐Ÿ‘€5
๐Ÿ”ฅ96

ChemDiffAgent Debuts: Masked Diffusion Language Agent Breaks Autoregressive Bottlenecks in Chemistry Reasoning

Researchers from the Institute of Computing Technology (CAS ICT) have introduced ChemDiffAgent, the first masked diffusion language agent for tool-integrated chemical reasoning. By replacing standard left-to-right autoregressive generation with iterative trajectory denoising, ChemDiffAgent enables bidirectional molecule comprehension and arbitrary-order tool planning, surpassing conventional models by ~20%.

Key Takeaways

  • Paradigm breakthrough: replaces unilateral causal attention with an iterative denoising process over interleaved reasoning and tool trajectories
  • Two-stage post-training: couples agentic supervised fine-tuning with variance-reduced preference optimization for holistic trajectory valuation
  • 8B model matches frontier LLMs: outperforms autoregressive baselines by ~20% across 6 chemistry tasks, matching or exceeding GPT-5.5 and Claude Opus 4.7