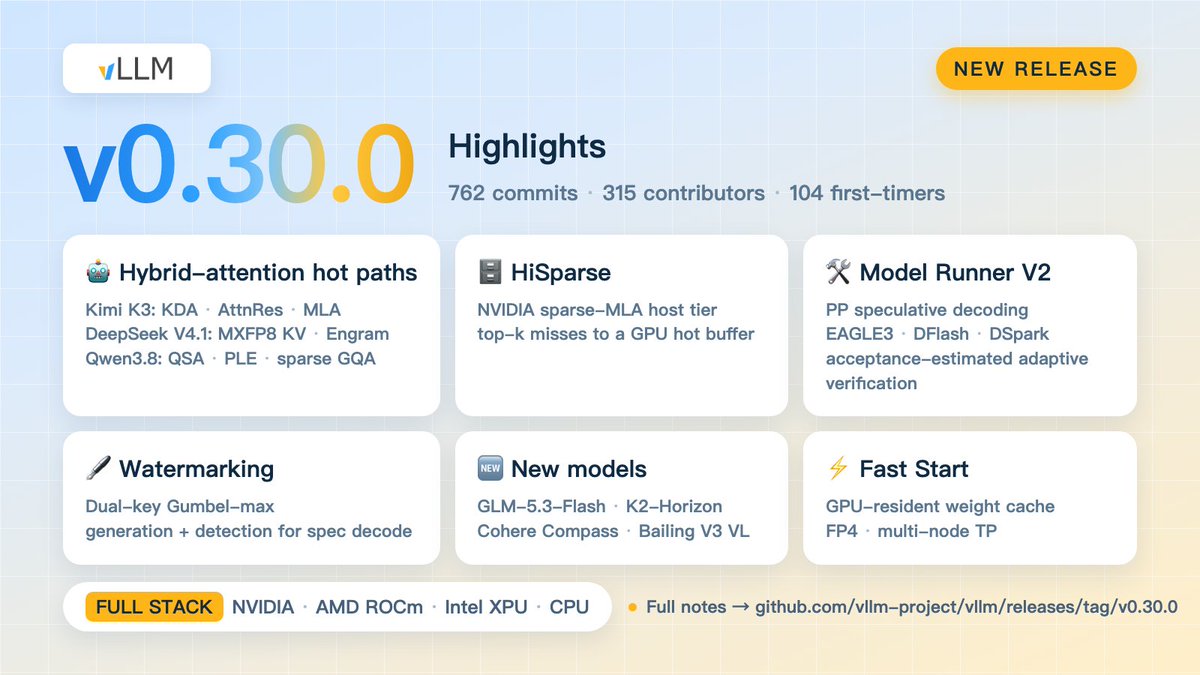
The vLLM project (@vllm_project) released v0.30.0 with 762 commits from 315 contributors. Highlights include hybrid-attention hot paths for Kimi K3 (KDA/AttnRes/MLA), DeepSeek-V4.1-Flash (MXFP8 KV and async Engram), and Qwen3.8-Flash-Next (QSA/PLE, lower sparse-GQA overhead); plus HiSparse host-tier decode, Model Runner V2 EAGLE3 pipeline parallelism with adaptive verification, dual-key Gumbel-max watermarking, Fast Start CUDA IPC weight cache, and new models such as GLM-5.3-Flash, K2-Horizon, Cohere Compass, and Bailing V3 VL.
Key Takeaways
- ✓Hybrid-attention hot paths cover Kimi K3, DeepSeek-V4.1-Flash, and Qwen3.8-Flash-Next.
- ✓Model Runner V2 brings EAGLE3-style drafts to pipeline parallelism with online acceptance estimation.
- ✓Fast Start maps post-quantized TP-sharded weights over CUDA IPC for faster restarts.
🖼️Official Media
⚡
TL;DR VerdictKey Decision Metrics at a Glance
🧭
Not enough VRAM? Compare cloud API and self-hosting costs
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Action HubReady to adopt this in production?
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Up NextvLLM v0.31.0: 717 commits, `vllm preload` fast restarts, DeepSeek-V4.1-Flash FlashMLA default, security gates and breaking changes
Read Now→
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.