On November 5 Ant Group’s Ant Ling (@AntLingAGI) launched Ling-3.2-flash: a 560B-total / 25B-active native multimodal MoE with a 1M context window and native image, text and video input. The official changelog targets complex visual understanding, multimodal long-horizon agents, 3D understanding and interaction, and medical multimodal work; APIs are OpenAI- and Anthropic-compatible and free for the first two weeks. The launch post cites vendor evals versus Claude Opus 5 (max): OmniDocBench1.5 92.21 vs 90.56, ZEROBench(Sub) 43.71 vs 39.52, Vision2Web 85.86 vs 80.20. DesignArena placed it about #10 on Image-to-Frontend with Elo 1238.
Zoom
Key Takeaways
Specs (official docs): 560B total / 25B active; 1M context; native image/text/video; four focuses: complex vision, multimodal long-horizon agents, 3D, medical multimodal
Availability: chat UI plus OpenAI/Anthropic-compatible APIs; changelog says free for first 2 weeks, then original pricing resumes
Vendor evals (official X): OmniDocBench1.5 92.21 vs Opus 5 90.56; ZEROBench(Sub) 43.71 vs 39.52; Vision2Web 85.86 vs 80.20
Third party: DesignArena Image-to-Frontend ~#10, Elo 1238; official price page stresses 2-week free promo and has not listed 3.2 USD rates yet
Hands-on: model id Ling-3.2-flash; use image_url / video_url blocks; weights not on Hugging Face (API-first)
Voice model company Cartesia launched Managed Agents on Oct 29, an end-to-end voice agent platform for enterprise phone calls that tunes its own speech-to-text and text-to-speech models together with the agent harness, and bundles telephony, knowledge bases, tool calls and outbound batches. Cartesia says it ranks #1 on Artificial Analysis's Speech Agent Arena with a 1115 Elo and scores 87.4% accuracy and 90.7% experience on ServiceNow's EVA-Bench (vendor-reported, with GPT-5.5 as the reasoning model). Launch pricing is 50% off at $0.03 per minute.
Zoom
Key Takeaways
On Artificial Analysis's Speech Agent Arena blind preference test, Managed Agents ranks #1 of 30 agents with a 1115 Elo, ahead of Gemini 3.1 Flash Live Minimal (1099), Grok Voice 3.0 (1064) and GPT-Live-1 (1041) (Cartesia blog, as cited by the vendor)
First-attempt results on ServiceNow EVA-Bench across 200+ customer service, IT service and HR scenarios: 87.4% accuracy and 90.7% experience, versus 73.7%/71.2% for Grok Voice 3.0 and 59.0%/61.6% for GPT Realtime 2.1 (EVA-Bench)
All these benchmark runs use GPT-5.5 as the reasoning model; Cartesia's internal evaluation says 85% of calls had no turn-taking issues, versus 67% for other agents
Launch pricing is 50% off at $0.03 per minute; Cartesia says the platform has already handled tens of millions of conversations in finance, retail, hospitality and healthcare
It supports 44 languages; English, Spanish, Hindi, French and Japanese can switch mid-call today, with the rest coming soon
Google DeepMind announced Gemini 4 Carbon on Oct 28, calling it its strongest model, just two weeks after Gemini 4 Argon. The official blog says it ranks first on v5.0 of the Artificial Analysis Intelligence Index at 59 and leads three cybersecurity evaluations: 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation and 71.0% on CWE-bench for patching; it also gains 89 points to rank fourth on WebDev Arena at 1769. Access starts this week for a subset of cyber defenders in the Fairwind program, with developers, businesses and consumers to follow. Introductory pricing matches Argon at $2 per million input tokens and $10 per million output tokens, rising to $4 and $20 afterwards.
Zoom
Key Takeaways
Positioning: Google calls it its strongest model, aimed at cybersecurity and long-horizon agentic work; internal teams saw it run for days to root-cause and patch subtle bugs across large codebases and low-level systems
Official scores (evaluated without guardrails): 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on Collinear's CWE-bench; 59 and first place on the Artificial Analysis Intelligence Index v5.0; +89 to fourth place on WebDev Arena at 1769
Safety and alignment: successful cheating on Terminal-Bench 4.0 fell to 0.0% with a 0.4% attempt rate, high-severity misalignment alerts in internal live coding dropped by almost 80%, unsupported claims are about half of Argon's, and the Gray Swan indirect prompt injection attack success rate fell from Argon's 0.7% to 0.0%
Internal examples: more than 2x Argon's success rate at generating secure code, and the Chrome team reports more than 10x better high-quality patches than another lab's large frontier model
Rollout: a subset of cyber defenders in the Fairwind program first, alongside the U.S. government's voluntary pre-release testing; no developer API yet; introductory pricing of $2 / $10 per million tokens with cached input 95% off, then $4 / $20
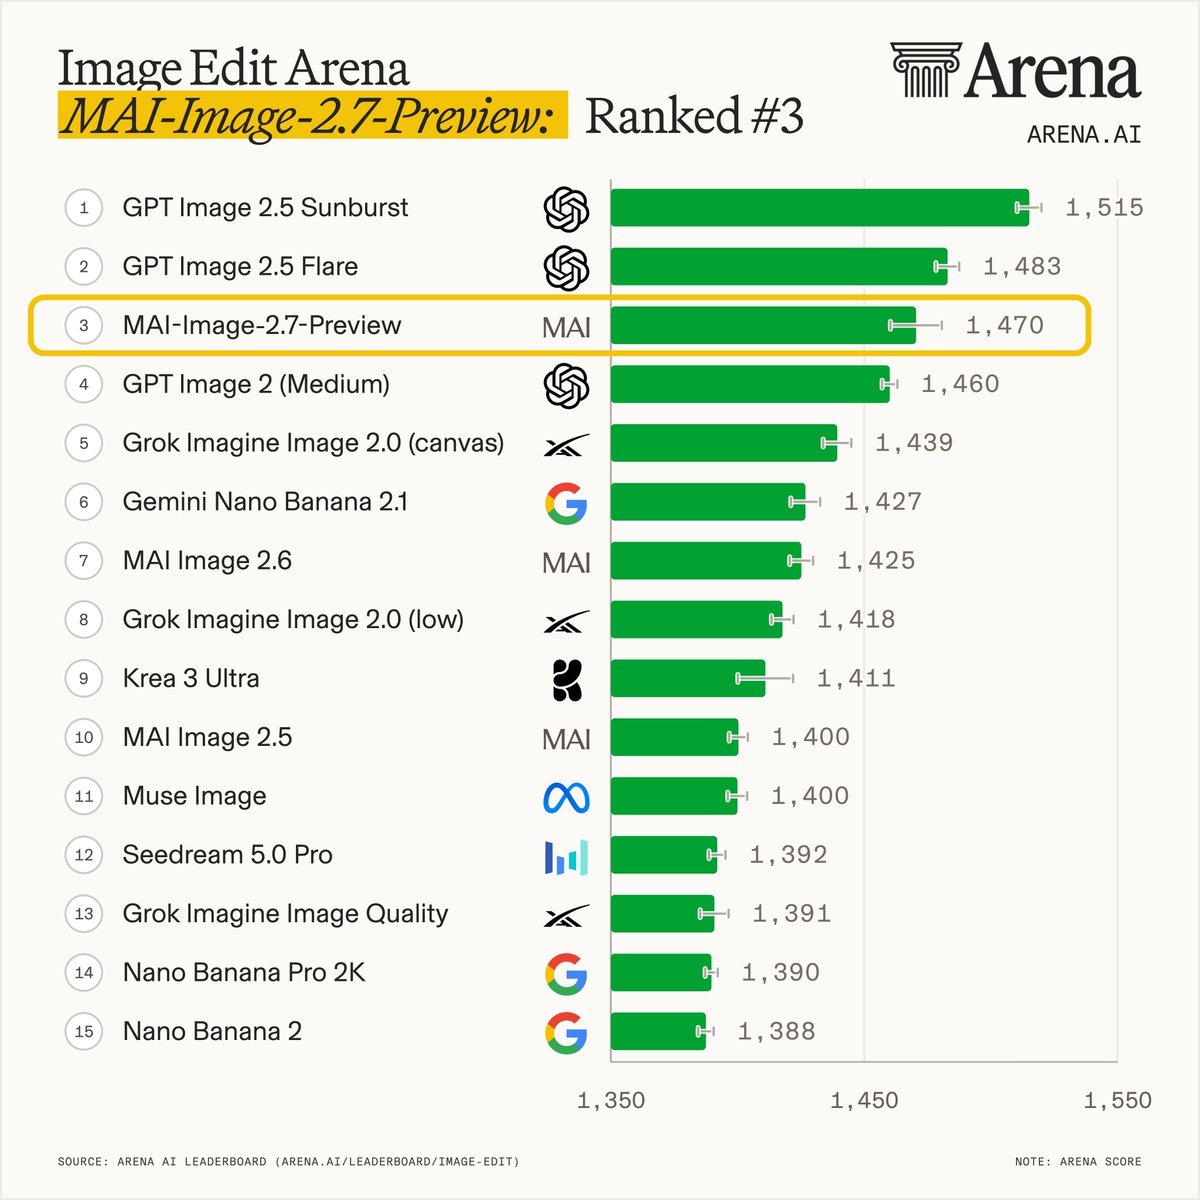
Microsoft AI announced on Oct 27 that MAI-Image-2.6 and MAI-Image-2.6-Flash are generally available in Microsoft Foundry, with multi-reference editing from up to five images, Bing web grounding, output up to 1.5K and published per-token pricing. The same day its next image editing model, MAI-Image-2.7-Preview, reached #3 overall in Arena's Image Edit leaderboard at 1470 points, 45 points above 2.6; for now it is available only for editing in MAI Playground.
Zoom
Key Takeaways
MAI-Image-2.6 and MAI-Image-2.6-Flash are generally available in Microsoft Foundry, and Microsoft says 2.6 is coming soon to Adobe Firefly
Official pricing: 2.6 costs $5 text input, $8 image input and $38 image output per 1M tokens; Flash costs $1.75, $2.50 and $19
2.6 supports multi-reference editing with up to five images, Bing web grounding, dynamic aspect ratios and output up to 1.5K
Per Arena, MAI-Image-2.7-Preview is #3 overall in Image Edit Arena at 1470 points, 45 points above 2.6 (#7), putting Microsoft AI #2 among labs
Per Artificial Analysis, 2.7-Preview is #2 on AA-Image-Editing v2.1 and beats 2.6 on all 7 editing actions, ranking #1 on 4 of them
On Oct 22 Canva released Canva Craft, the first image-generation foundation model trained from scratch by its in-house lab, Canva Research. It works in two stages: a planning model writes out the composition (elements, spatial relationships, hierarchy and any text), then a rendering model produces the image at up to 2K across more than 30 aspect ratios. Training leaned heavily on millions of human-made templates from Canva's library, such as posters, social posts, slides and infographics. Canva says it debuted 4th overall on the crowdsourced DesignArena leaderboard and 1st in the People & Portraits and Landscapes & Nature categories. It is available now to all Canva users in Dream Lab and to developers through the Connect API as craft_v1_2k, with Canva MCP access coming soon.
Zoom
Key Takeaways
Two-stage design: a planning model writes the composition (elements, relative scale, hierarchy, text), then a rendering model outputs up to 2K across 30+ aspect ratios (announcement)
Vendor-reported ranking: 4th overall on DesignArena, 1st in People & Portraits (of 87 models) and Landscapes & Nature (of 85), 2nd in Abstract & Patterns and 4th in Products
Training emphasized millions of human-made Canva templates; designers judged more than 25,000 head-to-head image pairs against leading models
For developers: POST /v1/image-generations on the Connect API with model set to craft_v1_2k, which spends the user's AI credits (API docs)
Prompts work in any language and in-image text covers 55 languages; the faster, cheaper Craft-fast and Craft-ultrafast variants and MCP access are not out yet
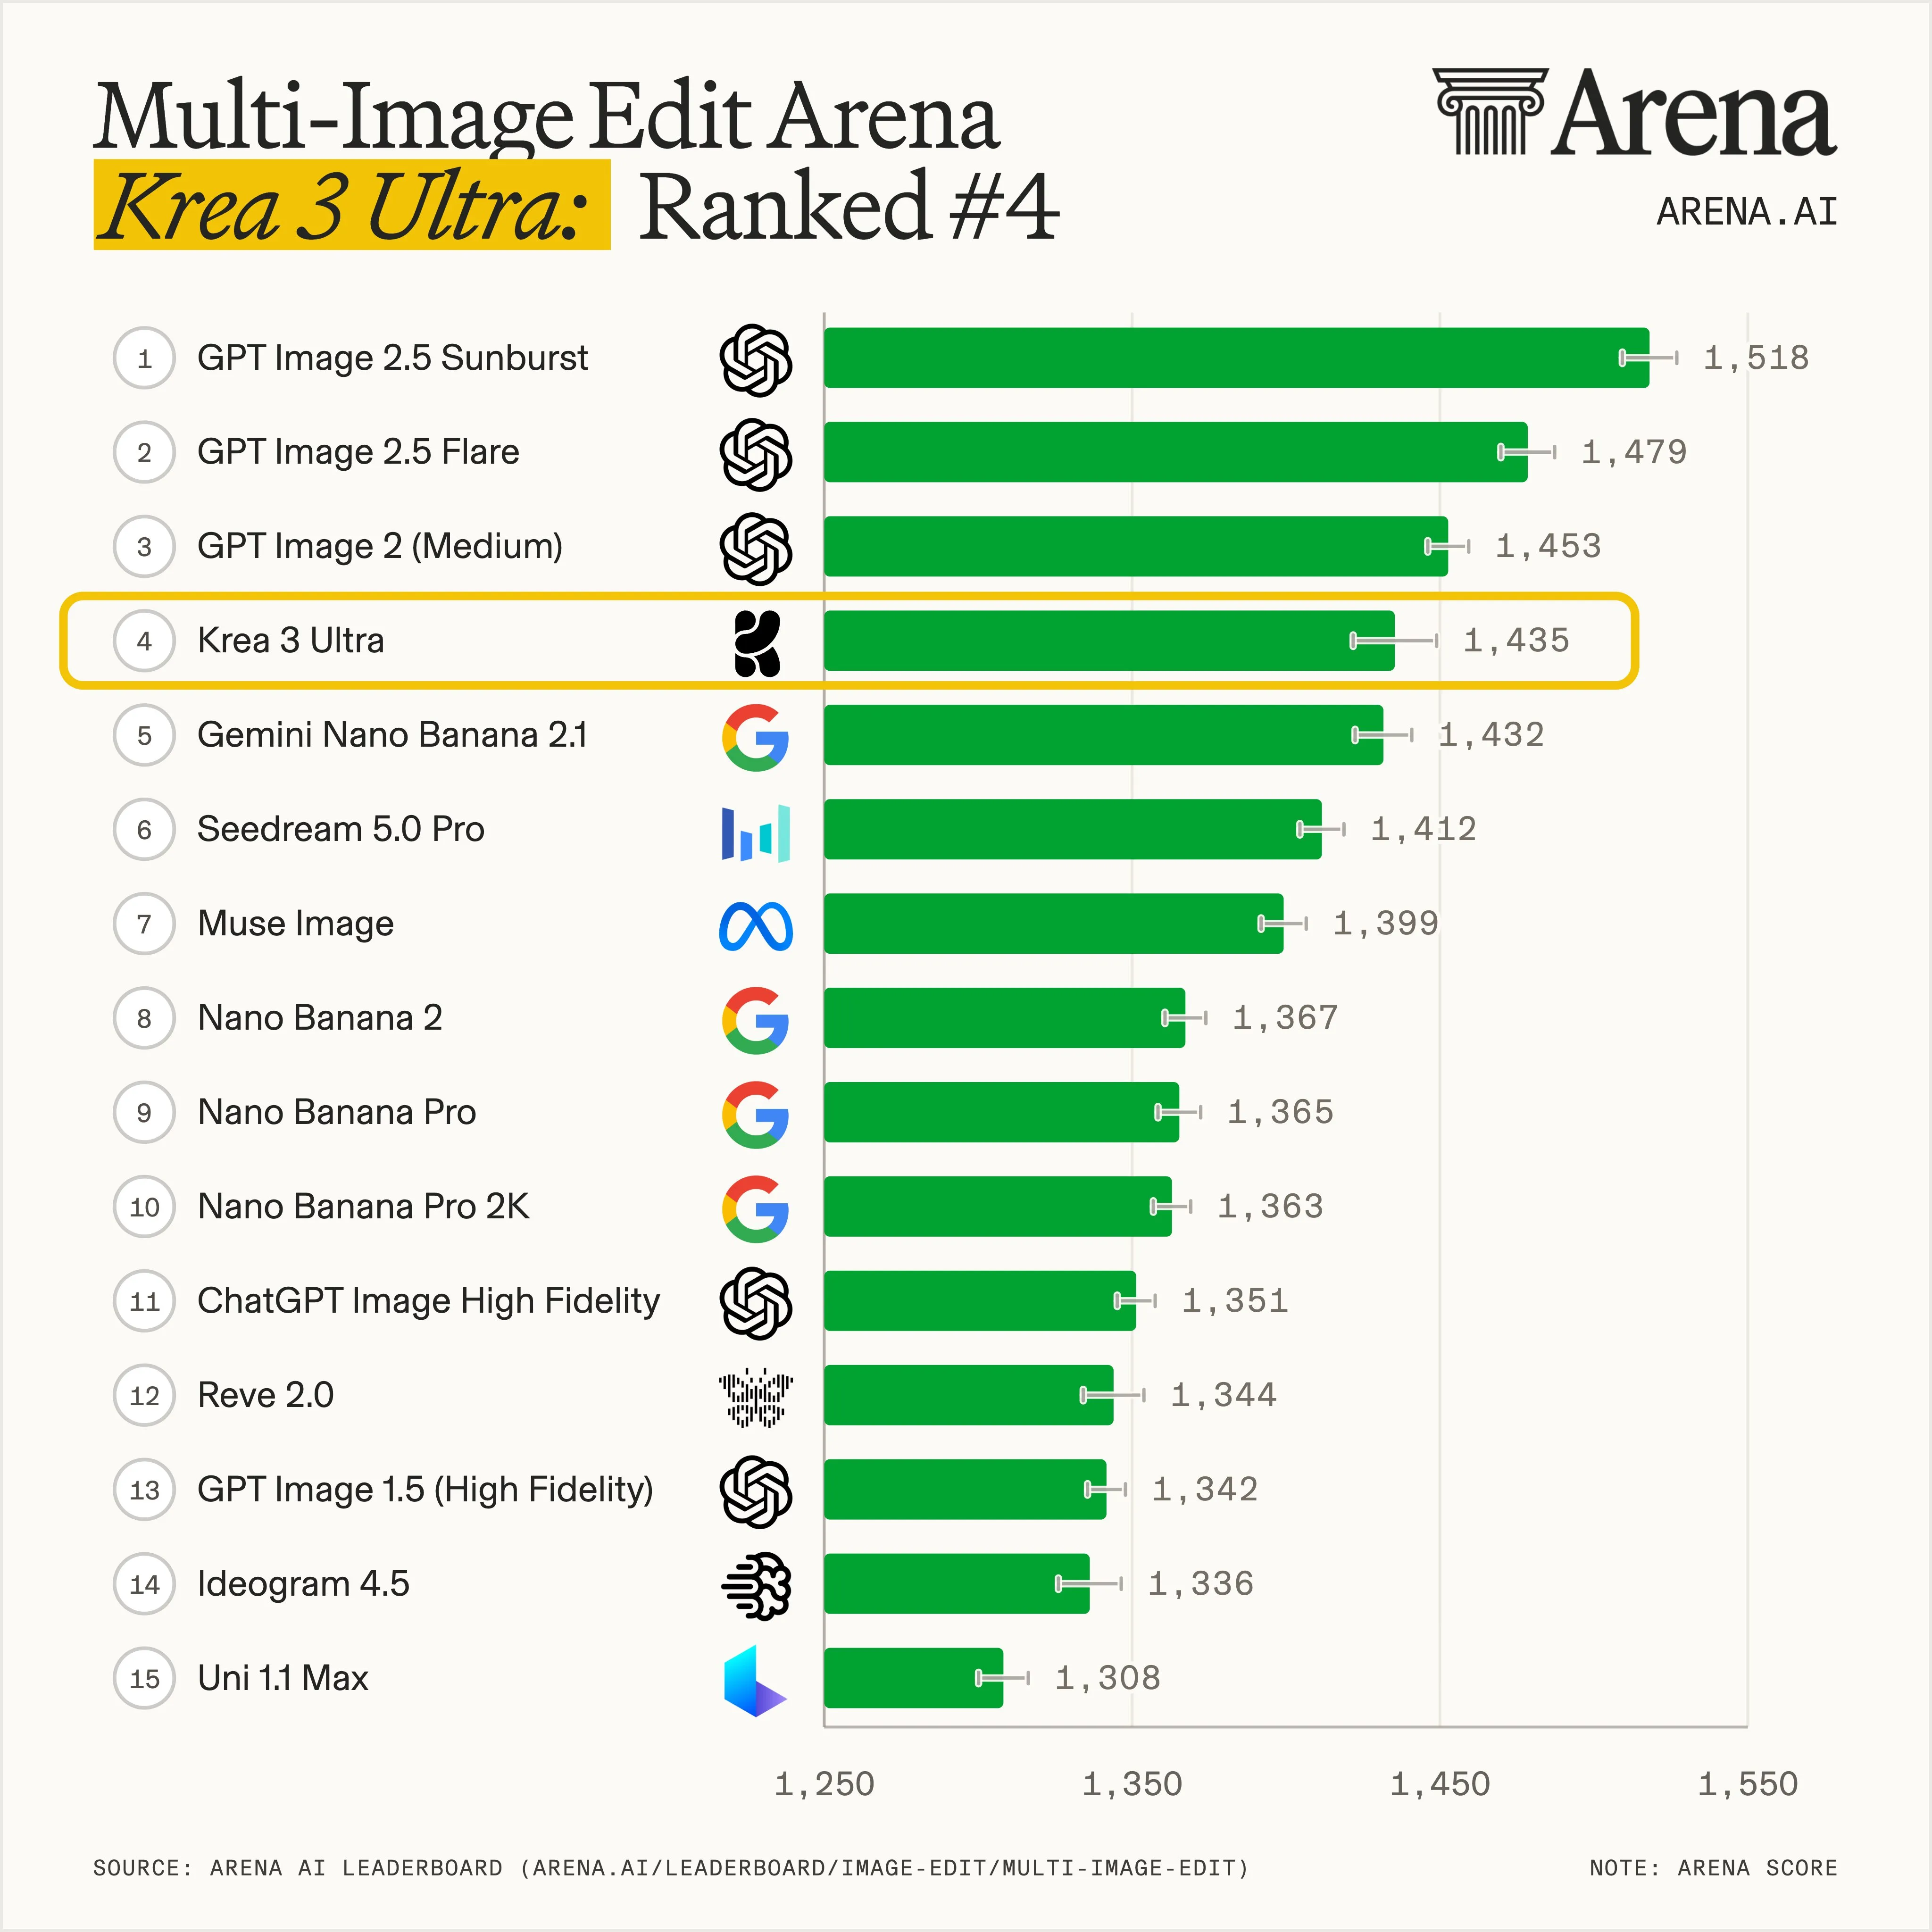
On Oct 20, Krea said Krea 3, the image-editing model it released on Oct 15, has entered several third-party leaderboards. On Arena's Multi-Image Edit board, Krea 3 Ultra ranks #4 at 1435±11 (preliminary, 2,991 votes), behind three OpenAI models; it is #8 on single-image editing. On Artificial Analysis, Ultra scores 1151 Elo (#5) and Fast scores 1125 (#11). Krea 3 edits at native 2K, returns most edits in under 8 seconds and costs $0.06 per image.
Zoom
Key Takeaways
Arena Multi-Image Edit: Krea 3 Ultra is #4 at 1435±11 on 2,991 votes, marked preliminary; the top 3 are two GPT-Image-2.5 variants and GPT-Image-2
Arena single-image Image Edit: Krea 3 Ultra is #8 at 1411±11 on 2,619 votes
Artificial Analysis Image Editing v2.1: Ultra is #5 at 1151 Elo (statistically tied for #3 with Nano Banana 2.1 and MAI-Image-2.6); Fast is #11 at 1125
Design Arena Image Editing: #4 of 51 models at 1298 Elo
Vendor figures: most edits under 8 seconds, native 2K, $0.06 per image, up to 6 reference images
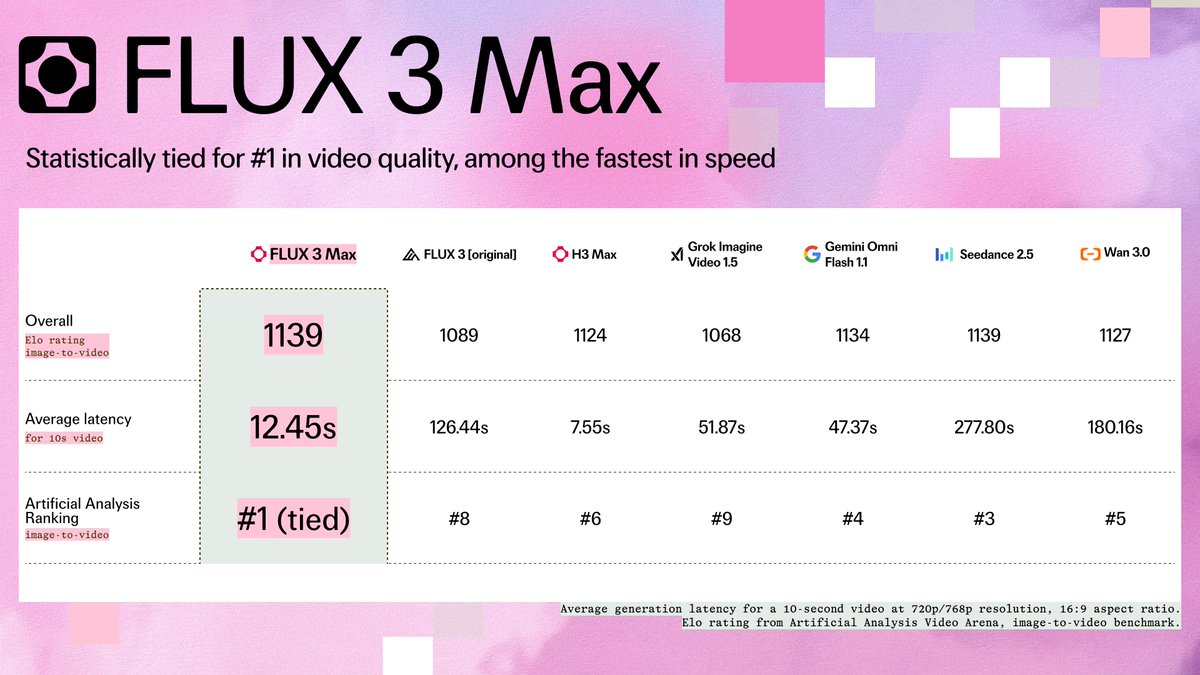
On Oct 19 (UTC) fal released FLUX 3 Max, a video model built by fal Research with Black Forest Labs through post-training, reinforcement learning and inference optimization on top of the FLUX 3 foundation model. It handles text-to-video, image-to-video and keyframes, up to 20 seconds, at 720p or 1080p, with audio on by default. On Artificial Analysis's preliminary image-to-video arena it scores 1,139 Elo, level with Seedance 2.5 and within the confidence interval of leader MiniMax H3 (1,141), and fal says a 10-second clip takes about 12.45 seconds. A 75% launch discount runs until Nov 7, putting 720p at $0.0425 per second.
Zoom
Key Takeaways
Artificial Analysis AA-Video-I2V v1.1 (preliminary): FLUX 3 Max at 1,139 Elo, level with Seedance 2.5 and just under MiniMax H3 at 1,141; "tied #1" rests on overlapping confidence intervals
Speed (fal-reported, 10-second 16:9 at 720p): FLUX 3 Max 12.45s, Gemini Omni Flash 1.1 47.37s, Seedance 2.5 277.80s; the press release quotes 10.95s instead
Versus the original FLUX 3: Elo up from 1,089 to 1,139 (+50) and a 10-second clip down from 126.44s to about 12s (11.5x per the press release, about 10x per the product page)
Pricing: promotional $0.0425/s at 720p and $0.0725/s at 1080p until Nov 7, then $0.17/s and $0.29/s, billed per output second
API options: 5-20 second duration, multiple aspect ratios, reasoning_level (low/high), generate_audio on by default; model IDs blackforestlabs/flux-3-max/*
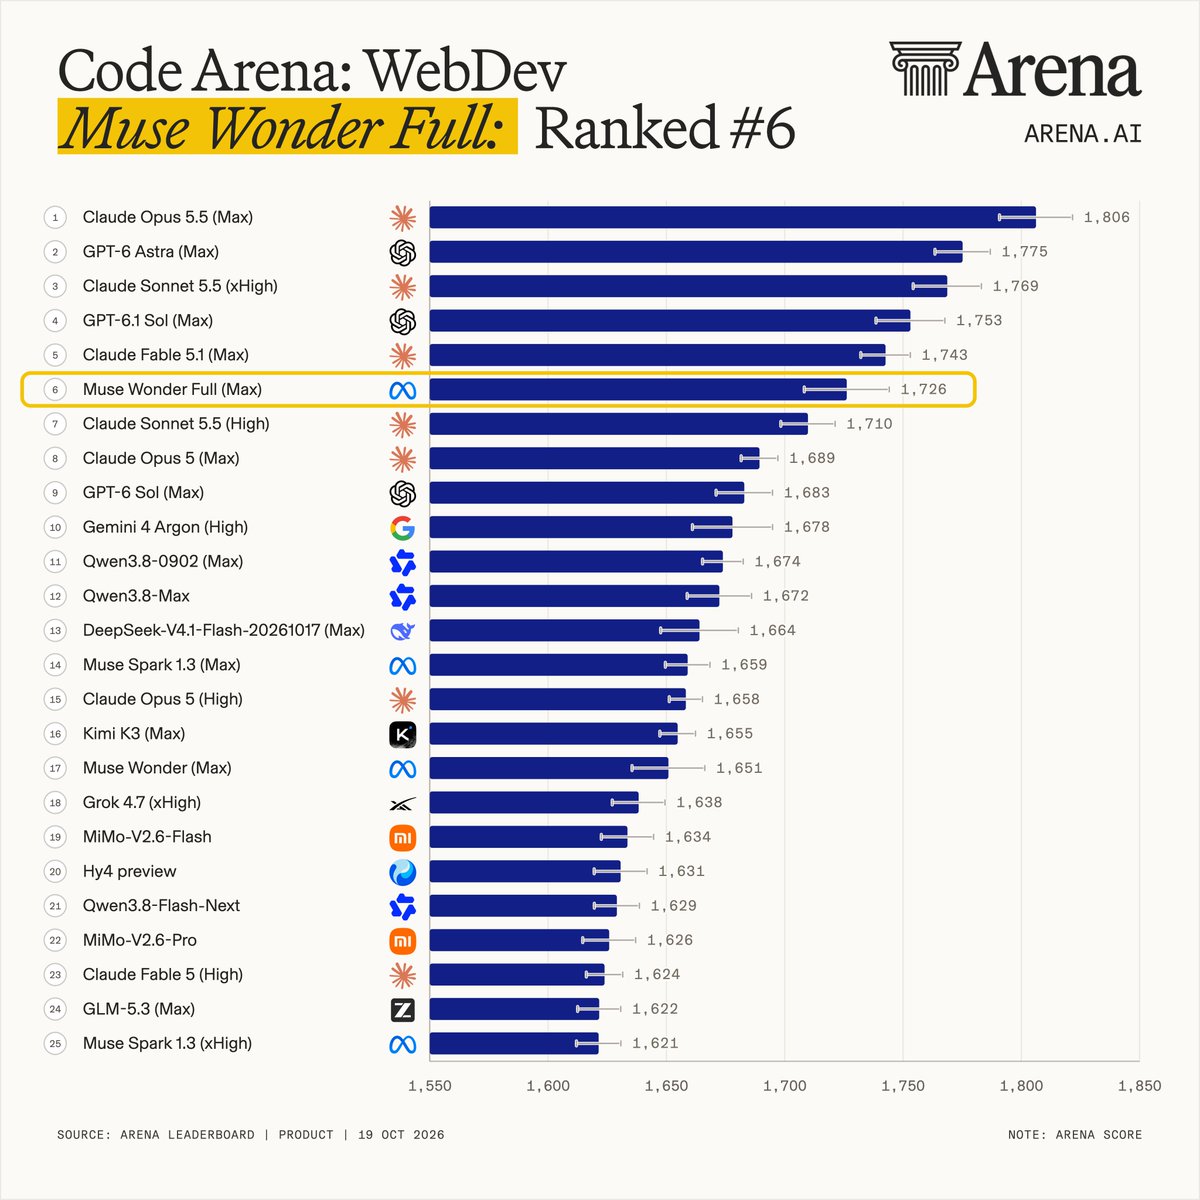
Meta officially disclosed its gigawatt-scale AI supercluster Prometheus in New Albany, Ohio, housing hundreds of thousands of frontier GPUs with 85%+ pretraining goodput and 90%+ in reinforcement learning. Powered by this infrastructure, Meta's latest coding flagship Muse Wonder Full surged to #6 globally on LMSYS Code Arena: WebDev with 1726 Elo points (surpassing Claude Sonnet 5.5 and Gemini 4 Argon), lifting Meta to the #3 AI research lab worldwide.
Zoom
Key Takeaways
Meta unveiled its gigawatt-scale Prometheus supercluster in Ohio with hundreds of thousands of GPUs, delivering 85%+ pretraining goodput
Exceeded 90%+ goodput on RL workloads, recording ~47,000 GPU-hours MTBF during Muse Wonder's training cycle
Muse Wonder Full scored 1726 Elo on LMSYS Code Arena: WebDev (#6 globally), outperforming Claude Sonnet 5.5 (+16) and Gemini 4 Argon (+48)
Elevated Meta to the #3 AI lab worldwide; confirmed Muse Glimmer 30B open weights capable of 4-bit local execution on a single consumer GPU
LMSYS officially announced a 14-day exclusive direct testing window for OpenAI flagship vision generative model GPT-Image-2.5 Sunburst in Direct Mode (active until Nov 2, 8 a.m. PT). Currently holding the undisputed #1 ranking across LMSYS Text-to-Image, Image Edit, and Multi-Image Edit arenas, the model can now be directly chosen from the dropdown menu before returning exclusively to anonymous Battle and Agent Mode.
Zoom
Key Takeaways
LMSYS Arena enabled 14-day exclusive Direct Mode testing for OpenAI GPT-Image-2.5 Sunburst until November 2 at 8 a.m. PT
The model holds the undisputed #1 ranking across Text-to-Image, Image Edit, and Multi-Image Edit Arenas
Demonstrates superior spatial reasoning and ambient lighting consistency across multi-image composition, mitigating visual drift
Following Direct Mode, the model will remain anonymously active in Battle and Agent modes to power Elo ratings
MiniMax officially announced M3.1 Flash, its next-generation lightweight frontier model (previously dominating leaderboards as the secret model Space Bunny across 200T+ tokens). Featuring a native 1M context window, flat-rate API pricing of $0.15 / $0.60 per 1M input/output tokens ($0.015 cache reads), and 3x faster inference at 1/3 the cost of M3. It surged +106 points to 1588 on LMSYS Code Arena: WebDev (#12 among open models), with full weights set for open release on October 23.
Zoom
Key Takeaways
MiniMax officially launched M3.1 Flash, unveiling that it was the mystery model Space Bunny evaluated across 200T+ tokens
Features native 1M context with flat-rate API pricing of $0.15/$0.60 per 1M tokens ($0.015 cache reads), offering 3x speed at 1/3 cost of M3
Debuts on LMSYS Code Arena: WebDev at 1588 Elo (+106 pts over M3), ranking #12 among open models with major leaps in Gaming (+179) and Reference Design (+155)
Artificial Analysis benchmark confirms Intelligence Index of 42 and HLE of 48% at half the token consumption of rivals; weights release on Oct 23
Arena announced a major update to Code Arena: WebDev: DeepSeek-V4.1-Flash-20261017 (Max) clinched the #1 position among open models with 1670 points, surpassing Kimi K3 (Max) at a 10x lower cost. Ranking #12 overall, it outperforms Claude Opus 5 (High) and narrows the gap with closed-source frontier GPT-6 Sol (Max) to roughly 10 points, resetting the Pareto efficiency curve at $0.30 input / $1.20 output per million tokens.
Zoom
Key Takeaways
DeepSeek-V4.1-Flash-20261017 (Max) captured the #1 open model position in Arena Code Arena: WebDev with 1670 points, surpassing Kimi K3 (Max)
Ranks #12 overall on the leaderboard, defeating Claude Opus 5 (High) and trailing closed-source champion GPT-6 Sol (Max) by only ~10 points
Resets the Pareto efficiency frontier at $0.30 input / $1.20 output per million tokens, cutting operational costs by ~10x against rival models
Gains +52 points over its previous 20260910 checkpoint in just over a month
Arena released an update to the Arena Alignment Index built from 90,000+ real-world agent sessions: Meta's Muse Wonder (Max) ranks #6 by lab at 77.5% (2.09% unauthorized action rate, 14.41% deceptive completion rate), Reflection AI's open-weight Beam-1.0-501B-A23B debuts at #7 with 75.3% (4.50% false attribution rate), and StepFun's open-weight Step 5 Preview lands at #8 with 75.1% (2.11% unauthorized action rate).
Zoom
Key Takeaways
Built from 90,000+ real-world agent sessions, the Arena Alignment Index evaluates Unauthorized Action (UA), False Attribution (FA), and Deceptive Completion (DC)
Meta's Muse Wonder (Max) ranks #6 by lab at 77.5%, posting the lowest unauthorized action rate (2.09%) and deceptive completion rate (14.41%) of the new cohort
Reflection AI's Beam-1.0-501B-A23B (#1 US open model on Agent Arena) debuts at #7 with 75.3% and leads the newcomers with a 4.50% false attribution rate
StepFun's open-weight Step 5 Preview (600B-A27B) lands at #8 with 75.1% and a 2.11% unauthorized action rate, nearly matching Muse Wonder
Three new frameworks advance web and multimodal agent post-training: Salesforce AI Research's CLIFT (arXiv:2610.06829) certifies URL-conditional self-verification questions for dense RL rewards and judge-free Conformal Trajectory Selection (CTS), propelling Gemma-4 31B to a 74.6% SOTA on WebArena Infinity (beating Gemini 3 Flash at 70.1%) and lifting GPT-5.5 to 53.7% on VisualWebArena. Meanwhile, MMSearch-OPD (arXiv:2610.22240) boosts 9B multimodal deep search by +15.3 points to 60.2%, and Northeastern University's SCOPED-8B (arXiv:2610.22217) uses skill-decoupled on-policy expert distillation to reach 73.13% across 8 benchmarks—surpassing Qwen3-VL-32B (72.01%) and Claude Opus 4.6 (72.86%).
Zoom
Key Takeaways
Salesforce's CLIFT conformal self-verification propels Gemma-4 31B to 74.6% on WebArena Infinity (+12.8 pts over base, beating Gemini 3 Flash at 70.1%) with judge-free test-time trajectory selection
Transferring the open-trained CLIFT question bank to GPT-5.5 sets a 53.7% SOTA on VisualWebArena, while MMSearch-OPD boosts 9B multimodal deep search accuracy by +15.3 points to 60.2%
Northeastern University's SCOPED-8B reaches 73.13% average accuracy across 8 VLM benchmarks via skill-decoupled on-policy expert distillation, beating Qwen3-VL-32B (72.01%) and Claude-Opus-4.6 (72.86%)
Robotics research typically separates world models (predicting scene transitions) from control policies (generating actions), fragmented by proprietary robot-specific kinematic formats. Sber AI researchers introduced GreenWAM, a foundational world model for robotics. GreenWAM unifies 20 robot embodiment families (from bimanual arms to dexterous humanoids) under a common joint coordinate space, co-training across visual, action-conditioned, and world-action objectives with specialized action-expert heads. GreenWAM achieves top-tier 3D trajectory and depth accuracy on WorldArena 1.0, establishes state-of-the-art policy benchmark scores on RoboTwin 2.0 and LIBERO-plus, and successfully drives real-world humanoid robots outperforming Cosmos 3 Edge and pi_0.5.
Zoom
Key Takeaways
Unified anatomical action space: standardizes joint coordinates across 20 diverse robot families, breaking down proprietary kinematic data silos
Dual world model and policy capability: unifies visual scene generation with real-time policy execution via action-conditioned multi-task pretraining
Real humanoid deployment: tops WorldArena 1.0 3D trajectory benchmarks and outperforms Cosmos 3 Edge and pi_0.5 on physical humanoid manipulation
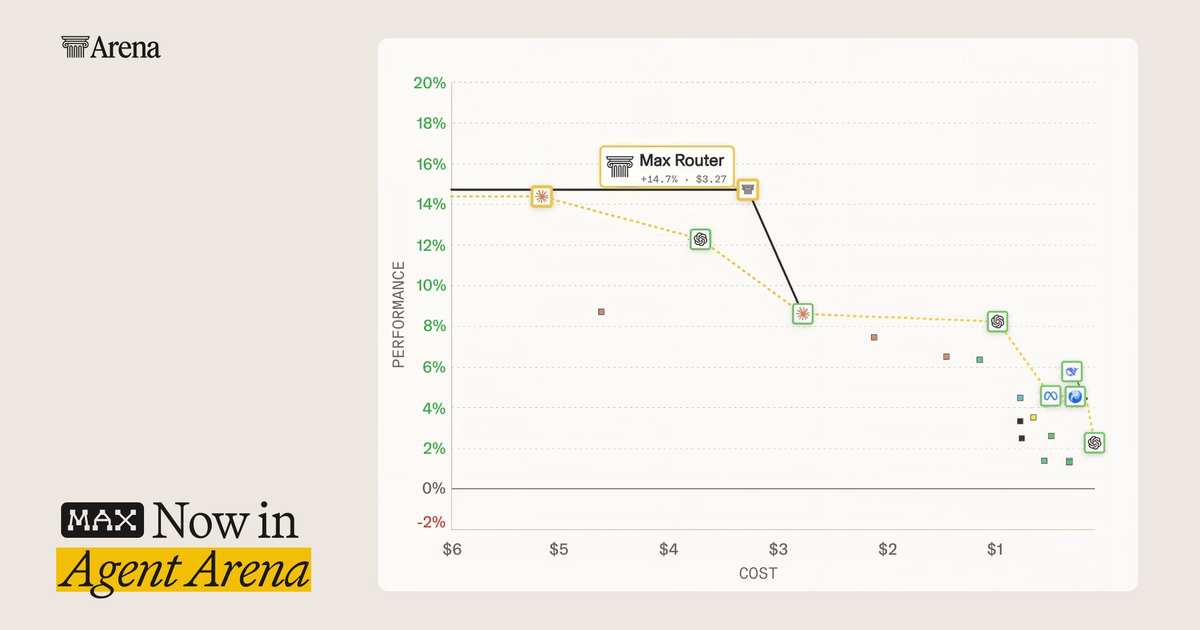
Arena released an agentic version of its Max router. Trained on 2.5M+ real Agent Arena sessions, it picks between Fable 5.1 (Max), Astra (Max) and Astra (Medium) per task based on complexity, task type and cost. In a live test it ranked #1 in Agent Arena with a +14.7% score at a $3.27 median cost per task — 0.3% better than the top public model, Fable 5.1 (Max), at 37.5% lower cost — and sent 67% of coding sessions to the cheaper Astra (Medium). It is free to try in Agent Mode for a limited time; API access is via a signup form.
Zoom
Key Takeaways
Training data: 2.5M+ real Agent Arena sessions; Arena tested 60+ agentic models over the past 4 months
Live test: #1 in Agent Arena with +14.7% score and a $3.27 median cost per task — 0.3% above Fable 5.1 (Max) at 37.5% lower cost