
Artificial Analysis Ships Endpoint Accuracy Index v1.1: Nearly 1 in 4 of 100+ Serverless Endpoints Score Below Reference
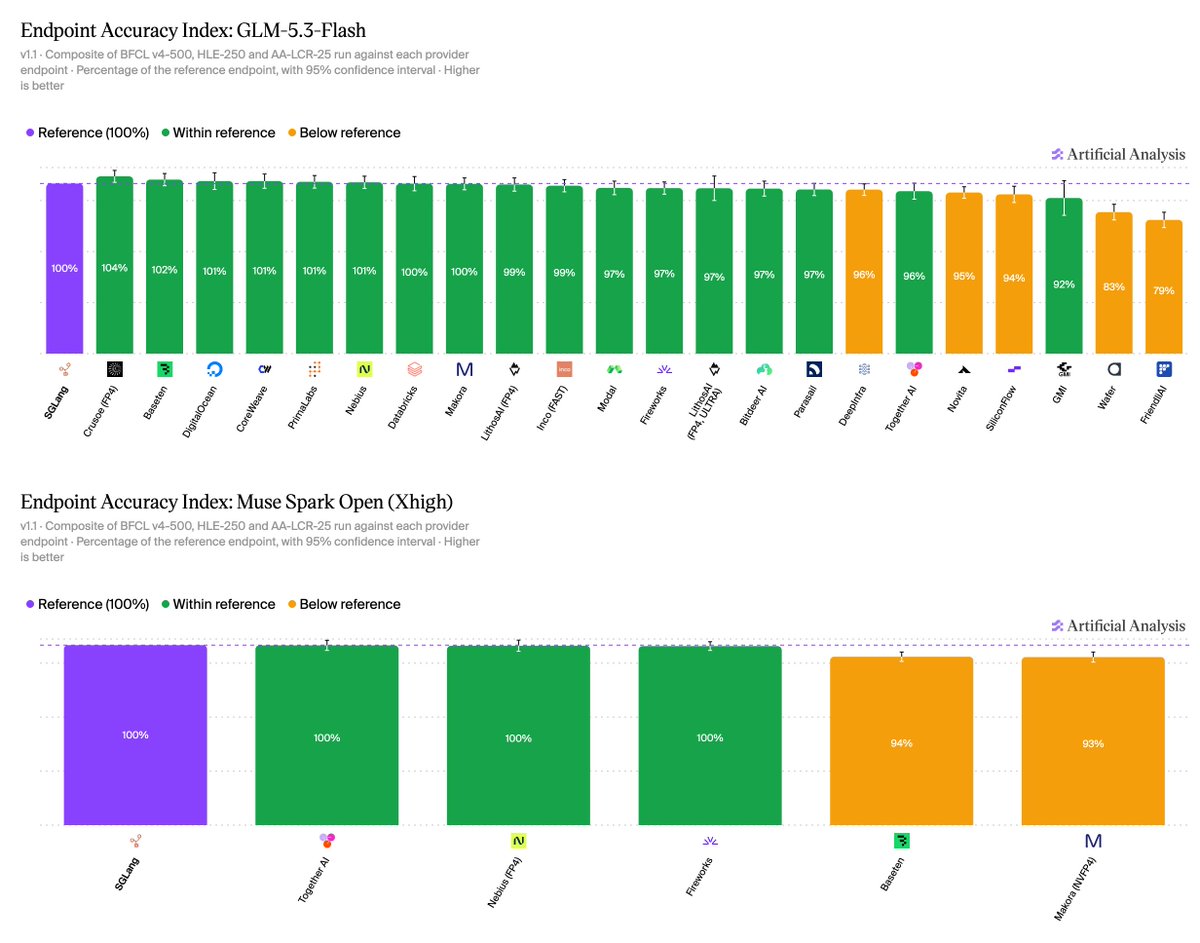
On 2026-11-06 Artificial Analysis launched Endpoint Accuracy Index v1.1: each serverless endpoint is scored as a percentage of a self-hosted official-weights reference across equally weighted BFCL-500, HLE-250, and AA-LCR-25. Vendor claim: nearly 1 in 4 of 100+ benchmarked endpoints score below the reference. AA-LCR-25 moved to v1.1 with repeats raised from 10 to 25 (average 95% CI ~±4.7 to ±2.6), and coverage expanded to six open-weights models including GLM-5.3 Flash and Muse Spark Open.
Key Takeaways
- Official: @ArtificialAnlys 2026-11-06 02:44 UTC; changelog 05 Nov 2026; methodology Endpoint Accuracy Index v1.1
- Vendor claim: nearly 1 in 4 of 100+ serverless endpoints score below the self-hosted reference; providers often quantize, custom-kernel, tune stacks, or cap outputs
- Equal-weight suite: BFCL v4-500 (3 repeats), HLE-250 (10), AA-LCR-25 (25); 95% CIs vs reference with significance flags
- GLM-5.3 Flash: 16 of 22 endpoints statistically in line, one ~104.2; ~32K output caps scored ~22%/29% on HLE-250 vs 55% reference
- Muse Spark Open: 3 of 5 endpoints ~99.5–99.9 (incl. FP4); two mainly lose on tool calling (BFCL-500 ~50%/51% vs 59%)
Linked Models & Agents:

