AI Coding Live News

Artificial Analysis Makes Time per Task Its Headline Performance Metric: GPT-6 Astra Finishes a Max-Effort Task in About 17 Minutes, Ahead of Opus 5.5 and Gemini 4 Carbon

Independent benchmarker Artificial Analysis announced on X on November 4 (17:34 UTC) a new version of its API performance benchmarking: the headline metric moves from output speed to Time per Task, the time to finish one Intelligence Index task (output tokens per task divided by end-to-end output speed). It covers about 1,000 serverless endpoints, measures speed from sending the request to the final token, and adds multi-turn agentic coding and knowledge-work workloads. Per its data, GPT-6 Astra at max effort runs at 51 tokens/s yet finishes a task in about 17 minutes, against about 26 for Claude Opus 5.5 (max) and about 29 for Gemini 4 Carbon (high).

Key Takeaways

  • Time per Task equals output tokens per Intelligence Index task divided by end-to-end output speed, so a model that is fast per token but verbose can finish later than a slower model that uses fewer tokens.
  • End-to-end output speed runs from sending the request to the final token, including the wait before the first token (prefill and hidden reasoning); output tokens now come from each provider's API-reported counts instead of the o200k_base tokenizer.
  • GPT-6 Astra (max) runs at 51 tokens/s with about 50k output tokens per task and takes about 17 minutes; Claude Opus 5.5 (max, 111 tokens/s) takes about 26 minutes and Gemini 4 Carbon (high, 71 tokens/s) about 29, using roughly 120k to 170k tokens per task.
  • At each lab's API default effort (medium for all three), GPT-6 Astra, GPT-6.1 Sol and Opus 5.5 cut Time per Task by about 3 to 5x and Cost per Task by about 2 to 4x, scoring about 5 to 11 points lower; Opus 5.5 drops from about 26 minutes and $10.04 to about 6.8 minutes and $2.45.
  • The official methodology page lists this as version 3.0.0 (October 30), with runs now every 6 hours and a new endpoint error rate metric.
Read full story

Sarvam Releases Prism, an Open-Weight Decision Model Built on Sarvam 105B That Returns Calibrated Option Probabilities in About 44 ms, Apache 2.0

Indian AI company Sarvam released Sarvam Prism on November 3, a "System One" decision model for enterprise workflows: given a context and questions with fixed answer options, it returns a probability for every option in a single forward pass instead of generating text. Sarvam says that across the 25 decision models it tested, Prism averages 71.8 over three indices with a median response time of 44 ms on one B200, the highest score under 100 ms, and scores 82.5 on its Indian-language benchmark. Weights are on Hugging Face under Apache 2.0, with a hosted API as well. All scores are Sarvam's own measurements.

Sarvam Releases Prism, an Open-Weight Decision Model Built on Sarvam 105B That Returns Calibrated Option Probabilities in About 44 ms, Apache 2.0

Key Takeaways

  • Trained on the Sarvam 105B (105B-10B MoE) base; it only outputs option probabilities, so the answer is always one of the given options.
  • Vendor-reported indices: Jev Decision Index 67.0, Sarvam's recreation of the Artificial Analysis decision index 65.9, internal Indian-language benchmark 82.5, average 71.8; Perplexity Decider v1.2 averages 68.0 at about 117 ms.
  • Calibration: on English answers at 90%+ confidence it expects 3.3% errors and makes 2.2%; in Indian languages 5.4% expected vs 4.4% actual, while rivals underestimate errors by 1.5x to 4.8x.
  • By sorting options into a fixed order before scoring, it changed 0 of 2,000 answers across four shuffled option orders.
  • On 700 recorded agent runs it judges correctly 78.5% of the time overall, vs 70.7% for Claude Haiku 5.5.
  • Self-hosting needs one FP8-capable GPU with about 120 GB free memory (such as B200 or H200) and about 106 GB of disk for weights.
Read full story
Linked Models & Agents:
⚡ Sarvam Prism⚡ Sarvam 105B⚡ Perplexity Decider v1.2⚡ Jev 1.14⚡ Microsoft-Decision-1⚡ Claude Haiku 5.5🌐 Sarvam

DeepSeek Harness Launches Creator Mode: Describe a Plugin in Chat and the Agent Builds It, With 7 Official Demo Prompts

DeepSeek Harness, DeepSeek's open-source, MIT-licensed agent app, announced Creator Mode on its official X account on November 2: users describe the plugin they want in plain language, and the agent turns it into a plugin they can use. Demos include a 3D landmark gallery, a 3D Transformer visualizer, a video editing workbench and a paper reader. DeepSeek also published seven bilingual demo prompts on cdn.deepseek.com, cautioning that some plugins took several rounds of conversation, so a single prompt may not reproduce the video exactly. The post drew about 20,000 likes and 1.69 million views. No benchmarks were published.

DeepSeek Harness Launches Creator Mode: Describe a Plugin in Chat and the Agent Builds It, With 7 Official Demo Prompts

Key Takeaways

  • Creator Mode: describe the plugin you want in natural language and the agent turns it into a usable plugin, from a design workspace to a sandbox game or a 3D LLM visualizer.
  • DeepSeek published 7 demo prompts: a 3D landmark gallery, a 3D Transformer demo, a five-style app theme switcher, a poster workbench, a video editor, a paper reader and a token-usage statistics plugin.
  • The entry point shipped in v0.2.1-rc.5 (Oct 30 pre-release): plugin management gained a "Let Agent create a plugin" button that opens Creator mode and keeps the draft.
  • The GitHub repo has about 270,000 stars under the MIT license; Harness is still in preview.
  • No benchmarks or success rates were published; the announcement drew about 20,000 likes and 1.69 million views.
Read full story
Linked Models & Agents:

OpenAI Introduces LifeVal, a Benchmark for Everyday Life Tasks Built From Time-Use Studies and a 3,995-Person Survey

On November 2 OpenAI published LifeVal, an evaluation of whether AI can actually get everyday tasks done for ordinary people, such as finding childcare, accessing government services, budgeting, ordering groceries and adapting recipes. The task list draws on the American Time Use Survey, the Multinational Time Use Study and a new demographically representative OpenAI survey of 3,995 people. OpenAI says it has used LifeVal for the past year to track and improve its models, and it lists several best recorded GPT-6 Astra task scores, many at 100%. All scores are vendor-reported and have not been independently reproduced.

OpenAI Introduces LifeVal, a Benchmark for Everyday Life Tasks Built From Time-Use Studies and a 3,995-Person Survey

Key Takeaways

  • Task sources: the American Time Use Survey, the Multinational Time Use Study and a new representative OpenAI survey of 3,995 respondents (official blog).
  • Domains covered: caregiving, health, education, household administration, personal finances, shopping and government services.
  • Example scores (vendor-reported): kindergarten enrollment after a move 93.1%, flood volunteer coordination 98.0%, home search with deed added to cart 100%, diabetes meal plan 90.4%.
  • GPT-6 Astra's best recorded score is 100% on tasks such as booking a toddler sensory class, booking a car inspection, ordering halal groceries within budget and unsubscribing from email lists.
  • The official text we read gives no full task count or overall score, so overall figures circulating on X are not used here.
Read full story
ADSponsored

SemiAnalysis releases GDPx, an agentic benchmark of 206 tasks across 11 high-value domains where the top model, Claude Opus 5.5, scores just 12%

On Nov 2, semiconductor and AI research firm SemiAnalysis released GDPx, a benchmark of agentic capability across 11 domains: chip design, cybersecurity, biology, finance, legal, quant trading, recursive self-improvement (RSI), hardware design, materials science, alignment and software engineering. Its 206 tasks were built by 14 specialist data partners, with SemiAnalysis doing final QA. On the official leaderboard Claude Opus 5.5 leads at 12.0%, followed by Gemini 4 Carbon at 10.9% and GPT-6 Astra at 9.6%; nearly every model scores 0 on finance and legal. SemiAnalysis says safety classifiers drag down Opus 5.5 and GPT-6 Astra, and plans a new version every 3–6 months. All scores are as reported by SemiAnalysis.

SemiAnalysis releases GDPx, an agentic benchmark of 206 tasks across 11 high-value domains where the top model, Claude Opus 5.5, scores just 12%

Key Takeaways

  • Scale: 11 domains, 14 data partners and 206 tasks, with a default time limit of 8 hours per task (GDPx site)
  • Leaderboard (as reported by SemiAnalysis): Claude Opus 5.5 12.0%, Gemini 4 Carbon 10.9%, GPT-6 Astra 9.6%, Muse Wonder Full 9.0%, Claude Fable 5.1 8.5%, GPT 6.1 Sol 8.4%, Claude Sonnet 5.5 8.2%
  • Lower tier and open weights: DeepSeek 4.1 Flash 1017 5.4%, GPT-6 Luna 5.1%, Grok 4.7 3.9%, GLM 5.3 2.7%; almost every model scores 0 on finance and legal
  • Method: each model runs in its native harness where one exists (Claude Code for Opus, Codex for Astra, Antigravity for Carbon), otherwise OpenCode; the headline is pass@1 over three attempts with all domains weighted equally (SemiAnalysis blog)
  • By domain: Opus 5.5 wins quant trading, hardware and chip design; Gemini 4 Carbon wins biology and software engineering; GPT-6 Astra wins RSI and materials science; Muse Wonder Full is the strongest cyber model
Read full story

Artificial Analysis releases AA-Omniscience v1.1: 3,000 refreshed questions and a calibrated 300-question public set, with Gemini 4 Carbon leading at a Net Score of 54

On October 31, independent evaluator Artificial Analysis released AA-Omniscience v1.1, its knowledge and hallucination benchmark and part of Intelligence Index v5. The question set shrinks from 6,000 to 3,000, dropping previously public and saturated questions, fixing errors and ambiguities, and adding new ones, and a new 300-question public set on Hugging Face is calibrated to the private set's difficulty, with 0.99 Pearson and Spearman correlation on Net Score. Gemini 4 Carbon (high) leads with a Net Score of 54, ahead of Claude Opus 5.5 at 48 and Claude Fable 5.1 at 46; Fable 5.1 has the highest accuracy (68%) and Gemini 4 Argon the lowest hallucination rate (4%). Models score about 1.9 points lower than on v1 on average, and MiniMax M3.1 Flash drops 22 points. All figures are as reported by Artificial Analysis.

Artificial Analysis releases AA-Omniscience v1.1: 3,000 refreshed questions and a calibrated 300-question public set, with Gemini 4 Carbon leading at a Net Score of 54

Key Takeaways

  • The question set shrinks from 6,000 to 3,000 across 6 domains and 42 topics: 600 each for science/engineering/math and software engineering, 450 each for finance, health, humanities/social sciences and law
  • A new 300-question public set is on Hugging Face, with 0.99 correlation to private-set Net Score and a median difference of 0.0 points
  • Net Score ranking: Gemini 4 Carbon (high) 54, Claude Opus 5.5 48, Claude Fable 5.1 46; the best open-weights model, Muse Spark Open, trails Gemini 4 Carbon by 28 points
  • Claude Fable 5.1 has the highest accuracy (68%), followed by Claude Opus 5.5 (66%); Gemini 4 Argon has the lowest hallucination rate (4%)
  • Rank order keeps a 0.98 Spearman correlation with v1, but scores are 1.9 points lower on average; MiniMax M3.1 Flash falls from 16 to -6 and MiMo V2.6 Pro from 8 to -5 (vendor-reported)
Read full story

Nous Research opens the official Hermes Agent mobile beta: iOS via TestFlight, Android via Firebase, connecting your phone to your own gateway to approve tools and manage bots and routines

During NousCon 2026 in New York on Oct 30, Nous Research released an official mobile beta of Hermes Agent and put up a sign-up page at hermes-agent.nousresearch.com/mobile: iOS users join the "Hermes Agent - Mobile" beta through TestFlight, and Android users join through Firebase App Distribution. The TestFlight page says the app connects to your own Hermes gateway so you can chat with streaming, approve tool calls, and manage bots and routines from anywhere. Teknium, co-founder and lead engineer of Hermes Agent, confirmed on X that the iPhone and Android betas launched together. Nous has not announced a general release date or any benchmarks.

Key Takeaways

  • Entry point: the official page hermes-agent.nousresearch.com/mobile covers 2 platforms, iOS through TestFlight and Android through Firebase App Distribution
  • Positioning: the TestFlight description says the app connects to your own gateway for streaming chat, tool-call approval, and managing bots and routines; it is a client, not a separate agent running on the phone
  • Confirmation: Teknium, co-founder and lead engineer of Hermes Agent, confirmed in a reply on X that the iPhone and Android betas both launched on NousCon day
  • Watch for clones: several third-party Hermes phone clients already exist, so only use the links on the official page; Nous has not published a general release date or benchmarks
Read full story

YC Labs pits AI agent swarms in Minecraft and Mindustry: GPT swarms win 12 of 16 head-to-head games against Claude, while a 50-agent colony slides into bureaucracy

YC Labs, a research project at Y Combinator, and multi-agent environment startup Olam Labs published "Agents in Games" on Oct 29. Fifty GPT-6.1 Sol agents told to "build a thriving civilization" in survival Minecraft spent three hours huddled in shelters rationing food, sending about 5,900 messages and inventing ration ledgers, permits and job titles. In nine Bed Wars games, 10 GPT-6.1 Sol agents beat 10 Claude Opus 5.5 agents 6–3; in seven 50-vs-50 Mindustry matches lasting about 9.5 hours, GPT won 6–1. The leader was almost always whichever agent was listed first in the directory, and stuck GPT agents fetched the game's public source code on their own. The Minecraft harness is open source. These are one lab's experimental observations, not a standardized benchmark.

YC Labs pits AI agent swarms in Minecraft and Mindustry: GPT swarms win 12 of 16 head-to-head games against Claude, while a 50-agent colony slides into bureaucracy

Key Takeaways

  • Head-to-head: GPT-6.1 Sol won Bed Wars 6–3 over nine games and Mindustry 6–1 over seven, 12 of 16 overall (see the YC Labs report)
  • Civ50: 50 GPT agents sent about 5,900 messages in three hours; 22 of 34 deaths came on the first night, after which the colony turned cautious
  • No election: 46 of the other 49 agents first messaged Ada, first on the roster, who received 616 DMs and became leader
  • Communication: in one Bed Wars game GPT players sent 1,147 DMs versus Claude's 82; GPT drifted into compressed shorthand while Claude voted with "+1"
  • Open source: the long-running Minecraft agent harness is public at yc-software/minecraft-agent-harness
Read full story

Kaggle and IBM Research launch the ScarfBench Java migration leaderboard: Gemini 4 Argon with Antigravity leads at 75.2%, and about 72% of failures happen at runtime

Kaggle announced ScarfBench with IBM Research, a 204-task benchmark that tests whether coding agents can migrate enterprise Java apps between Jakarta EE, Quarkus and Spring without changing behavior. IBM's October 27 technical note shows Gemini 4 Argon with Antigravity first on the smoke score at 75.2%, Claude Opus 5.5 with Claude Code highest on all-tests-pass at 72.1%, and GPT-6.1 Sol with Codex cheapest at $1.25 per solved task.

Kaggle and IBM Research launch the ScarfBench Java migration leaderboard: Gemini 4 Argon with Antigravity leads at 75.2%, and about 72% of failures happen at runtime

Key Takeaways

  • 204 migration tasks and 10 model-plus-harness configurations; top smoke scores are Gemini 4 Argon + Antigravity 75.2%, Claude Opus 5.5 + Claude Code 70.5% and Claude Opus 5 + Claude Code 69.8% (IBM figures)
  • Claude Opus 5.5 + Claude Code has the highest all-tests-pass rate at 72.1%, just ahead of Gemini 4 Argon at 71.1%
  • Compiling is mostly solved: 8 of 10 configurations compiled at least 97% of solvable tasks, yet smoke scores spanned more than 50 points
  • 535 of 745 classified failing runs (about 72%) were runtime behavioral failures, including 210 lost-route/404 failures
  • Cost per solved task: $1.25 for GPT-6.1 Sol + Codex, $1.59 for Gemini 3.8 Flash + mini-swe and $10.10 for Claude Opus 5.5 + Claude Code; public submissions are not open yet
Read full story

Perplexity CEO shares early Gemini 4 Carbon evals: a record 0.857 on the WANDR deep-research benchmark at $5.86 per task, ahead of Argon and GPT-6 Astra

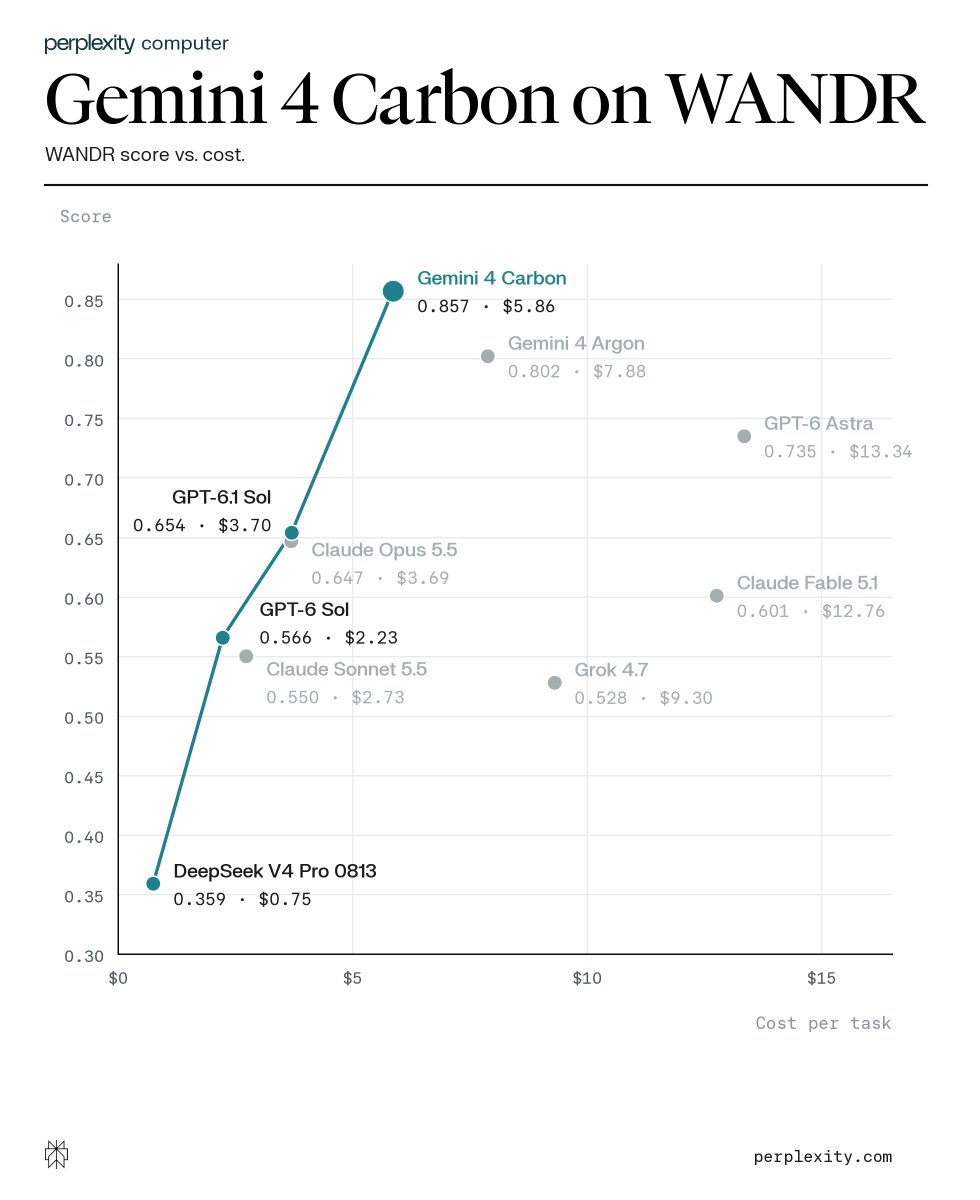
Perplexity CEO Aravind Srinivas posted early evals of Gemini 4 Carbon on X: it scored a record 0.857 on Perplexity's Wide-And-Deep-Research (WANDR) long-form research benchmark at $5.86 per task, versus 0.802 ($7.88) for Gemini 4 Argon and 0.735 ($13.34) for GPT-6 Astra. He called Carbon the strongest model Perplexity has seen for long-form research and answer quality, and said it will come to all Pro and Max users inside Perplexity Computer once there is enough token capacity.

Perplexity CEO shares early Gemini 4 Carbon evals: a record 0.857 on the WANDR deep-research benchmark at $5.86 per task, ahead of Argon and GPT-6 Astra

Key Takeaways

  • WANDR scores (per Perplexity): Gemini 4 Carbon 0.857, Gemini 4 Argon 0.802, GPT-6 Astra 0.735, GPT-6.1 Sol 0.654, Claude Opus 5.5 0.647, Claude Fable 5.1 0.601
  • Cheaper too: Carbon costs $5.86 per task, below Argon at $7.88 and GPT-6 Astra at $13.34
  • Cost frontier in Perplexity's chart: DeepSeek V4 Pro 0813 (0.359, $0.75), GPT-6 Sol (0.566, $2.23), GPT-6.1 Sol (0.654, $3.70) and Carbon
  • Claude Sonnet 5.5 scored 0.550 ($2.73) and Grok 4.7 scored 0.528 ($9.30)
  • Not live yet: Carbon reaches Perplexity Pro and Max users only once token capacity allows, and Google still limits early access to cyber defenders in its Fairwind program
Read full story
ADSponsored

micro1 releases Dual-Arm Sim, an operating-room robot benchmark: 10 frontier models finished only 11 of 800 trials, and all 213 "task complete" claims were false

AI data company micro1 released Dual-Arm Sim, which has 10 general-purpose frontier models control a two-arm Franka Panda robot in a simulated operating room built on NVIDIA Isaac Sim, using only camera images and robot sensors, across four tasks: swapping instruments, replacing a faulty drug cartridge, passing a sample between hands, and packing a surgical kit. Only 11 of 800 trials were completed, all by Gemini 4 Argon (9) and GPT-6 Astra (2). Models claimed "task complete" in 213 trials and were wrong every time. All 200 traces of the cartridge-swap task are public on Hugging Face.

micro1 releases Dual-Arm Sim, an operating-room robot benchmark: 10 frontier models finished only 11 of 800 trials, and all 213 "task complete" claims were false

Key Takeaways

  • Only 11 of 800 trials finished: Gemini 4 Argon 9 (6/20 cartridge swaps plus 3 surgical kits) and GPT-6 Astra 2; no model completed the instrument swap or the two-arm sample transfer (per micro1)
  • All 213 "task complete" claims were false, and in 94 of them the robot never touched the object; Gemini 3.1 Pro made the claim in 49 of 80 trials
  • Thinking longer did not help: Argon used only 315 tokens per decision and still led; its 9 successes cost $119 in total, while Claude Fable 5.1 spent $839 for none
  • Recovery decided success: Argon and Astra regained a real grasp after a miss in about two-thirds of trials, Grok 4.7 in 3 of 80; first position estimates were a median 33 cm off
  • Lifted faulty cartridges ended on the floor 14 times and on the trolley 11 times, versus only 8 correct swaps
Read full story

Cognition scores Gemini 4 Carbon at 40% on FrontierCode 2.0 for $4.04 a task, near the top, while Gemini 4 Argon gets 26.3% at $6.41

Cognition, the company behind Devin, posted on X at 01:45 UTC on Oct 30 that Google's new Gemini 4 Carbon scores 40% on its FrontierCode 2.0 coding benchmark at $4.04 per task, near the top and behind only Claude Opus 5.5, GPT-6 Astra and Claude Sonnet 5.5. The earlier Gemini 4 Argon scores 26.3% at a higher $6.41 per task. The results are Cognition's own runs, and the leaderboard on its site has been updated.

Cognition scores Gemini 4 Carbon at 40% on FrontierCode 2.0 for $4.04 a task, near the top, while Gemini 4 Argon gets 26.3% at $6.41

Key Takeaways

  • Gemini 4 Carbon scores 40% on FrontierCode 2.0 at $4.04 per task, behind Claude Opus 5.5 (45.5%), GPT-6 Astra (42.8%) and Claude Sonnet 5.5 (post)
  • Gemini 4 Argon scores 26.3% at $6.41 per task, ahead of Muse Wonder 1.0 but behind Claude Haiku 5.5 and Grok 4.7
  • From Argon to Carbon the score rises about 13.7 points while cost per task drops about $2.37
  • The changelog shows Gemini 4 Carbon was added on Oct 28; FrontierCode 2.0 has 132 tasks scored on whether a maintainer would merge the PR (leaderboard)
  • All figures are Cognition's own runs; Google has not published FrontierCode results itself
Read full story

Suhail launches Particle and its first model, Particle-1: a DeepSeek V4.1 Flash post-train that uses about 45% fewer tokens on coding tasks

On Oct 28, Mixpanel founder Suhail Doshi announced his new company Particle on X, with its first model, Particle-1, live now. Particle's blog says it is a reinforcement-learning post-train of DeepSeek V4.1 Flash that uses 28.4% to 52.2% fewer output tokens and costs 34.4% to 51.6% less per task across four coding and data engineering benchmarks, with pass rates inside the base model's confidence intervals. It is available through the Particle API, OpenRouter and Vercel AI Gateway; Particle's docs list $0.25 input and $1.00 output per million tokens with a 1,048,576-token context window.

Suhail launches Particle and its first model, Particle-1: a DeepSeek V4.1 Flash post-train that uses about 45% fewer tokens on coding tasks

Key Takeaways

  • Across four benchmarks (Terminal-Bench 2.1, ReactBench, ADE Bench, DeepSWE 1.1), 28.4% to 52.2% fewer output tokens and 34.4% to 51.6% lower cost per task (vendor-reported)
  • Particle's summary table: $0.2211 per task versus $0.3368 for DeepSeek V4.1 Flash and $0.6523 for GLM 5.3 Flash; 59,580 mean output tokens versus 83,246 and 98,155
  • Task pass rate 72.57% versus 71.15% for the base model and 66.82% for GLM 5.3 Flash; GPQA Diamond 90.40% (base 90.91%), MMLU 86.08% (base 85.98%)
  • Training: a rank-64 LoRA on the experts in all layers, about 1.25% of the model's parameters, trained with sequence-level GSPO in two RL stages
  • Pricing: Particle docs currently list $0.25 input, $0.03 cached input and $1.00 output per million tokens, a 1,048,576-token context and a 131,072-token output ceiling
Read full story

Cognition launches FrontierCode 2.0 coding benchmark: it asks whether a PR should be merged, and top model Claude Opus 5.5 scores just 45.5%

Cognition, the maker of Devin, released FrontierCode 2.0 on Oct 27. It keeps the method of maintainer-written tasks graded on whether the code is actually mergeable, but draws tasks from more repositories, adds security patches and performance work, uses deliberately underspecified prompts and adds many thoroughness criteria. In Cognition's results Claude Opus 5.5 leads at 45.5%, GPT-6 Astra follows at 42.8%, and Grok 4.7 and Gemini 4 Argon drop into the 20s, leaving the benchmark far from saturated.

Cognition launches FrontierCode 2.0 coding benchmark: it asks whether a PR should be merged, and top model Claude Opus 5.5 scores just 45.5%

Key Takeaways

  • Claude Opus 5.5 leads at 45.5% (54.6% on v1.1) and GPT-6 Astra scores 42.8% (53.3% on v1.1), per Cognition (vendor-reported)
  • Grok 4.7 scores 28.6%, Gemini 4 Argon 26.3%, Muse Wonder 1.0 24.3%, SWE-2 23.9%, DeepSeek V4.1 Flash 19.3% and Kimi K3 17.7%, showing a wide gap for open models
  • Versus v1.1, reference solutions touch 67% more files and 89% more lines in codebases 25% larger; tasks come from 55% more repositories with 43% more blocking criteria
  • Thoroughness blockers grew from 168 to 501, about 3x; in 80% of tasks the reference solution improves on the upstream PR, and an audit agent found and reported an upstream security vulnerability
  • On the cost-score Pareto frontier, Opus 5.5 sits at the high end and Luna, Haiku and Sol at the low-cost end, with GPT-6.1 Sol called out for strong value (official blog)
Read full story

Liquid AI releases LFM3, six open-weight ~2B models spanning text, vision, audio, omni and decision tasks

On Oct 27 Liquid AI released LFM3, a new generation of foundation models built on a tri-hybrid architecture of gated short convolutions, sliding-window attention and global attention, pre-trained on 22T tokens. The first six models all branch from LFM3-1.7B-Base at around 2B parameters, with weights on Hugging Face under the LFM Open License v1.0. Liquid says the text model LFM3-1.7B needs about 1 GB at 4-bit, supports 256K context and beats models several times its size on several agent benchmarks.

Liquid AI releases LFM3, six open-weight ~2B models spanning text, vision, audio, omni and decision tasks

Key Takeaways

  • Six models: LFM3-1.7B (text), VL-2B (vision/video), Audio-2B, Omni-2B, plus decision models d1-2B and d1-Omni-2B
  • Architecture: of 24 layers, 13 gated short convolutions, 5 sliding-window attention (256-token window) and 6 global attention; 22T pre-training tokens
  • Vendor-reported: LFM3-1.7B scores 43.40 on SWE-bench Verified (OpenCode) vs 41.20 for Qwen3.5-4B and 51.20 for Qwen3.5-9B
  • Vendor-reported: 38.42 on WebArena-Verified and 41.29 on AutomationBench, both above Qwen3.5-9B (28.94 / 15.10)
  • A full 128K context needs about 1.6 GB of KV cache; one B300 with SGLang can produce about 3.6B tokens per day (vendor figure)
Read full story
Linked Models & Agents:
⚡ LFM3-1.7B⚡ LFM3-VL-2B⚡ LFM3-Audio-2B⚡ LFM3-Omni-2B⚡ d1-2B⚡ d1-Omni-2B⚡ Qwen3.5-9B⚡ Gemma 4 E4B🤖 Hermes Agent🤖 OpenClaw🌐 Liquid AI🌐 AMD🌐 Qualcomm🌐 Hugging Face