AI Coding Live News

Artificial Analysis: Tencent Hy4 Scores 35 on Intelligence Index v5, Ranked No.2 Among China Labs, 31% on FrontierCode 2.0

Independent evaluator Artificial Analysis published Tencent Hunyuan Hy4 results on the Intelligence Index v5 on November 5 (08:28 UTC): a composite score of 35, tying Grok 4.7 (xhigh) and one point behind Claude Haiku 5.5 (max). Among China-based labs it ranks second only to Kimi K3.1 Pro (46). On agentic coding it scores 31% on FrontierCode 2.0 and 37% on Terminal-Bench 4.0; cost per Intelligence Index task is about $0.78, roughly one-tenth of same-score Grok 4.7.

Artificial Analysis: Tencent Hy4 Scores 35 on Intelligence Index v5, Ranked No.2 Among China Labs, 31% on FrontierCode 2.0

Key Takeaways

  • Intelligence Index v5 composite 35: ties Grok 4.7 (xhigh), one point behind Haiku 5.5 (max, 36); No.2 China-lab model behind Kimi K3.1 Pro (46)
  • FrontierCode 2.0 at 31% (leads China labs; DeepSeek V4.1 Flash 1017 max 28%, Kimi K3.1 Pro 25%); Terminal-Bench 4.0 at 37%
  • AA-Omniscience v1.1 accuracy 50% but hallucination rate 89% (Kimi K3.1 Pro hallucination 37%); HLE-Diamond 33%
  • About $0.78 per Intelligence Index task: ~10x cheaper than same-score Grok 4.7, ~13x cheaper than Qwen3.8 Max (34), nearly 2x Haiku 5.5
  • Pricing about $0.834/$2.501 per 1M input/output tokens, cache reads $0.042; 1M context; text and image input
Read full story

Tencent Releases Hy4: First Hy Model With Vision and Computer Use, Live on Tencent Cloud and OpenRouter, Open Weights Planned

On November 4, Tencent Hy published Hy4 on its official site. Versus Augusts Hy4 preview, Tencent says it scaled up pre-training and post-training, added vision for the first time, added computer use across CLI and GUI, and trained specifically on Blender, CAD and engines like Unreal, Unity and Godot. Hy4 is live on Tencent Cloud and OpenRouter (tencent/hy4, 1M context) at the same API price as the preview. Weights and a system card are promised soon, and a cheaper Hy4 flash is coming.

Key Takeaways

  • Official blog: Introducing Hy4, dated 2026-11-04; the Tencent Hy transparency center also lists V1.0 Hy4
  • Two firsts: vision (fine-grained image detail, complex charts, math visual reasoning) and computer use (CLI plus GUI, with targeted training on Blender, CAD and long cross-app workflows)
  • Tencent's own evals: on 579 real finance tasks rated by 213 finance professionals Hy4 scores 3.04, first among open-weight models (DeepSeek-V4.1-Flash-1017 2.97, Kimi K3.1 Pro 2.68, GLM-5.3 2.68); GameDev +19.1%, GameLogic +9.8%; internal search hallucination rate 15.76% to 5.45%
  • Same API price as the preview: $0.042 cached input, $0.834 input, $2.501 output per million tokens; the OpenRouter page currently shows 50% off ($0.417/$1.251), 1,048,576 context and up to 65,536 output tokens
  • Weights are not out yet: Tencent says it will open-source them with a full system card, working with vLLM and SGLang; Hy4 flash is due soon
Read full story
Linked Models & Agents:
⚡ Hy4⚡ Hy4 preview⚡ Hy4 flash🤖 CodeBuddy🤖 WorkBuddy🌐 Tencent

X discussion: Scott Alexander's "Against SURA" criticizes the "stop unilaterally and raise awareness" line, as AI safety is accused of acting like a mass political movement

On October 31, Scott Alexander published "Against SURA" on LessWrong. He uses SURA (Stop Unilaterally + Raise Awareness) for the view that AI companies, their employees and countries should halt AI work on their own and focus on raising awareness, and argues it would hand the lead to companies that do not prioritize alignment and cost the US its bargaining chip with China. He cites AI Futures Project members' survival estimates for scenarios without a global pause, mostly in the 25%-50% range, to push back on 90%+ doom estimates. Blogger jessicat quoted it and said parts of AI safety now behave like a mass political movement with bad epistemics (about 359 likes, 63K views); Bloomberg Odd Lots co-host Joe Weisenthal summed it up as people competing to out-doom each other (about 287 likes, 38K views). This is an opinion debate, not a policy announcement from any organization.

X discussion: Scott Alexander's "Against SURA" criticizes the "stop unilaterally and raise awareness" line, as AI safety is accused of acting like a mass political movement

Key Takeaways

  • Source: Scott Alexander's "Against SURA" on LessWrong, posted 2026-10-31 19:32 UTC; SURA stands for Stop Unilaterally + Raise Awareness
  • AI Futures Project members' survival estimates for three no-global-pause scenarios (C+ / C / D), as cited: Daniel Kokotajlo 40%/20%/10%, Ryan Greenblatt 60%/63%/55%, Eli Lifland 50%/45%/32%, Thomas Larsen 45%/35%/20%, Romeo Dean 40%/35%/20%; the AI forecaster FutureSearch gave 44%
  • He says that if the US unilaterally passed Sanders' "Ban Artificial Superintelligence Act" (endorsed by MIRI), the AI forecaster he asked put the chance of China agreeing to a pause within a year at only 7%, up from 1%
  • jessicat's quote post (Oct 31, 23:01 UTC) has about 359 likes, 28 reposts and 63K views; Joe Weisenthal's quote (Nov 1, 14:57 UTC) has about 287 likes, 33 replies and 38K views
  • Note: the "10-40%" in Weisenthal's post is his paraphrase; the estimates in the essay's table range from 10% to 63%
Read full story
Linked Models & Agents:

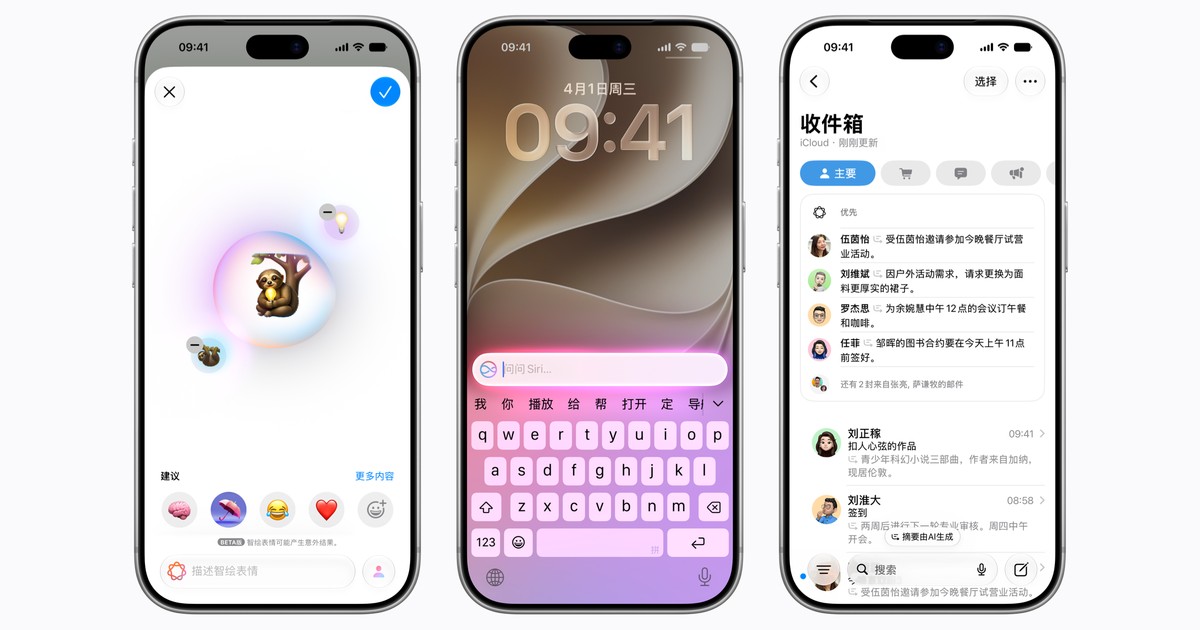
Apple Intelligence is coming to China: iOS 27.3 developer beta starts Nov 4, public release in December, with Alibaba Qwen inside Siri, Writing Tools and Visual Intelligence

In a press release on its China newsroom, Apple said the first Apple Intelligence features will open for testing in the latest iOS developer beta starting November 4 and reach users in China with the iOS 27.3 release in December. The features run on Apple-built generative models and include Live Translation, Writing Tools, Visual Intelligence, Clean Up, Genmoji, notification and Mail summaries, and Type to Siri; Apple also partnered with Alibaba to bring Qwen into Siri, Writing Tools and Visual Intelligence. The first wave covers iPhone 15 Pro and newer only; Siri AI and the other next-generation features announced at WWDC 2026, plus Image Playground, are not included, and Mac, iPad and other platforms wait on further approvals.

Apple Intelligence is coming to China: iOS 27.3 developer beta starts Nov 4, public release in December, with Alibaba Qwen inside Siri, Writing Tools and Visual Intelligence

Key Takeaways

  • Timeline (Apple): testing in the latest iOS developer beta from November 4, public rollout with iOS 27.3 in December, no exact date given
  • First-wave features include Live Translation (Messages, FaceTime, Phone and AirPods), Writing Tools, Visual Intelligence, Clean Up, Genmoji, natural-language photo search, Priority Mail, notification summaries and Type to Siri
  • Alibaba Qwen is built into Siri, Writing Tools and Visual Intelligence: users can ask about photos, PDFs and presentations and use Qwen to compose original text, signing in with a Qwen account or Sign in with Apple
  • Supported devices: iPhone 16 and later, iPhone Duo, iPhone 15 Pro/Pro Max and iPhone Air, with Siri and device language set to English and Simplified Chinese
  • Siri AI and other next-generation WWDC 2026 features are excluded, MacRumors says Image Playground is also missing, and other platforms follow after the necessary approvals
Read full story
Linked Models & Agents:
⚡ Qwen⚡ Apple Foundation Models🤖 Siri🌐 Apple🌐 Alibaba
ADSponsored

CrowdStrike: China-nexus VAPOR PANDA used the ARTEX multi-agent framework, mainly on DeepSeek, against 200+ organizations in 11 days

CrowdStrike reported on Oct 29 that the China-nexus espionage group VAPOR PANDA, starting Oct 17, ran the open-source agentic intrusion framework ARTEX with DeepSeek plus a second, unconfirmed commercial LLM, hitting more than 200 organizations in at least 14 countries from a single controller over 11 days. Post-exploitation was confirmed at nine organizations, where the BLOODALCHEMY backdoor was deployed. Planning agents used about 1.4 billion input tokens in a single intrusion, and recovered transcripts show a human operator steering the agents in Chinese at key decision points.

Key Takeaways

  • Over 11 days from Oct 17, one ARTEX controller targeted 200+ organizations in at least 14 countries, including several foreign ministries, 19 US pharma, semiconductor, defense, nuclear and finance organizations, and telecoms in the US, Belgium and the Philippines (CrowdStrike report)
  • Post-exploitation was confirmed at 9 organizations, which received the BLOODALCHEMY backdoor; at least 12 more saw password spraying and credential scanning
  • DeepSeek was the main model, plus a subscription commercial LLM CrowdStrike could not confirm; planning agents used about 1.4 billion input tokens in one intrusion
  • Recovered transcripts show an operator issuing Chinese instructions tagged as human instructions, including an order to find Windows hosts without the Falcon sensor
  • CrowdStrike says this is separate from the Storm-0940 ARTEX activity reported by Microsoft, and judges China-nexus groups will highly likely keep adopting such agent frameworks over the next 12 months
Read full story
Linked Models & Agents:

Symantec finds a grey-market relay that installs the real Codex and Claude Code CLIs, then turns off sandboxing and routes every request through its own servers

On Oct 29 Symantec's Threat Hunter Team disclosed an unauthorized AI relay seen at about a dozen organizations since early 2026, mostly in mainland China. Users install the genuine Codex or Claude Code CLI via npm, then run a one-line script from the reseller that rewrites ~/.codex/config.toml or ~/.claude/settings.json, points base_url at relay domains, swaps in relay-issued keys, sets the sandbox to danger-full-access and disables telemetry. Symantec says this is not a CLI vulnerability and it has seen no abuse so far.

Symantec finds a grey-market relay that installs the real Codex and Claude Code CLIs, then turns off sandboxing and routes every request through its own servers

Key Takeaways

  • About a dozen affected organizations, mostly in mainland China, plus Chinese or home-market units of South Korean, Taiwanese and Malaysian firms in semiconductors, electronics, pharma, shipping and petrochemicals
  • A one-line iwr | iex or curl | bash command fetches a fileless script from lookalike domains such as vibe.aiok[.]me, installs the genuine CLI, then rewrites its config, so it looks like a normal setup step
  • The Codex sandbox is set to danger-full-access with network access on, and DISABLE_TELEMETRY=1 and DISABLE_ERROR_REPORTING=1 are set
  • Relay-issued Claude Code keys use the sk-ant-oat01- prefix of subscription OAuth tokens, which Symantec says is consistent with, but not proof of, pooled subscription resale
  • Symantec says this is not a vulnerability in Codex or Claude Code and it has no evidence the operator has abused its access; the risks are potential
Read full story

Apple ships 27.2 updates: Siri AI adds French, Japanese, Korean, Portuguese and Spanish, and can now recall past conversations

On Oct 26 Apple released iOS, iPadOS, macOS, watchOS and visionOS 27.2, and Siri AI (beta), the assistant rebuilt on Apple Intelligence, now supports French, Japanese, Korean, Portuguese and Spanish in addition to English. Apple says Traditional Chinese, Norwegian, Turkish and Vietnamese will follow by the end of the year. Per the iOS 27.2 release notes, Siri AI can now recall past conversations and draw on more sources such as photos in Messages, Calendar attendees and voicemails. Siri AI is still unavailable in the EU on iOS, iPadOS and watchOS and in mainland China, and server-side features have daily usage limits; Apple says expanded access will be offered for a fee in the future.

Apple ships 27.2 updates: Siri AI adds French, Japanese, Korean, Portuguese and Spanish, and can now recall past conversations

Key Takeaways

  • Languages: Siri AI grows from English-only to 6 languages, adding French, Japanese, Korean, Portuguese and Spanish; Apple says Traditional Chinese, Norwegian, Turkish and Vietnamese arrive by year end
  • 5 platforms: iOS, iPadOS, macOS, watchOS and visionOS 27.2 shipped the same day, with Siri AI still labeled beta
  • New abilities (per iOS 27.2 release notes): recall of past conversations, more sources including photos in Messages, Calendar attendees and voicemails, plus one Excluded Apps setting
  • Limits: unavailable on iOS/iPadOS/watchOS in the EU, for mainland China accounts and for users under 13; server-side features have daily caps, and Apple says paid expanded access is coming
  • Devices: Apple Intelligence hardware such as iPhone 15 Pro and later and M1-or-later iPad and Mac, with device and Siri language set to the same supported language
Read full story
Linked Models & Agents:
⚡ Apple Intelligence⚡ AFM 3🤖 Siri AI🌐 Apple
m
mofcom.gov.cnSource·
👀119
🔥82

China proposes export controls on 23 AI technologies: weights of 2T-parameter or global top-10 models restricted, open source and API services exempt

On Oct 16 China's commerce and science ministries proposed adding 40 technologies, 23 of them in AI, to the export ban and restriction catalogue. The draft restricts core technology of models with at least 10^26 training FLOPs, at least 2 trillion parameters, or a global top-10 ranking, and sets step, concurrency and tool-count thresholds for agents. Open-sourced technology is exempt, and API or SaaS services are not treated as technology exports. Temporary pre-export registration took effect the same day; comments close Nov 15.

Key Takeaways

  • 23 AI items out of 40 proposed technologies (14 prohibited, 26 restricted across AI, biomedicine and photovoltaics); comments open Oct 16 to Nov 15, 2026
  • Restricted model thresholds (any one): at least 10^26 training FLOPs, at least 2 trillion parameters, or a global top-10 ranking; covers weights, checkpoints, source code, architecture and training or inference acceleration
  • Agent thresholds include 20 or more sub-task steps with at least 90% average success, 60 or more concurrent agents, or 200 or more integrated tools
  • Open-sourced or published technology is exempt; serving via API, app or web, SaaS, or lightweight on-device deployment is not a technology export, while overseas on-premise deployment is
  • Temporary pre-export registration has applied since Oct 16, including deals already underway
Read full story
Linked Models & Agents:

CrowdStrike: attacker used open-source AI pentest agent ARTEX plus Claude Code to breach South Korean financial firms

CrowdStrike Intelligence found Claude Code session histories, ARTEX configs and a CLAUDE.md in attacker open directories, showing a likely Chinese-speaking, financially motivated actor used the China-built open-source agentic pentest framework ARTEX (DeepSeek v4.1-flash primary, plus GLM-5.3 and Grok 4.6) to breach loan-inquiry and employee mobile systems at South Korean financial institutions from late September to early October 2026.

Key Takeaways

  • Window: late Sep to early Oct 2026; CrowdStrike attribution is moderate confidence, no named adversary
  • Model stack: DeepSeek v4.1-flash as ARTEX primary backend via likely reseller xcai[.]pro; GLM-5.3 and Grok 4.6 in Claude Code sessions
  • IOCs: 1 actor-controlled IP (38.244.50[.]120) plus 9 proxy IPs, with MITRE ATT&CK mapping
  • Reported impact: Shinhan 25,729 customers, Hana 89, Yegaram ~40,000 (press reports)
  • The upstream Autumn-27/ARTEX GitHub repo now returns 404
Read full story

Incremental Open-Ended Deep Research (IOEDR): Tsinghua and RUC Introduce Structured Harness for Autonomous Research Agents, Slashing Searches by 61%

Autonomous deep research agents (such as OpenAI Deep Research and Perplexity) represent a powerful leap toward automated knowledge synthesis. However, on open-ended and comprehensive inquiries, existing agents rely primarily on unconstrained search-and-generate loops. This leads to three systemic failures: redundant query loops, conflicting claims across sections, and runaway token expansion. Researchers from Tsinghua University and Renmin University of China unveil IOEDR (arXiv:2610.11566), a framework for Incremental Open-Ended Deep Research with a Structured Harness. IOEDR models the evolving research report as a dynamic hierarchical state graph coupled with a persistent, deduplicated evidence pool. Rather than executing open-ended browsing, the agent uses structured harness constraints to incrementally plan sections, identify specific evidential gaps, and trigger precision queries with dynamic termination conditions. On DeepResearch Bench, IOEDR achieves superior report coherence and verifiable fact density while reducing total token consumption by 33.2% and slashing search API requests by 61.4%.

Key Takeaways

  • Tsinghua and RUC introduce IOEDR, modeling deep research as an evolving hierarchical state graph coupled with a persistent evidence pool
  • Slashes search API queries by 61.4% and token usage by 33.2% on DeepResearch Bench while eliminating cross-section factual drift
  • Implements information-gain gating with a 92.4% noise rejection rate, establishing an efficient architectural pattern for deep research agents
Read full story
ADSponsored

CheckerBench: ECNU and Peking University Introduce the First Executable Benchmark for Coding Agents Synthesizing Static-Analysis Checkers

Prevailing coding agent benchmarks evaluate isolated patch synthesis (e.g. SWE-bench) or vulnerability detection, neglecting whether agents can construct reusable, production-grade static-analysis checkers from scratch. Developing static analyzers requires interpreting defect specifications, traversing multi-file AST semantics, writing engine-specific logic, and refining implementations through iterative compilation and diagnostic feedback. Researchers from East China Normal University, SJTU, and Peking University unveil CheckerBench (arXiv:2610.07557), an executable suite comprising 300 tasks derived from 297 CVEs across 167 repositories, 85 CWEs, and five programming languages. Powered by the CheckerLab harness, evaluation across 21 model-harness configurations reveals a mean Pass@1 rate of only 32.30% (peak 45.33%), demonstrating that end-to-end program analysis tool synthesis represents a profound new frontier for software engineering agents.

Key Takeaways

  • ECNU, SJTU, and Peking University launch CheckerBench, the first executable benchmark for coding agents synthesizing static analysis checkers
  • Features 300 tasks spanning 297 CVEs and 85 CWEs across C/C++, Go, Java, Python, and Rust with the CheckerLab framework
  • 21 model-harness setups achieve a mean Pass@1 of only 32.30% (peak 45.33%), exposing gaps in compiler-in-the-loop tool synthesis
Read full story

AREX-2 Advances Self-Improving Agents via Long-Horizon Reflective Tasks: Scoring 81.8 on MLE-bench and 92.2 on GAIA

Test-time self-improvement—the ability of an agent to iteratively refine solutions during inference—relies on high-fidelity reflection to surpass current proposals and long-horizon execution to maintain coherent multi-round exploration. Researchers from Renmin University of China, Microsoft Research, and USTC introduce AREX-2, establishing that these capabilities are domain-agnostic and learnable from verifiable environments. Synthesizing long-horizon reflective trajectories across machine learning and algorithmic programming, an AREX-2 agent built on Qwen3.8-27B achieves 81.8 on MLE-bench Lite and 70.7 on Frontier-CS, transferring seamlessly to deep research with 84.0 on BrowseComp, 92.2 on GAIA, and 93.8 on DeepSearchQA while monotonically scaling with compute budget.

AREX-2 Advances Self-Improving Agents via Long-Horizon Reflective Tasks: Scoring 81.8 on MLE-bench and 92.2 on GAIA

Key Takeaways

  • Identifies reflection and long-horizon execution as domain-agnostic foundations for test-time self-improving agents
  • Achieves 81.8 on MLE-bench Lite and 70.7 on Frontier-CS using an AREX-2 Qwen3.8-27B model
  • Transfers zero-shot to deep research benchmarks, scoring 92.2 on GAIA, 93.8 on DeepSearchQA, and 84.0 on BrowseComp
Read full story

Unity Insight: First Production Code-Asset Graph Index for Game-Engine Coding Agents, Slashing Tokens and Time by 52%

Researchers from Unity China and the Tuanjie Engine team introduced Unity Insight (arXiv:2609.27585), a production code-asset graph index natively integrated into the Tuanjie Codely agent CLI. In game-engine repositories, gameplay logic is fundamentally intertwined with serialized YAML assets (.prefab, .unity, .asset) connected via GUIDs rather than raw code imports. Traditional code-only retrievers and ripgrep fail to resolve basic cross-file dependencies. Unity Insight bridges this gap by indexing cross-asset object references and C# fields into typed retrieval tools. In paired experiments across 28 tasks on two commercial Unity games, index-backed agents spent 53% fewer tokens and 52% less wall-clock time compared to baseline exploration agents (p < 0.004).

Unity Insight: First Production Code-Asset Graph Index for Game-Engine Coding Agents, Slashing Tokens and Time by 52%

Key Takeaways

  • Dual code-asset graph: first index bridging C# source files and serialized YAML assets (.prefab, .unity) via Unity GUID tracking
  • 52% time and token reduction: cuts token consumption by 53% and wall-clock execution time by 52% across 28 paired benchmarks (p < 0.004)
  • Production-proven deployment: powers Tuanjie Codely, the official agent CLI for Tuanjie Engine, supporting production game codebases
  • Typed index tools: exposes structured asset-code query primitives, eliminating context window bloat caused by raw YAML dumps
  • Game development breakthrough: provides a standardized blueprint for high-accuracy, low-hallucination agentic refactoring in game studios
Read full story

Renmin University Open-Sources Agent-Editing World Model (AEWM): State-Editing Paradigm for Autonomous LLM Agents

Researchers from Renmin University of China (RUC AI Box, @huggingface) have released the Agent-Editing World Model (AEWM, arXiv: 2609.28416, GitHub: RUCAIBox/Agent-Editing-World-Model). Questioning the dogma that world models must simulate raw high-entropy environment responses, AEWM reframes world modeling around how an agent's reasoning and actions directly drive task progression. Featuring an Action Judge and State Revision pipeline, AEWM's EditAct mechanism directly edits task states under execution feedback, boosting benchmark scores by 3.2 to 6.7 points across search, terminal, and software engineering domains.

Renmin University Open-Sources Agent-Editing World Model (AEWM): State-Editing Paradigm for Autonomous LLM Agents

Key Takeaways

  • Abandons the brittle practice of hallucinating high-entropy tool observations, modeling task state progression instead.
  • Introduces the Action Judge framework, accurately classifying steps into Critical, Exploratory, and Noisy actions.
  • Implements EditAct, actively mutating contaminated conversation contexts rather than issuing passive natural language critiques.
  • Achieves 70.5% Macro-F1 on action verification, lifting downstream multi-turn scores by 3.2-6.7 points across six benchmarks.
  • PyTorch codebase, state-revision datasets, and benchmark harnesses published under MIT license on GitHub.
Read full story

DHH: Alibaba Cloud joins Omacom as founding patron with $3M; Omarchy coming to Qwen Book

DHH (@dhh) announced Alibaba Cloud as a Founding Corporate Patron of the Omacom Foundation: $3 million in funding, collaboration on Omarchy China, and bringing Omarchy to the newly announced Qwen Book. He argues agentic computers need a native agentic OS. Details: omarchy.org news post.

DHH: Alibaba Cloud joins Omacom as founding patron with $3M; Omarchy coming to Qwen Book

Key Takeaways

  • Alibaba Cloud commits $3M as an Omacom Foundation founding corporate patron.
  • Collaboration covers Omarchy China and shipping Omarchy onto the new Qwen Book.
  • Thesis: agentic computers need a native agentic OS (Omarchy).
Read full story
Linked Models & Agents:
⚡ Alibaba Qwen 3.8 Flash🌐 alibaba🌐 Qwen (通义千问)