AI Coding Live News

Cursor adds DeepSeek V4.1 Flash: all four effort levels sit on the CursorBench 4.0 cost frontier, with Max scoring 47.7% at $0.98 per task

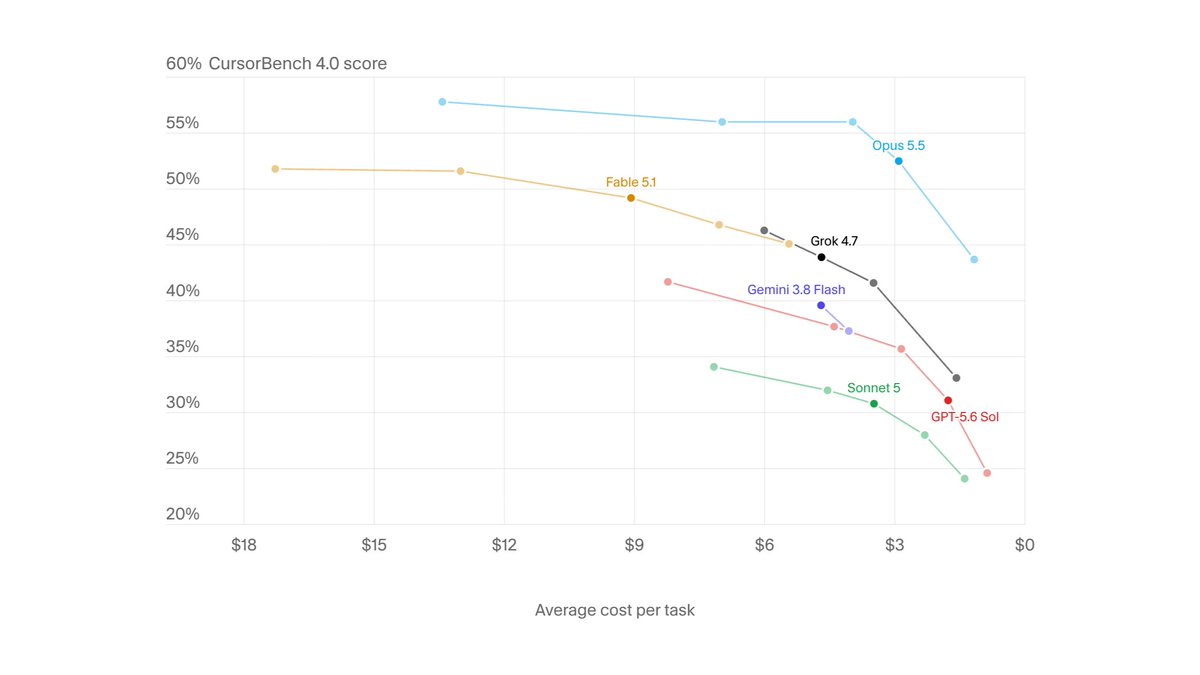
Cursor announced on Oct 26 (UTC) that DeepSeek V4.1 Flash is now available in Cursor and can be turned on under Cursor Settings > Models. Cursor says every effort level sits on the CursorBench cost frontier, from $0.60 to $0.98 per task, with no model scoring higher at those prices. The official CursorBench 4.0 leaderboard lists DeepSeek V4.1 Flash 1017 at 47.7% on Max ($0.98 per task), 46.3% on Medium ($0.80), 45.6% on High ($0.77) and 44.9% on Low ($0.60). The top score on the board, Opus 5.5 Max, is 57.8% but costs $13.43 per task.

Cursor adds DeepSeek V4.1 Flash: all four effort levels sit on the CursorBench 4.0 cost frontier, with Max scoring 47.7% at $0.98 per task

Key Takeaways

  • Four effort levels on the official CursorBench 4.0 board: Max 47.7% at $0.98, Medium 46.3% at $0.80, High 45.6% at $0.77, Low 44.9% at $0.60; Max ranks 17th overall
  • Value: Max at 47.7% nearly ties Sonnet 5.5 High (47.8%, $1.20) for about 18% less; Opus 5.5 Max scores about 10 points higher but costs $13.43 per task, roughly 13.7x more
  • Nearest rivals on price: Haiku 5.5 Max at 48.4% for $1.12 and Haiku 5.5 Extra High at 44.3% for $0.56, bracketing DeepSeek's price range
  • The trade-off is tokens and steps: Max averages about 537K tokens and 187 steps per task, versus about 37K tokens and 41 steps for Sonnet 5.5 High, so expect longer runs
  • Turn it on under Cursor Settings > Models; a counterintuitive detail is that Medium (46.3%) scores slightly above High (45.6%) for only $0.03 more
Read full story

Meta Muse Wonder and Wonder Full frontier agent models (Active Memory, Active Focus); Muse Wonder now in Cursor at 46.1% CursorBench, $4/$20

On 2026-10-12 Meta introduced Muse Wonder and Muse Wonder Full, its most capable models yet for personal and professional agentic work. Official posts highlight Active Memory (carry and retrieve what matters across conversations) and Active Focus (persist through hard tasks, recover from errors, clarify and confirm before consequential actions). Muse Wonder is available today via the Meta Model API and Muse Code; Muse Wonder Full is available today for Muse Code subscribers. Third-party Artificial Analysis Intelligence Index (max reasoning) lists Wonder Full at 56 and Wonder at 52 (Spark 1.3 Max was 48). Update Oct 16: Muse Wonder is now in Cursor with 300k context (1M Max Mode at the same rates), $4/$20 per million tokens, and 46.1% on CursorBench per Cursor.

Meta Muse Wonder and Wonder Full frontier agent models (Active Memory, Active Focus); Muse Wonder now in Cursor at 46.1% CursorBench, $4/$20

Key Takeaways

  • Announced 2026-10-12 via Meta Newsroom and @AIatMeta (official post)
  • Availability (Meta): Muse Wonder on Meta Model API + Muse Code; Muse Wonder Full for Muse Code subscribers only
  • Core mechanisms: Active Memory + Active Focus for long-horizon personal/professional agents
  • Third-party AA Intelligence Index (max): Wonder Full 56, Wonder 52 vs Spark 1.3 Max 48 (changelog)
  • Now in Cursor (2026-10-16): muse-wonder-1.0, 300k / 1M Max Mode at same rates, $4/$20 per M tokens; Cursor reports 46.1% CursorBench at default effort (Cursor docs)
Read full story

Anthropic launches Claude Sonnet 5.5: Terminal-Bench 70.6%, 30%+ faster output, same $2/$10 price with lower task cost

Anthropic released Claude Sonnet 5.5 on 2026-09-28 (API id claude-sonnet-5-5), the second Claude 5.5-family model. Vs Sonnet 5: Terminal-Bench 4.0 70.6% (from 10.3%), CursorBench 4.0 55.5%, GDPval-AA near Opus 5.5; 30%+ faster output and up to ~30% lower task cost at the same $2/$10 pricing. Native 1M context; adaptive thinking on by default — use between_tools to disable up-front thinking.

Anthropic launches Claude Sonnet 5.5: Terminal-Bench 70.6%, 30%+ faster output, same $2/$10 price with lower task cost

Key Takeaways

  • Shipped 2026-09-28 — model id claude-sonnet-5-5 (announcement)
  • Terminal-Bench 4.0 70.6% (vs Sonnet 5 10.3%); CursorBench 4.0 55.5%; GDPval-AA 1844
  • Same $2/$10 pricing; ~30%+ faster output; up to ~30% lower task cost via fewer tokens
  • 1M context / 128K max out; adaptive thinking default; between_tools turns off up-front thinking
  • Migrate via docs; anthropic-sdk-python ≥1.9.0; Claude Code ≥2.1.284 sonnet alias → 5.5
Read full story

Claude Opus 5.5 is now available in Cursor

Cursor announced that Claude Opus 5.5 is now available. It is the new top model on CursorBench at 57.8% (Max) and costs 40% less per task than Opus 5.

Claude Opus 5.5 is now available in Cursor

Key Takeaways

  • Cursor announced that Claude Opus 5.5 is now available. It is the new top model on CursorBench at 57.8% (Max) and costs 40% less per task than Opus 5.
Read full story
Linked Models & Agents:
ADSponsored

Cursor ships Claude Opus 5.5: tops CursorBench at 57.8% (Max), ~40% cheaper per task than Opus 5

Cursor (@cursor_ai) announced Claude Opus 5.5 is available in Cursor. Officially it is the new top model on CursorBench at 57.8% (Max) and costs about 40% less per task than Opus 5, wiring Anthropic’s same-day Opus 5.5 launch into a leading AI IDE.

Cursor ships Claude Opus 5.5: tops CursorBench at 57.8% (Max), ~40% cheaper per task than Opus 5

Key Takeaways

  • Cursor integrates Claude Opus 5.5 day-one across Composer and Chat.
  • Sets a new high score on CursorBench (Max) at 57.8%, boosting multi-file editing precision.
  • Delivers ~40% lower cost per coding task with over 30% faster token generation.
Read full story

Claude Fable 5.1 is now available in Cursor

Cursor announced that Claude Fable 5.1 is now available. It is the most capable model they have run on CursorBench 3.2, scoring 73.4% at max effort, and is especially skilled at verifying its own work on difficult coding tasks.

Key Takeaways

  • Cursor announced that Claude Fable 5.1 is now available. It is the most capable model they have run on CursorBench 3.2, scoring 73.4% at max effort, and is especially skilled at verifying its own work on difficult coding tasks.
Read full story
Linked Models & Agents:

Claude Fable 5.1 and Mythos 5.1 Launch for Coding and Knowledge Work

Anthropic introduced Claude Fable 5.1 and Claude Mythos 5.1, calling them the world’s most advanced models for coding and knowledge work. Fable 5.1 is built for long-running agentic tasks and research, with cache reads 75% cheaper than Fable 5—about 25% lower cost on typical workloads and up to 45% on highly agentic ones. Cursor reported 73.4% on CursorBench 3.2 at max effort.

Key Takeaways

  • Fable 5.1 is generally available; Mythos 5.1 is limited to trusted cyberdefense and life-science access
  • Cache-read pricing down 75%, cutting agentic workload cost by up to 45%
  • Immediately live in Cursor and GitHub Copilot for long-horizon coding and research
Read full story

Cursor Ships Claude Fable 5.1, a New CursorBench High of 73.4%

Cursor said Claude Fable 5.1 is live and is the strongest model it has run on CursorBench 3.2, scoring 73.4% at max effort. The team highlighted its skill at verifying its own work on hard, end-to-end coding tasks. GitHub Copilot also made the model generally available the same day.

Key Takeaways

  • 73.4% at max effort on CursorBench 3.2, the best result Cursor has recorded
  • Strong at self-verification, enabling difficult coding jobs to be taken from start to finish
  • GitHub Copilot GA in the app, CLI, and VS Code for long-running coding, codebase research, and agentic workflows
Read full story

Anthropic Launches Claude Fable 5.1, the World's Most Advanced Coding Model

Anthropic launched Claude Fable 5.1 and the restricted Mythos 5.1, calling them the world's most advanced models for coding and knowledge work. Fable 5.1 scores 55.8% on Terminal-Bench 4.0 (vs. 42.0% for Fable 5) and more than doubles Fable 5 on Terminal-Bench-Science 0.1 at 52.6%. Cache reads are 75% cheaper, cutting typical cost about 25% and highly agentic workloads by up to 45%. It is already live in Cursor (73.4% on CursorBench 3.2) and GitHub Copilot.

Key Takeaways

  • Fable 5.1 is built for long-running coding, deep codebase research, and complex agentic workflows, with fewer false refusals
  • Cheaper cache reads cut agentic cost by up to 45%, and lower-effort settings can match prior peak quality
  • Mythos 5.1 is trusted-access only, paired with Enterprise Frontier Safeguards for ZDR-plus monitoring
Read full story

Claude Fable 5.1 Lands in Cursor and Sets a 73.4% CursorBench Record

Cursor made Claude Fable 5.1 available immediately and called it the most capable model it has run on CursorBench 3.2, scoring 73.4% at max effort. The team found it especially skilled at verifying its own work, enabling difficult coding tasks to run start-to-finish inside the agent harness.

Key Takeaways

  • Fable 5.1 is the top model Cursor has run on CursorBench 3.2 at 73.4% max effort
  • Stronger self-verification lets the agent finish hard coding tasks end to end
  • The model is live in Cursor the same day as the Anthropic launch
Read full story
ADSponsored

Anthropic Launches Claude Fable 5.1, a New Peak for Coding and Knowledge Work

Anthropic released Claude Fable 5.1, plus Mythos 5.1 for cyber defenders and life scientists. Fable 5.1 scores 55.8% on Terminal-Bench 4.0 versus 42.0% for Fable 5, more than doubles Terminal-Bench-Science to 52.6%, and is Cursor’s strongest CursorBench 3.2 result at 73.4% max effort. Cache reads are 75% cheaper, cutting typical costs about 25% and highly agentic workloads up to 45%.

Key Takeaways

  • Fable 5.1 is available everywhere today as Anthropic’s most advanced coding and knowledge-work model
  • It sets a new bar on Terminal-Bench 4.0 (55.8%) and more than doubles science-terminal scores
  • Mythos 5.1 ships via trusted access; Enterprise Frontier Safeguards roll out in phases this fall
Read full story

Cursor ships Claude Fable 5.1; tops CursorBench 3.2 at 73.4%

Cursor said Claude Fable 5.1 is now available in the editor and is the strongest model it has run on CursorBench 3.2, scoring 73.4% at max effort. The post highlights strong self-verification, which helps it finish hard coding tasks end to end—an IDE-side landing the same day as the Fable 5.1 launch.

Key Takeaways

  • Fable 5.1 is selectable inside Cursor.
  • 73.4% at max effort on CursorBench 3.2 is Cursor's strongest result so far.
  • Self-verification makes it a fit for end-to-end hard coding tasks.
Read full story