AWS announces TorchNeuron: PyTorch runs natively on Trainium, open-sourcing under Apache 2.0 on October 20
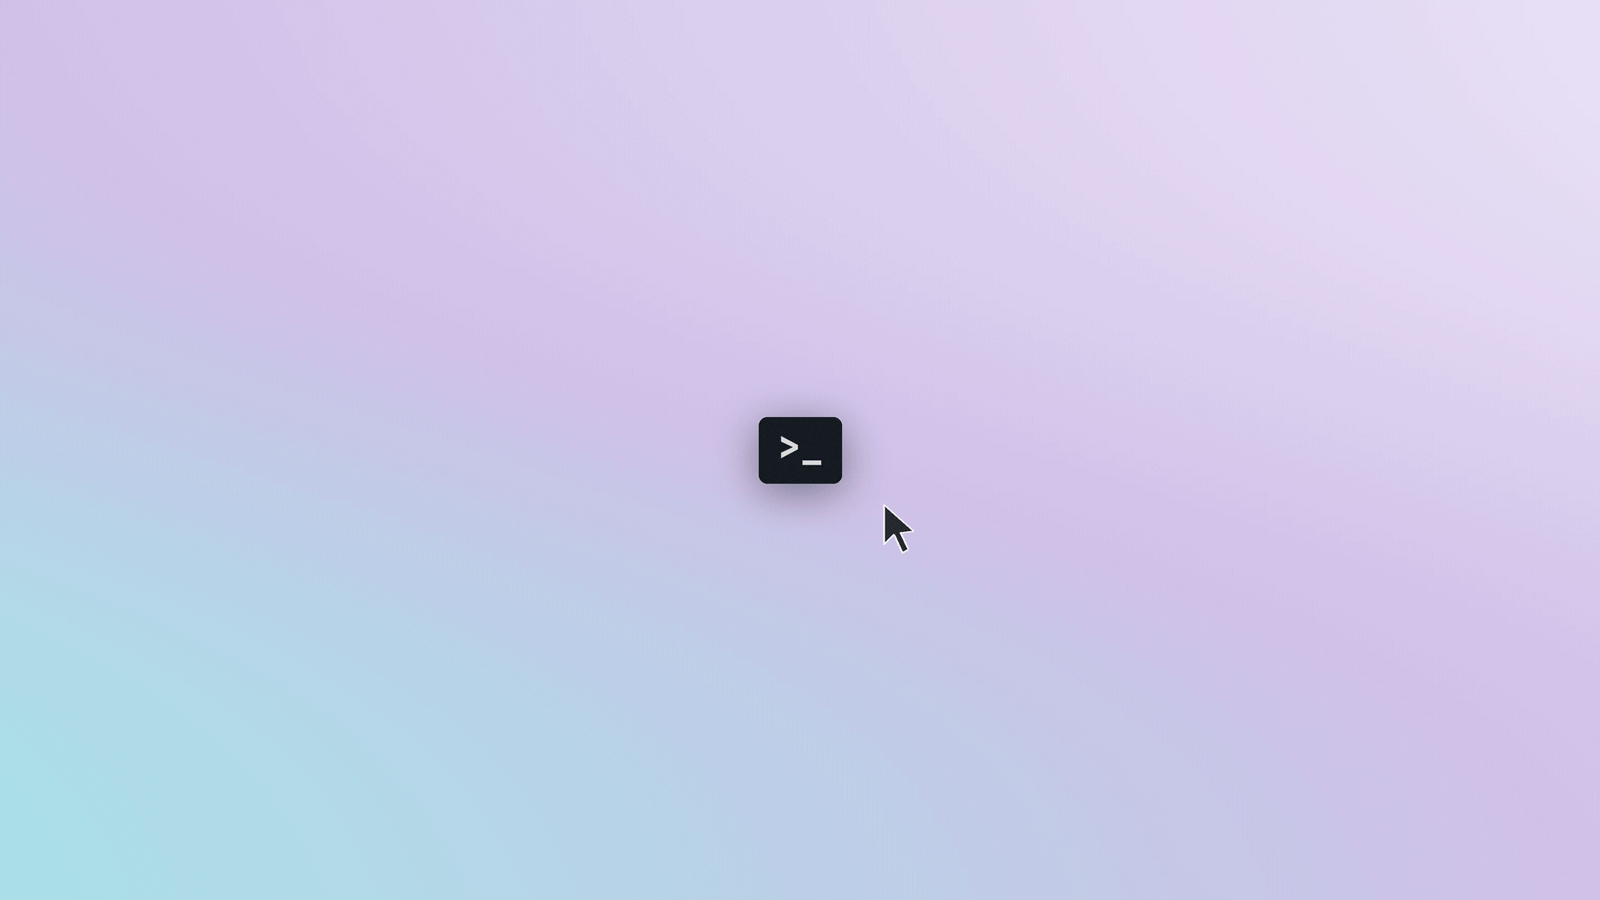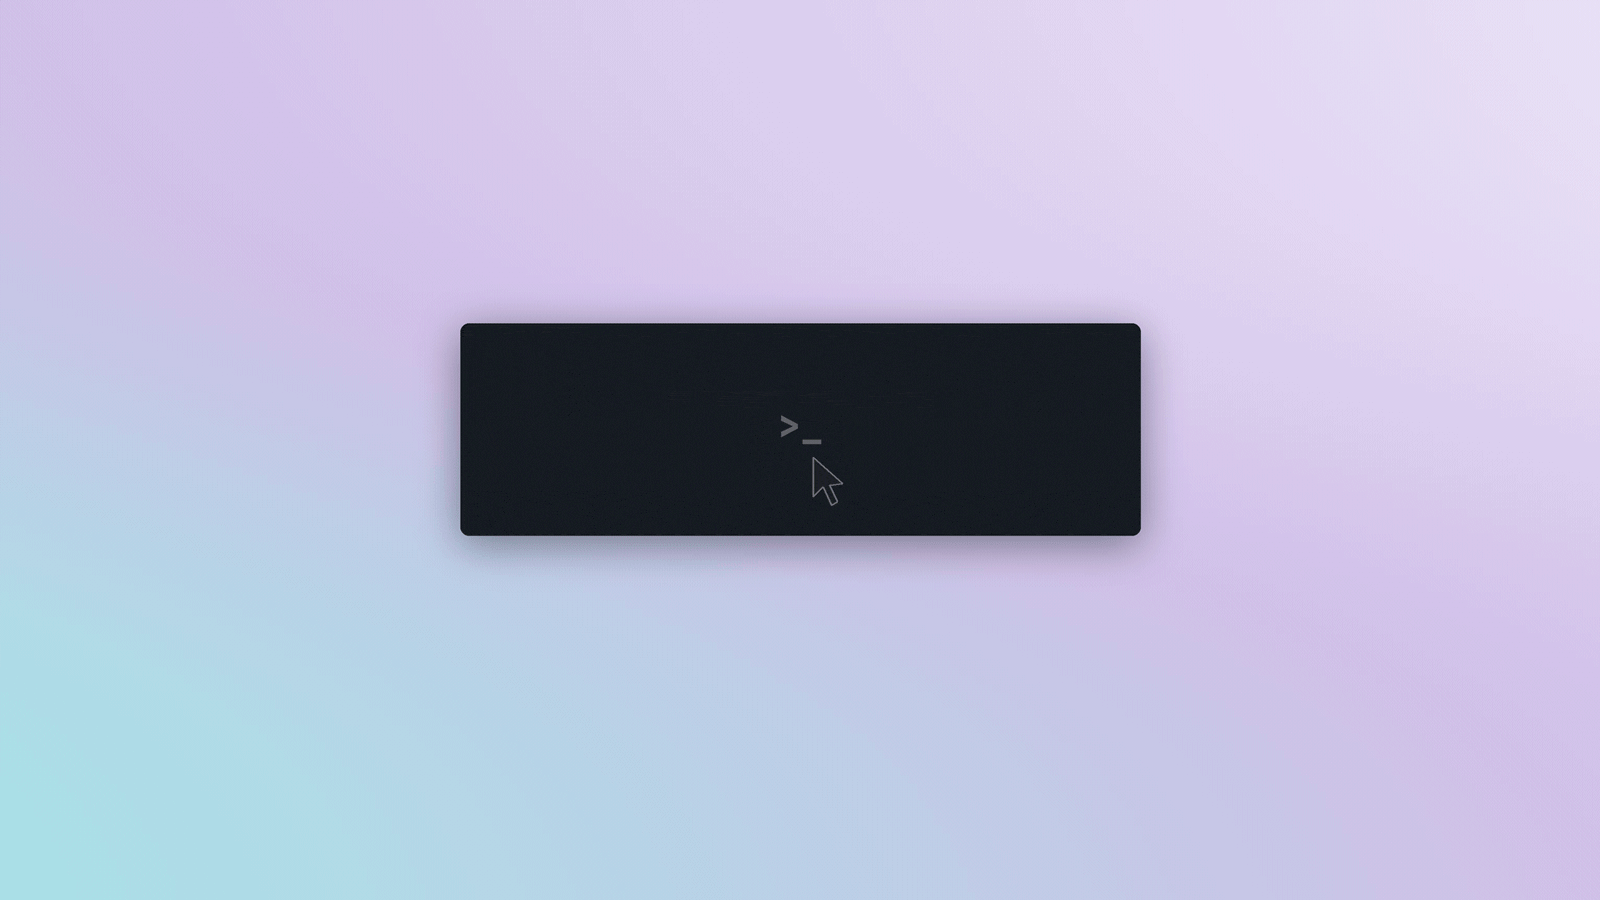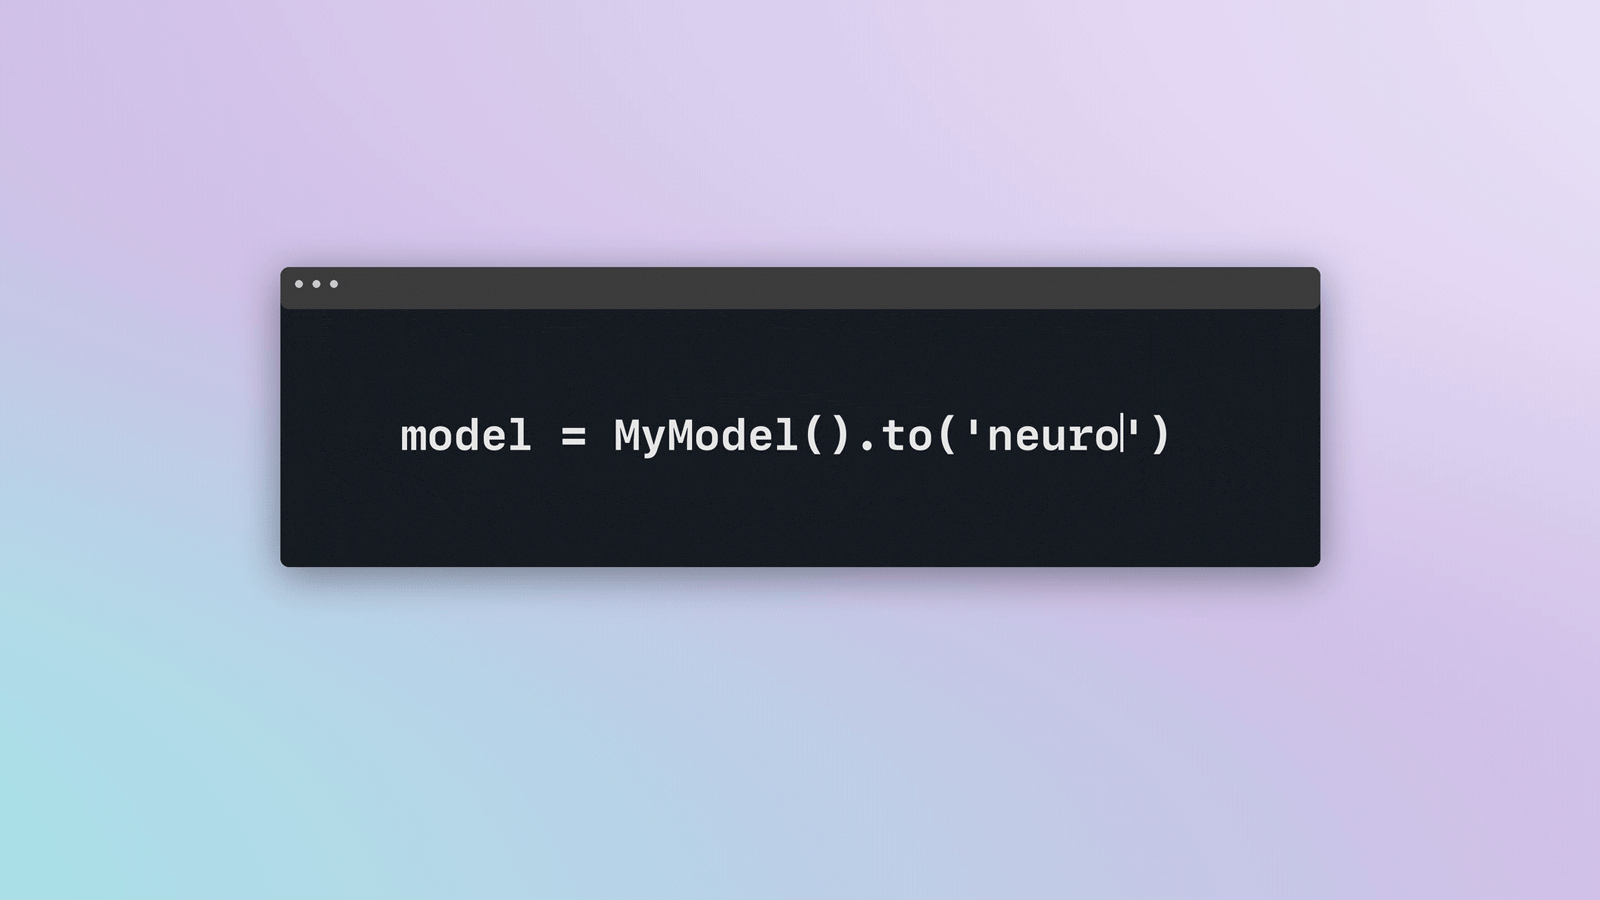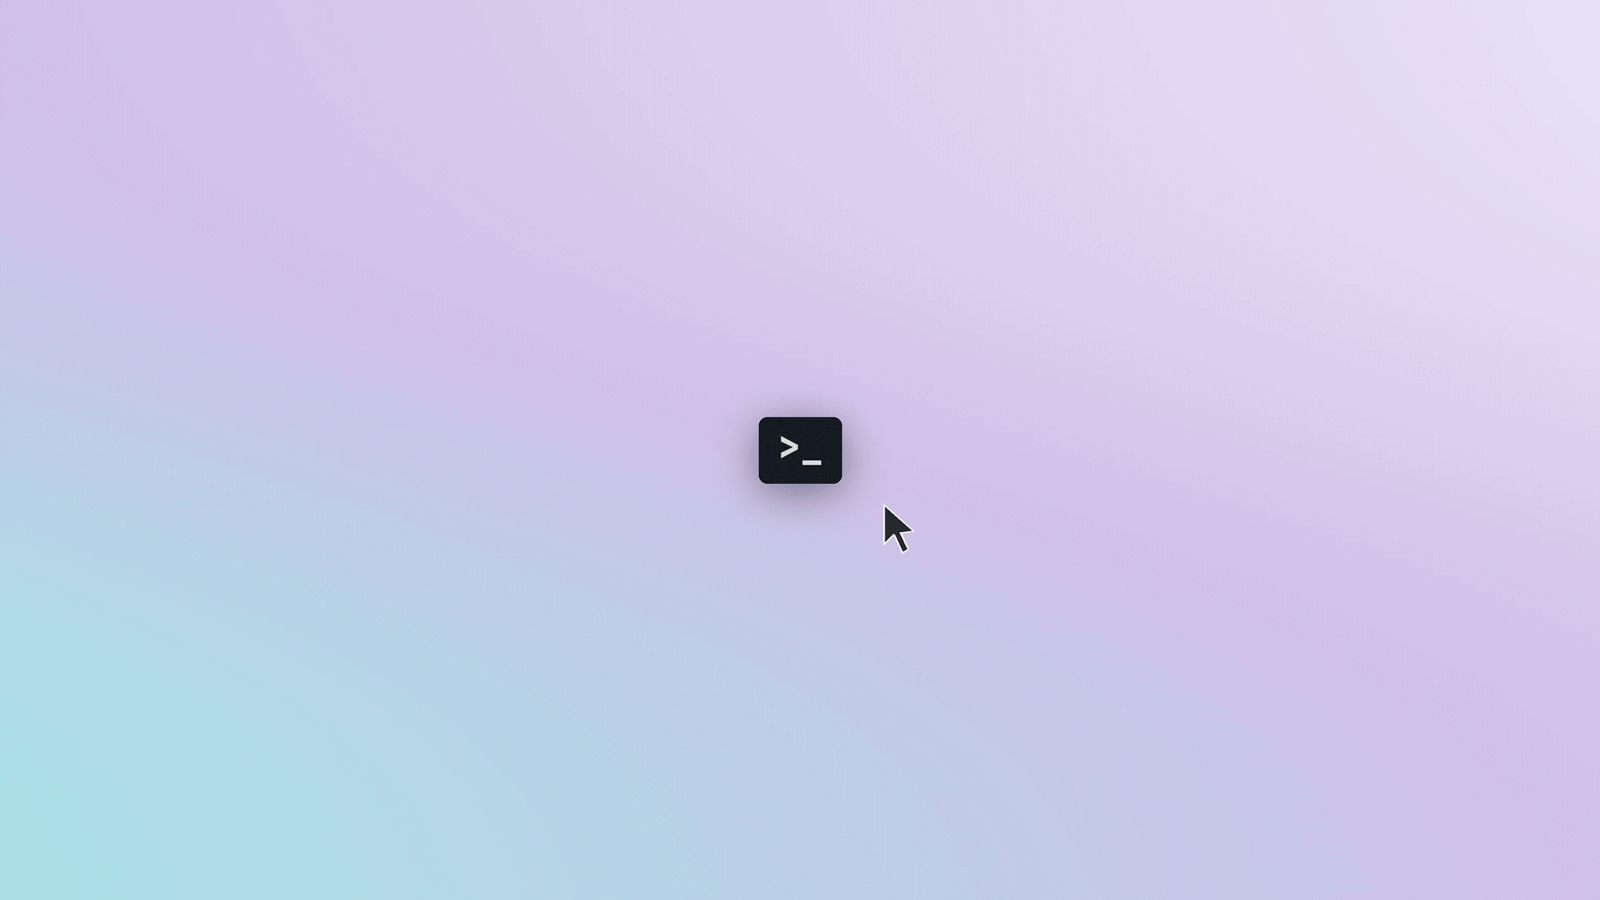
On October 19 Amazon announced TorchNeuron, which uses PyTorch's standard PrivateUse1 device-backend mechanism to register Trainium as a native "neuron" device, with eager mode, torch.compile and native distributed APIs such as FSDP, DTensor and DDP on Trn2 and Trn3. Amazon says existing PyTorch code runs with a single device configuration change, and it will be open-sourced under Apache 2.0 at PyTorch Conference North America on October 20. The official docs still list it as a closed beta for now.
Key Takeaways
- Open-source release: October 20 at PyTorch Conference North America, Apache 2.0 license (per Amazon).
- Hardware: Trainium2 and Trainium3; registers as the neuron device via PrivateUse1, with eager mode and torch.compile(backend="neuron").
- Migration: Amazon markets it as one configuration change with no rewrite; the docs list .to("cuda") to .to("neuron") as the minimum, and tensor parallelism also needs sharding set by NeuronCore count.
- PyTorch 2.9 is the last PyTorch/XLA-based release; from PyTorch 2.10 Neuron moves to TorchNeuron, so older scripts need updates.
- Quality and ecosystem: Amazon says every build is tested against hundreds of thousands of models, TorchTitan is integrated and Hugging Face tools support Trainium natively; no performance benchmarks were published.
Linked Models & Agents: