webAI CEO David Stout announced on X on November 4 (17:37 UTC) that the company is open-sourcing TwIL-8B. The official Hugging Face model card says it is post-trained from IBM Granite 4.2 8B with full-parameter SFT, GRPO/DAPO reinforcement learning and a length-aware RL stage, and ships in balanced and verbose variants. Self-reported scores include LiveCodeBench 81.6 (verbose), MATH-500 98.2 and IFBench 74.4, about 93% and 92% of the best frontier score, while GPQA Diamond is only 70.2. A 4.98 GiB Q4_K_M GGUF runs locally; the license is the webAI Non-Commercial License.
Zoom
Key Takeaways
TwIL-8B has 8.79B parameters, is built on IBM's ibm-granite/granite-4.2-8b, has a 131,072-token context window and is English-only, text to text.
The balanced variant averages about 19.5k output tokens per AIME 2026 problem, about 38% fewer than Qwen3.5-9B's 31.2k, but still roughly 4x GPT-5.5.
All scores are webAI internal evaluations; competitor figures are quoted from public sources and were not re-run. SWE-bench, tool use and agentic tasks were not evaluated.
The license is the webAI Non-Commercial License 1.0, so it cannot be used commercially as is; the Q4_K_M GGUF is about 4.98 GiB and runs with llama.cpp.
On Oct 26 Tencent Hunyuan (Tencent Hy) open-sourced Hy-SimulMT, a real-time simultaneous interpreting model for bidirectional Chinese-English speech-to-speech translation. It translates while the speaker talks, outputs both translated text and speech, and can clone the speaker's voice in real time. Six checkpoints landed on Hugging Face (30B-A3B translation-only and source-plus-translation Interleave variants, each in BF16, FP8 and GGUF), with the model card listing Apache-2.0; GitHub ships the SimulInfer serving stack and SimulTrain training tools. Vendor-reported: about 3s StreamLAAL on RealSI long-form audio, the lowest among compared systems.
Zoom
Key Takeaways
Size and variants: 30B-A3B MoE (about 3B active), six checkpoints: translation-only and Interleave (source plus translation), each in BF16, FP8 and GGUF (Hugging Face collection)
Latency (vendor-reported): about 3s StreamLAAL on RealSI long-form audio, the lowest among compared systems, with a GEMBA quality score above the compared open models and 4 of 5 commercial APIs
Short-form (vendor-reported): FLEURS 90.3, CoVoST2 75.5, ACL6060 81.2, RealSI-Sentence 84.7, the last being the top score in the table; Qwen3.8-LiveTranslate scores 88.4/82.1/80.5/84.4 in the same table
Human comparison: 18 real Chinese and English recordings of about 6 minutes each against 6 CATTI Level 1/2 interpreters; Tencent says quality was on par with often lower latency, and notes the result only covers this small test
Deployment: one SimulInfer deploy.sh command starts vLLM (>=0.31) plus a web/WebSocket service; speech output and voice cloning need a separate TTS service; llama.cpp support is not yet merged upstream (SimulInfer docs)
The Ornith AI team officially released Ornith-1.5-122B under the permissive MIT license, a 122-billion parameter mixture-of-experts (MoE) reasoning model optimized to execute on a single GPU node (such as a single DGX). The model is immediately available across vLLM (0.19.1+), SGLang (0.5.9+), Hugging Face, and Ollama (ornith-1.5:122b) with native FP8, GGUF, and MLX quantization. Across independent agentic evaluations in the OpenHands harness, Ornith-1.5-122B registered 84.5 on SWE-bench Verified, 76.9 on SWE-bench Pro (surpassing Qwen3.8-Flash-Next's 43.9 by 33 points), 81.2 on TerminalBench 2.1, and 74.6 on MCP-Atlas.
Zoom
Key Takeaways
Ornith-1.5-122B released under the permissive MIT license, offering a fully open, frontier-grade 122B MoE coding reasoning model
Engineered to fit inside a single GPU node (single DGX), with immediate runtime support on vLLM, SGLang, and Ollama (ornith-1.5:122b)
Achieves 76.9 on SWE-bench Pro, drastically outperforming the comparable open-weight baseline Qwen3.8-Flash-Next (43.9)
Delivers balanced agentic performance with 81.2 on TerminalBench 2.1, 80.0 on CyberGym, and 74.6 on MCP-Atlas
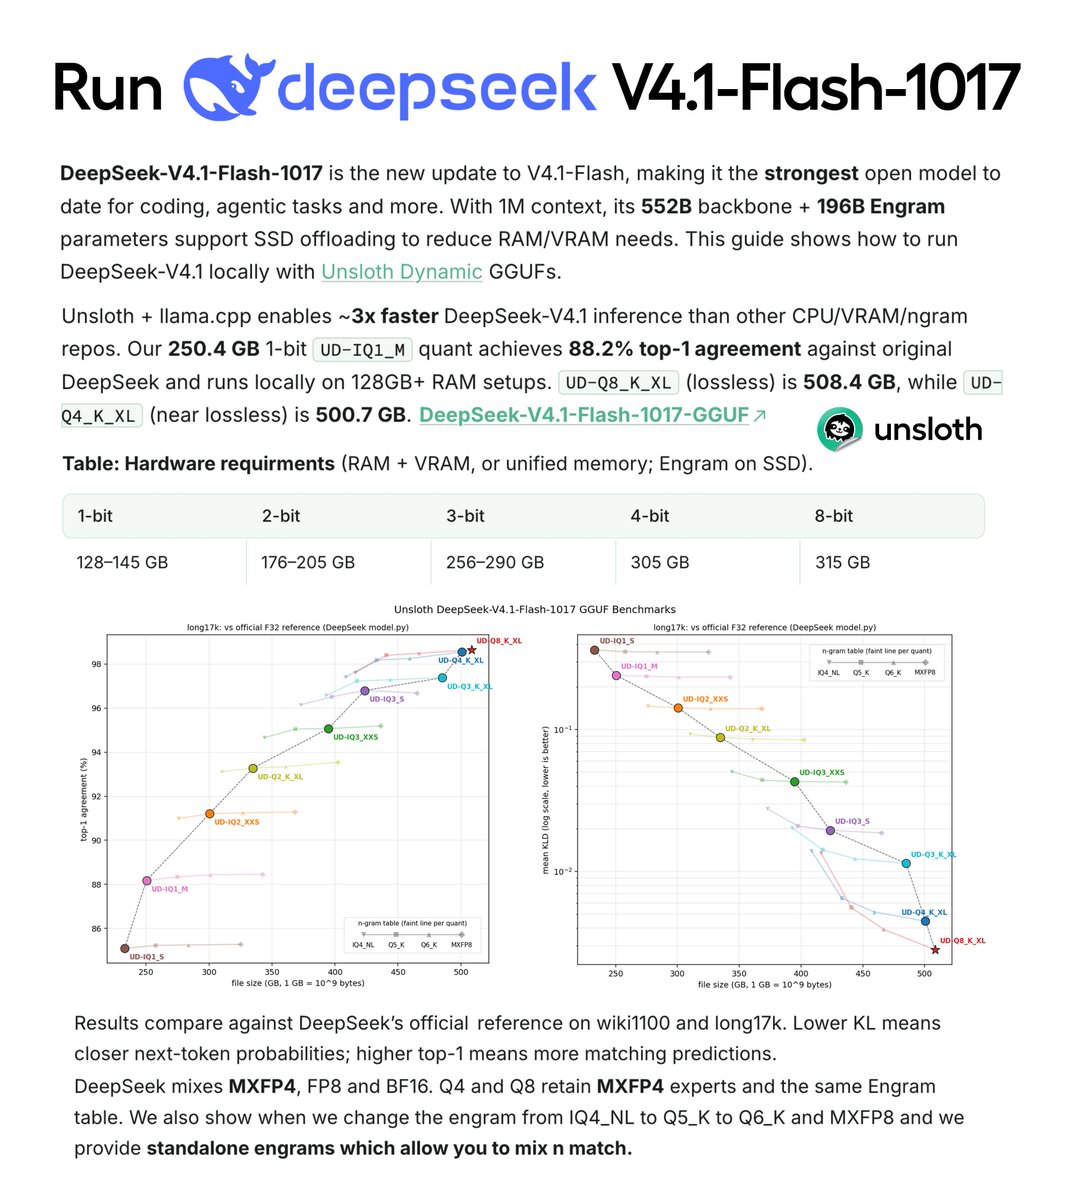
On Oct 19 (UTC) Unsloth released dynamic GGUF quants and a run-locally guide for DeepSeek-V4.1-Flash-1017. Per Unsloth, the 1-bit UD-IQ1_M quant is 250.4 GB (vs 508.4 GB for lossless Q8), keeps 88.2% top-1 agreement with the official weights on long17k, and runs on 128 GB+ RAM machines, because the model's 110.6–202.8 GB Engram n-gram table can stay on SSD via mmap. Running it currently requires Unsloth's llama.cpp PR build or Unsloth Desktop.
Zoom
Key Takeaways
1-bit UD-IQ1_M is 250.4 GB, about 51% smaller than lossless UD-Q8_K_XL (508.4 GB), with 88.2% top-1 agreement on long17k and 87.1% on wiki1100 (Unsloth-reported)
The smallest UD-IQ1_S (233.0 GB) targets 128 GB RAM machines such as a Mac or DGX Spark at 82.8–85.1% agreement; 3-bit UD-IQ3_XXS needs ~256 GB (e.g. Mac Studio) at 94.6–95.1%
The model pairs a 552B backbone with 196B Engram parameters; the 110.6–202.8 GB Engram n-gram table can stay on SSD via mmap, saving RAM but not disk
Unsloth claims ~3x faster inference than other CPU/VRAM/ngram-focused repos on top of llama.cpp (vendor claim, no independent test yet)
The Hugging Face repo is MIT-licensed with 9 quant levels from IQ1_S to Q8_K_XL plus standalone Engram files at different precisions
NVIDIA published Nemotron-Labs Dory1.0-4B on Hugging Face on Oct 16: a 20-layer shared block runs 1, 2 or 4 times at inference so one checkpoint serves several compute budgets. NVIDIA reports 61.8 on SWE-bench Verified at 4 loops, close to Qwen3.5-9B. BF16/MXFP8/NVFP4/GGUF under OpenMDW-1.1.
On Oct 13 Liquid AI released LFM2.5-24B-A2B, the largest and final LFM2.5 model: 24B total parameters, ~2.45B active per token, 131K context, and always-on reasoning. By Liquid's own numbers it leads or matches Qwen3.6-35B-A3B on 5 of 8 tool-use/agent benchmarks (AutomationBench 27.69 vs 8.72) while trailing on SWE-Bench Verified, GPQA and other knowledge/coding tests. Open weights are on Hugging Face with GGUF, MLX, FP8 and ONNX builds; API pricing is $0.10 / $1.00 per million tokens and it is also on OpenRouter.
Agent benchmarks (vendor-reported, vs Qwen3.6-35B-A3B): AutomationBench 27.69 vs 8.72, LiveClaw 48.09 vs 38.19, ToolSandbox 80.71 vs 75.02, BFCLv4 65.01 vs 65.00
Disclosed weaknesses: SWE-Bench Verified (OpenCode) 51.00 vs 66.20, GPQA Diamond 74.42 vs 83.69, WebArena Verified 26.75 vs 37.62
Speed: 184 tok/s decode on Apple M5 Max, 114 tok/s on Ryzen AI Max+ 395, 21K+ output tok/s on one B300 with SGLang
Training: pretraining scaled 17T to 33T tokens; agentic RL inside OpenClaw, Hermes Agent, Pi and OpenCode; API $0.10 in / $1.00 out per M tokens
On 2026-10-12 LightOn AI released ColGrep-Agent-2B (fine-tuned from MiniCPM5-2B, Apache-2.0): a local 2B code-localization agent that searches with ColGrep multi-vector retrieval plus a read-only terminal, then returns file paths and line ranges to a frontier coding agent. On 52 code-search questions across 13 unseen repos (624 Claude Code / Sonnet 5.5 sessions), delegating search cut API tokens ~34.3% and cache-aware cost ~40% vs grep, with 80.8% vs 83.3% accuracy (not statistically significant). On SWE-bench Lite localization it posted 19.92 line F1—best among models evaluated in the same ColGrep harness, including several >10× larger. Ships brew/cargo/GGUF installers and hooks for Claude Code, Codex, and OpenCode.
On Oct 8 JetBrains released Mellum2.1 Thinking: same 12B MoE / 2.5B active / 131K / Apache 2.0 architecture, with gains almost entirely from large-scale RL in real sandboxes. Self-reported same-pipeline scores: SWE-bench Verified 47.0 (vs Mellum2 2.0), LiveCodeBench v6 82.0. On Hugging Face; vLLM serve now; GGUF/MTP coming soon.
Unsloth AI released version v0.1.815-beta alongside official prebuilt Linux x86_64 CUDA 13 wheels for Flash-Attention 2.8.4, Causal-Conv1D 1.7.0, and Mamba-SSM 2.3.2.post1 targeting PyTorch 2.13/2.14 on Python 3.13. The release enables fast local deployment of Alibaba's Qwen-Image-2.1 across both consumer and datacenter GPUs using Fast FP8 and GGUF quantization (defaulting to Q4_K_M) for combined image generation and precise image editing. Crucially, the Unsloth workspace introduces custom Agent Skills compatible with Claude Code and .agents formats, featuring @skill tagging in chat and 2x faster reasoning blocks (boosting UI rendering from 30 FPS to 60 FPS).
Zoom
Key Takeaways
Official CUDA 13 prebuilt wheels: instant binaries for Flash-Attention 2.8.4 and Mamba-SSM on PyTorch 2.13/2.14, eliminating compilation errors
Local Qwen-Image-2.1 execution: Fast FP8 and GGUF Q4_K_M support for both high-fidelity image generation and interactive image editing
Claude Code skill interoperability: native support for importing and executing custom skills from .agents and Claude Code folders with @skill
60 FPS reasoning blocks: doubled chain-of-thought rendering performance from 30 FPS to 60 FPS with reworked UX
Expanded platform support: in-app Debian upgrades and a dedicated installer for Ubuntu 24.04+ on ARM64 architectures
Unsloth says optimized local GGUF decoding makes GLM-5.3-Flash up to ~3.3× faster (typically ~1.6–3.4×), with multi-token prediction (MTP) and faster long-context decoding. 3-bit quants still target ~128GB setups via Unsloth Desktop or llama.cpp; docs and Hugging Face GGUF weights are updated.
Key Takeaways
Speed: local GGUF inference up to ~3.3× (typical ~1.6–3.4×).
Features: MTP enabled plus faster long-context decoding.
Run: 3-bit on ~128GB via Unsloth Desktop / llama.cpp; docs and HF GGUFs live.
Unsloth released 3-bit GGUF quantization for Z.ai's GLM-5.3-Flash (Ox Alpha), enabling local on-device inference for the 320B-A18B multimodal MoE on 128GB RAM workstations without datacenter GPUs.
Key Takeaways
Day-one local offline support for a 320B multimodal coding model on workstation hardware like Mac Studio;
Maintains high reasoning and coding fidelity on DeepSWE benchmarks under optimized 3-bit quantization;
Weights and deployment guides published on Hugging Face for instant use with llama.cpp and LM Studio.
Alibaba Qwen team open-sources Qwen3.8-Flash-Next weights (125B total / 6B active MoE). Partnering with Unsloth, optimized GGUF quantizations run full 262K context on single 24GB GPUs at 85 tokens/sec.
Key Takeaways
Qwen team open-sources Qwen3.8-Flash-Next 125B/6B MoE weights;
Unsloth GGUF quantizations enable full 262K context on single 24GB GPUs;
Local inference throughput reaches 85 tokens/s for air-gapped private development.
Alibaba Qwen confirmed that the 125B multimodal MoE Qwen3.8-Flash-Next can now run locally on about 75GB of RAM via Unsloth GGUFs, with N-gram embeddings offloaded to CPU or unified memory for near-VRAM speed. It is the day-0 local path for the Qwen4 architecture preview weights.
Key Takeaways
125B MoE with 6B active parameters plus 51B n-gram embeddings now runs locally on ~75GB RAM without fitting the full model in GPU VRAM
Unsloth shipped day-0 GGUFs and a Qwen3.8-Flash-Next guide; CPU RAM / unified-memory setups approach VRAM throughput
Official weights remain on Hugging Face and ModelScope, with day-0 vLLM and SGLang serving on NVIDIA and AMD