Baidu Opens ERNIE-5.5-Flash-Base: 280B-A14B MoE, 33.5T Pretrain, Vendor-Reported MMLU 93.3
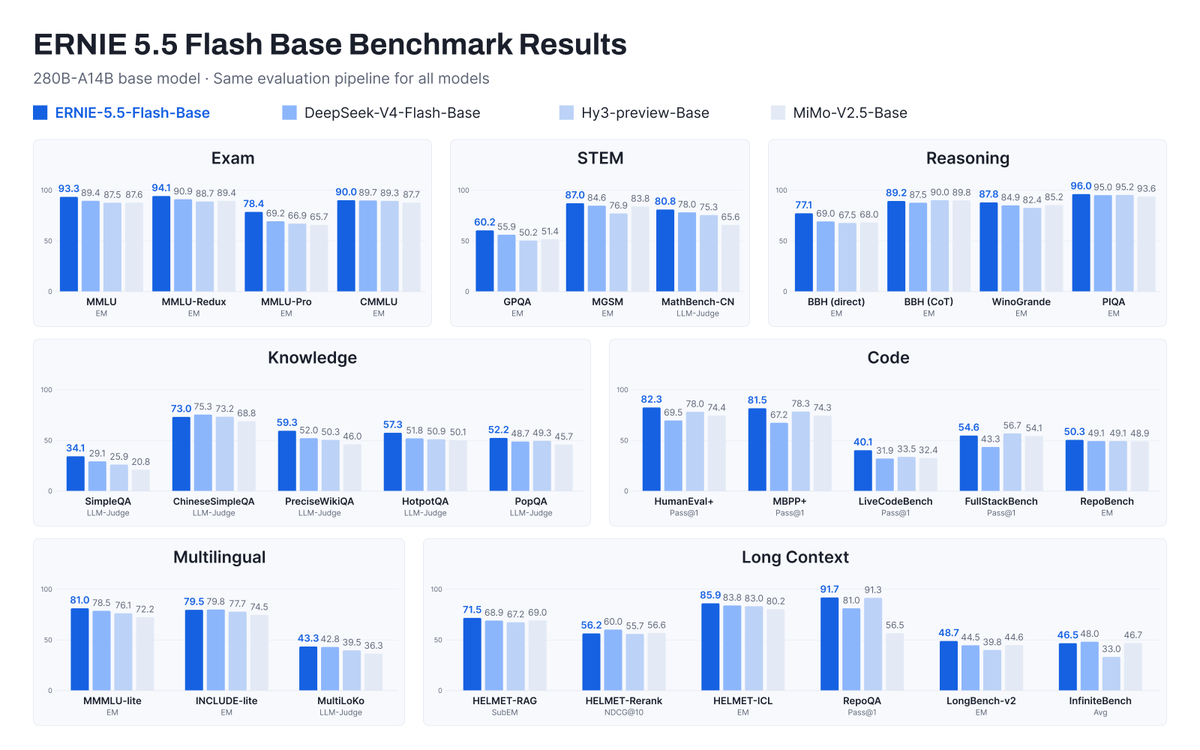
On November 5 Baidu (official blog + @BaiduResearch) open-sourced ERNIE-5.5-Flash-Base: a text-only MoE base checkpoint at end of pre-training (no mid/post-training), 280B total / 14B active per token, 33.5T pretrain tokens, up to 128K train context and 1M for fine-tune/inference. FP8 and BF16 weights are on Hugging Face and ModelScope. Under Baidu's unified eval pipeline vs similar bases: MMLU 93.3, HumanEval+ 82.3, LiveCodeBench 40.1 (vendor-reported). Post-trained ERNIE 5.5 Flash "will follow". License is custom (excludes EU/UK/South Korea; commercial use above $50M related revenue needs prior written authorization).
Key Takeaways
- Nov 5 open base at end of pre-training: 280B total / 14B active — not a chat/instruct model
- 33.5T pretrain tokens; up to 128K train context, 1M for fine-tune and inference
- Vendor unified eval: MMLU 93.3, HumanEval+ 82.3, LiveCodeBench 40.1 vs similar bases
- Architecture: 37 HCA + 6 MLA-DSA layers; Multi-Router Latent MoE (512 routed top-10 + 1 shared)
- Custom license (not Apache): excludes EU/UK/South Korea; >$50M related revenue needs Baidu written authorization
Linked Models & Agents:
⚡ Ernie 5.5 Flash Base🌐 Baidu (百度文心)