AI Coding Live News

Hyperstition Open-Sources Hyperkernel: Recursive Megakernel Generator; Vendor Claims Beat NVIDIA-Published vLLM on DeepSeek v4.1 Flash Latency

On 2026-11-05 Hyperstition open-sourced Hyperkernel’s first generated megakernels (Hyperserve), with vendor-reported gains versus NVIDIA-published vLLM baselines; Alpha, B300-oriented.
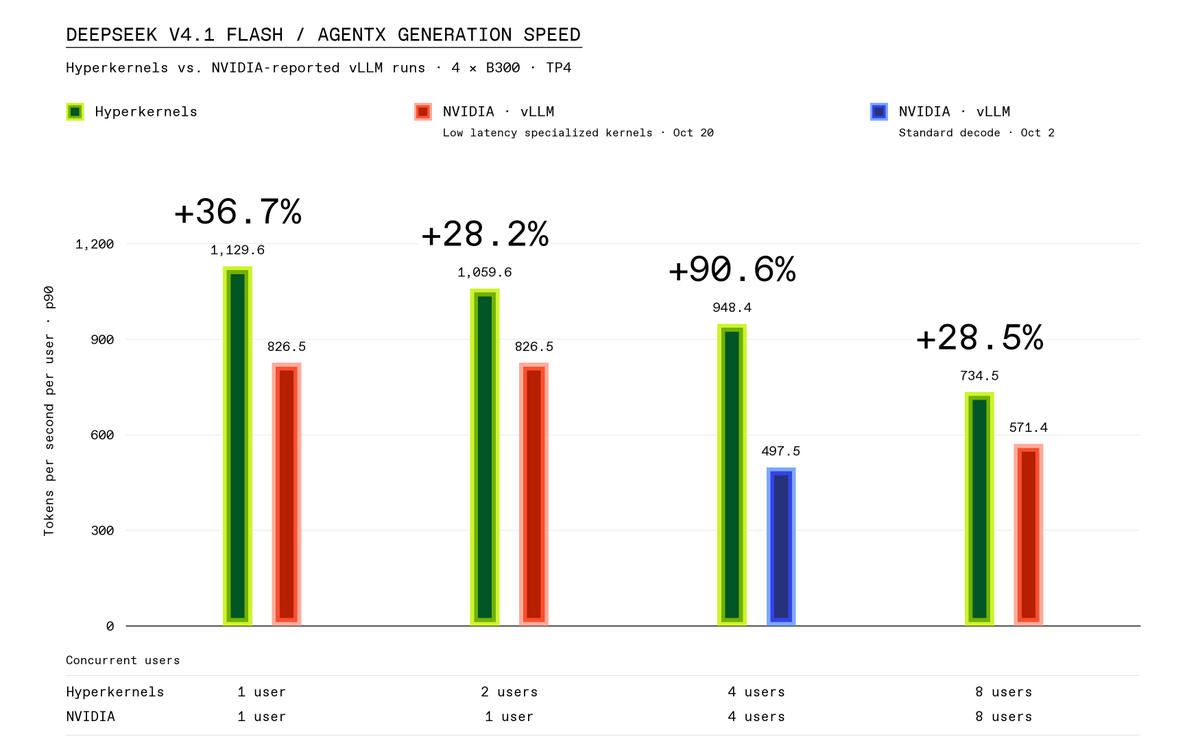
Hyperstition Open-Sources Hyperkernel: Recursive Megakernel Generator; Vendor Claims Beat NVIDIA-Published vLLM on DeepSeek v4.1 Flash Latency

Key Takeaways

  • Official: @hyperstition_cc on 2026-11-05; GitHub Hyperstitioncc/Hyperkernel (MIT, Alpha)
  • Vendor claim: DeepSeek v4.1 Flash ~36.7% higher per-user gen at C1 vs NVIDIA-published vLLM; ~90.6% at C4 vs AgentX
  • π₀-FAST ~94 vs ~243 ms; Matrix-Game ~37.4 vs ~11.6 FPS (~3.2×)
  • CLI: hyperserve llm|drive|dna|world; BYO weights, B300/R580+
  • Not independent reruns; full stack + Kimi/GLM serving planned in weeks
Read full story
Linked Models & Agents:

SemiAnalysis Discloses Google & Inferact TPUv7 Submission: TorchTPU vLLM Megakernels Drive 2.8T Kimi K3, Surpassing GB200 NVL72 and B300 in High-Interactivity TCO

SemiAnalysis revealed the first Google TPUv7 benchmark submission for the 2.8T Kimi K3 MoE model, led end-to-end by Inferact (the creators of vLLM) and Google using the TorchTPU vLLM stack. At a hardware rental cost of just $1.21/chip-hour (vs $2.31 for GB300 and $1.86 for GB200), TPUv7 delivers ~2.2M tokens per $1 TCO in the ultra-high interactivity regime (~390 tok/s/user), outpacing NVIDIA GB200 NVL72, B300, and AMD MI355X on cost-performance.

SemiAnalysis Discloses Google & Inferact TPUv7 Submission: TorchTPU vLLM Megakernels Drive 2.8T Kimi K3, Surpassing GB200 NVL72 and B300 in High-Interactivity TCO

Key Takeaways

  • Inferact (creators of vLLM) and Google submitted their first preliminary TPUv7 benchmark for the 2.8T Kimi K3 MoE model
  • TPUv7 chip rental sits at $1.21/hour, significantly below GB300 ($2.31), B300 ($2.26), and GB200 ($1.86)
  • Delivers ~2.2M tokens per $1 TCO at ~390 tok/s/user, beating NVIDIA GB200 NVL72, B300, and AMD MI355X in the ultra-high interactivity regime
  • Built with fused TorchTPU vLLM megakernels and the TPU-Sync KVCache offload library for production PD disaggregation
Read full story
Linked Models & Agents:

Kimi K3 Hits 842 tok/s on NVIDIA GB300 NVL72: NVIDIA and vLLM Unveil 12,000-Line CuTe DSL Decode Megakernel with 1.8x Higher AgentX Interactivity

vLLM and NVIDIA unveiled a unified CuTe DSL decode megakernel (~12,000 LoC authored by NVIDIA CentML's Benjamin Chislett) for Moonshot AI's frontier Kimi K3 model on NVIDIA GB300 NVL72. By fusing attention, MoE, and cross-GPU communication, the optimization cuts per-layer latency from 130 µs (23 kernels) to 69 µs (13 kernels), delivering 842 tokens/s at batch=1 with DSpark speculative decoding (1.73x faster than stock vLLM) and up to 1.8x higher P90 per-user interactivity (403.2–423 tok/s/user) on SemiAnalysis AgentX, with DeepSeek-V4.1-Flash (PR #61868) and GLM-5.3 support coming next.

Kimi K3 Hits 842 tok/s on NVIDIA GB300 NVL72: NVIDIA and vLLM Unveil 12,000-Line CuTe DSL Decode Megakernel with 1.8x Higher AgentX Interactivity

Key Takeaways

  • NVIDIA and vLLM introduce a 12,000-line CuTe DSL decode megakernel for the 2.8T-parameter Kimi K3, reducing per-layer execution from 23 kernels (130 µs) to 13 kernels (69 µs)
  • On 16x NVIDIA GB300 NVL72 GPUs, batch-1 decode hits 842 tok/s with DSpark speculative decoding (1.73x faster) and 256.4 tok/s without speculation (1.88x faster)
  • Delivers up to 1.8x higher P90 interactivity (403.2-423 tok/s/user) on SemiAnalysis AgentX, with DeepSeek-V4.1-Flash (vLLM PR #61868) and GLM-5.3 megakernels following next
Read full story
Linked Models & Agents:

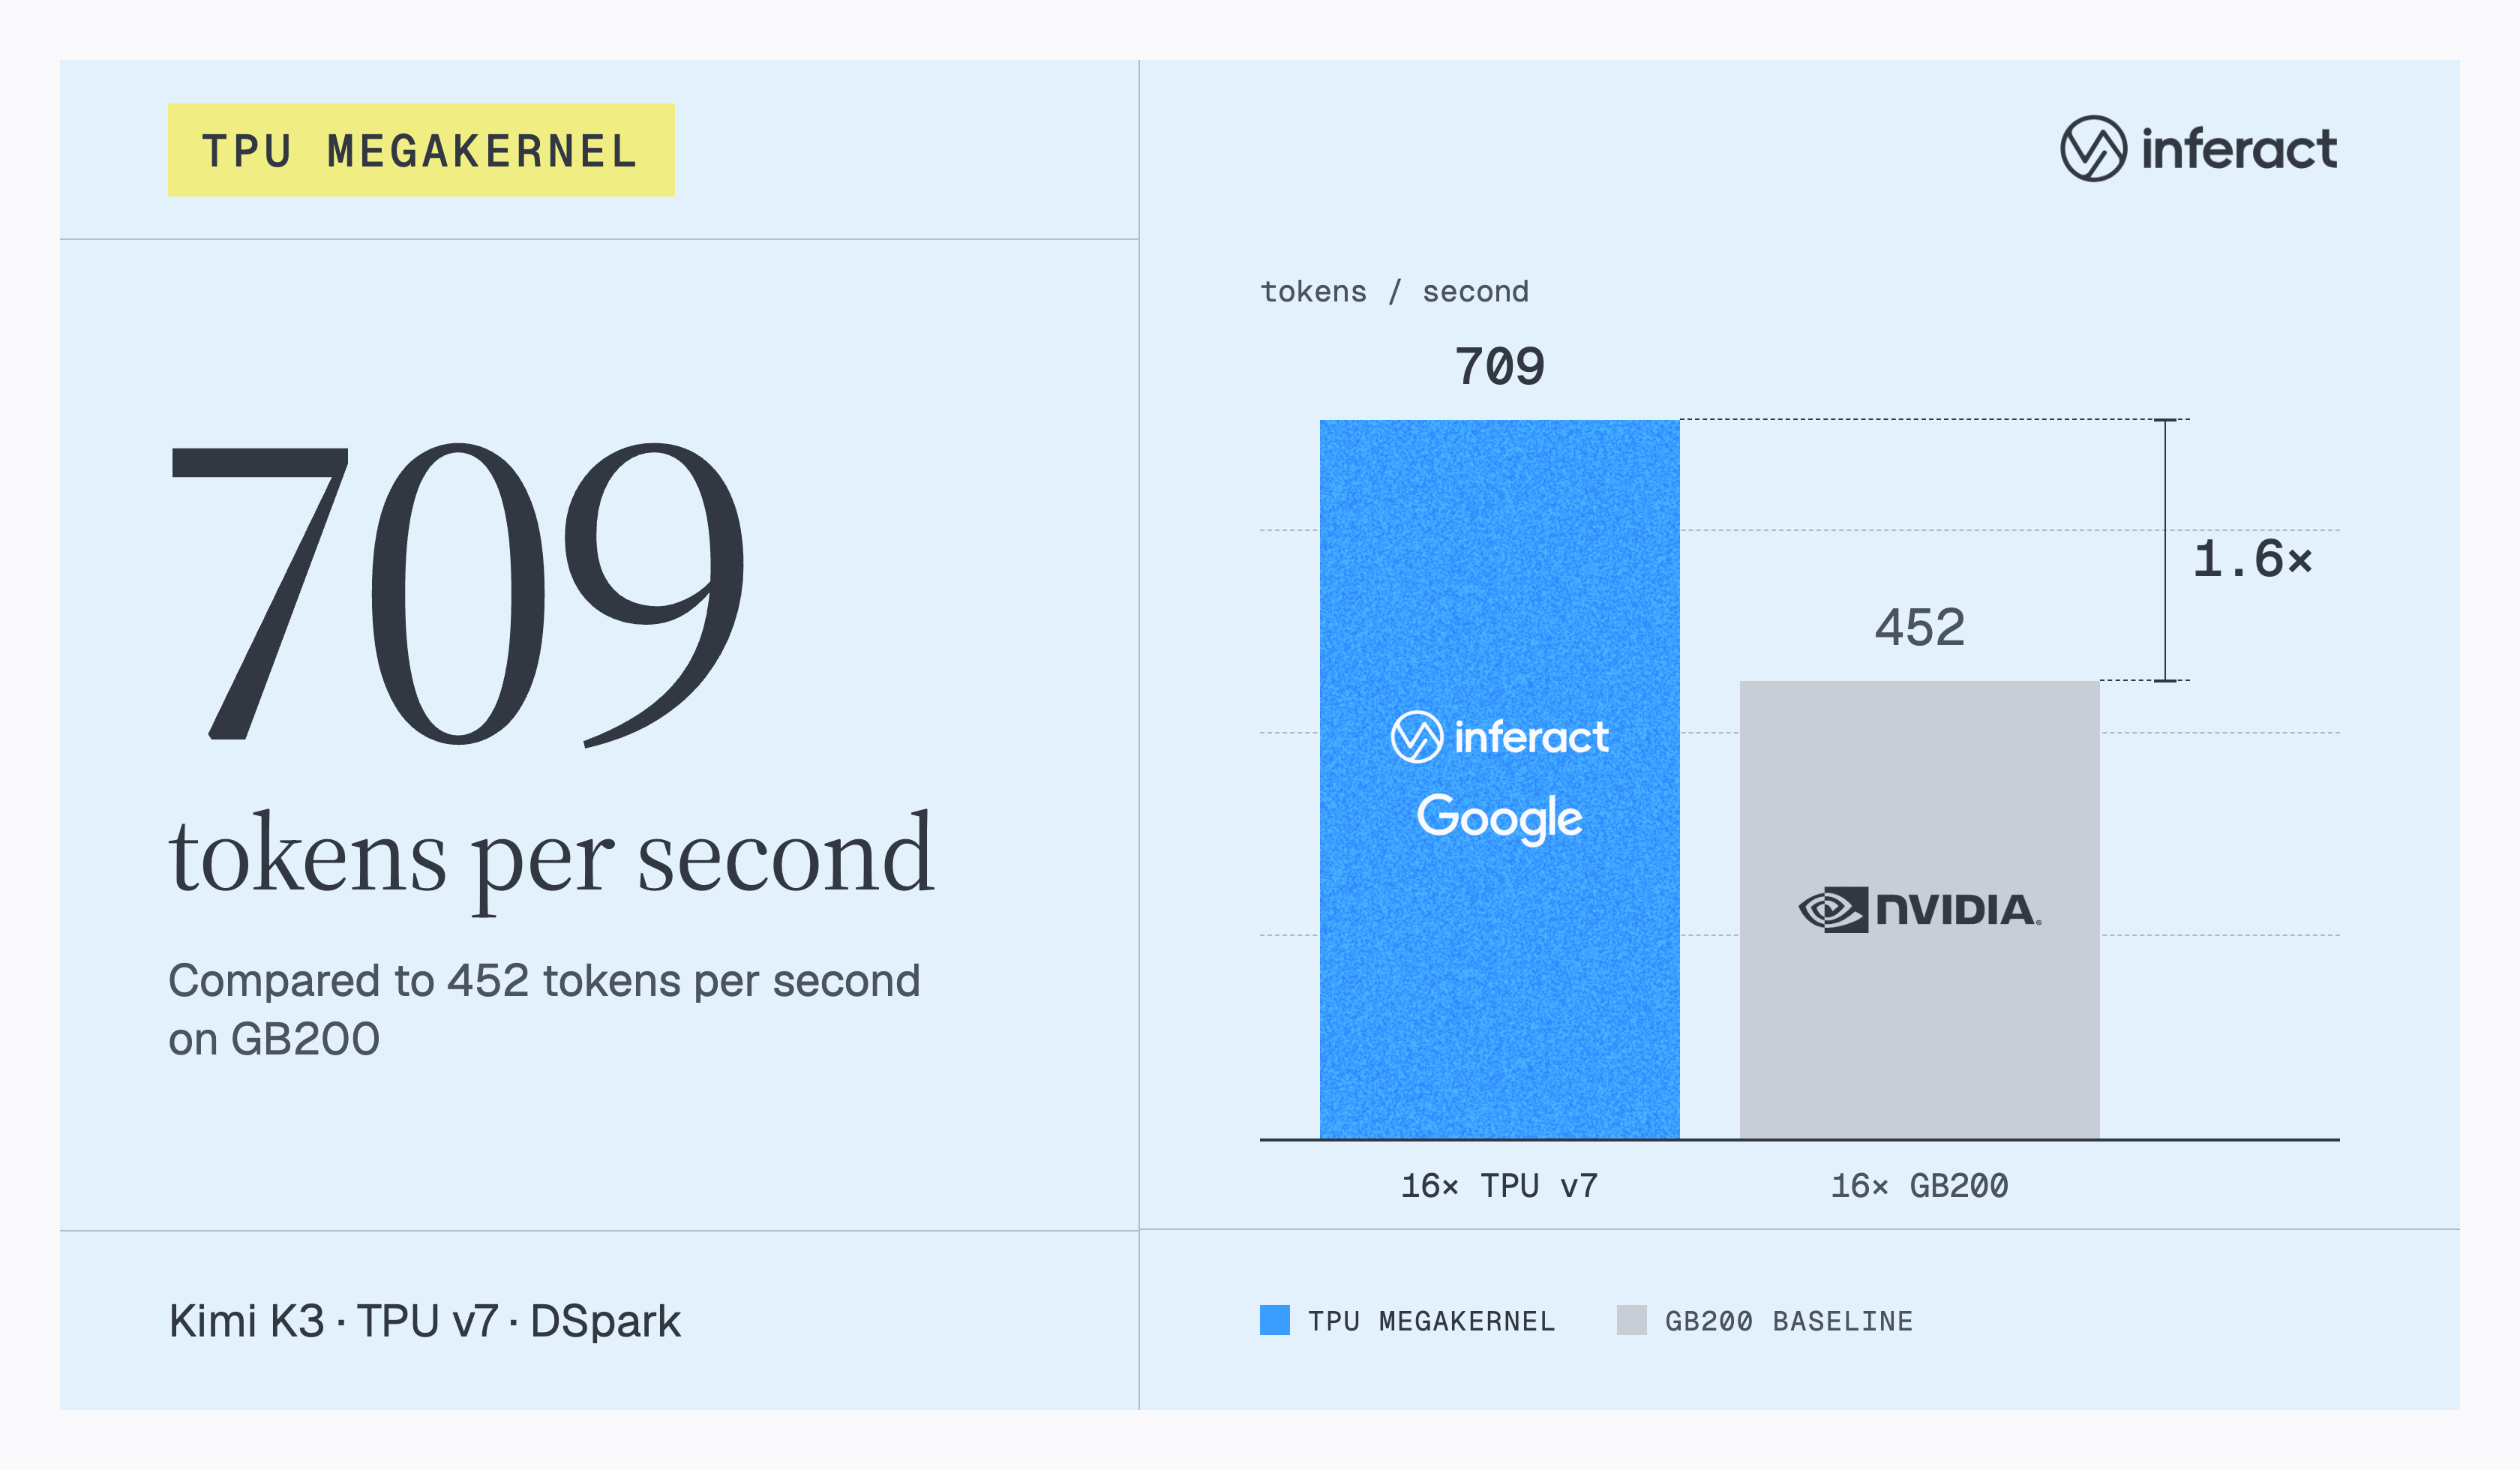
Inferact open-sources TPU megakernels: Kimi K3 hits 709 tok/s on 16× TPU v7 vs 452 on GB200

Inferact open-sourced inferact/tpu-megakernels on 2026-09-23: a Pallas megakernel collection for TPU v7. Their blog reports Kimi K3 at 709 tok/s on 16× TPU v7 Ironwood vs 452 tok/s on 16× GB200 under DSpark speculative decoding (acceptance length 6), and roughly 1.4–2× the GB200 baseline at batch sizes 1–8 without speculation. All 92 MoE layers of Kimi K3 run in a single kernel with cross-layer weight prefetch.

Inferact open-sources TPU megakernels: Kimi K3 hits 709 tok/s on 16× TPU v7 vs 452 on GB200

Key Takeaways

  • Inferact-reported (not independently reproduced): Kimi K3 + DSpark reaches 709 tok/s on 16× TPU v7 vs 452 tok/s on 16× GB200 (blog)
  • Without speculation: ~1.4–2× GB200 baseline at batch 1–8; Qwen 3.8 27B: 1,515 vs 695 tok/s on 4× chips with speculation
  • All 92 MoE layers of Kimi K3 run in one Pallas megakernel with cross-layer weight prefetch into VMEM
  • Repo: Inferact/tpu-megakernels (Apache-2.0)
Read full story
Linked Models & Agents:
ADSponsored