AI Coding Live News

Artificial Analysis Ships Endpoint Accuracy Index v1.1: Nearly 1 in 4 of 100+ Serverless Endpoints Score Below Reference

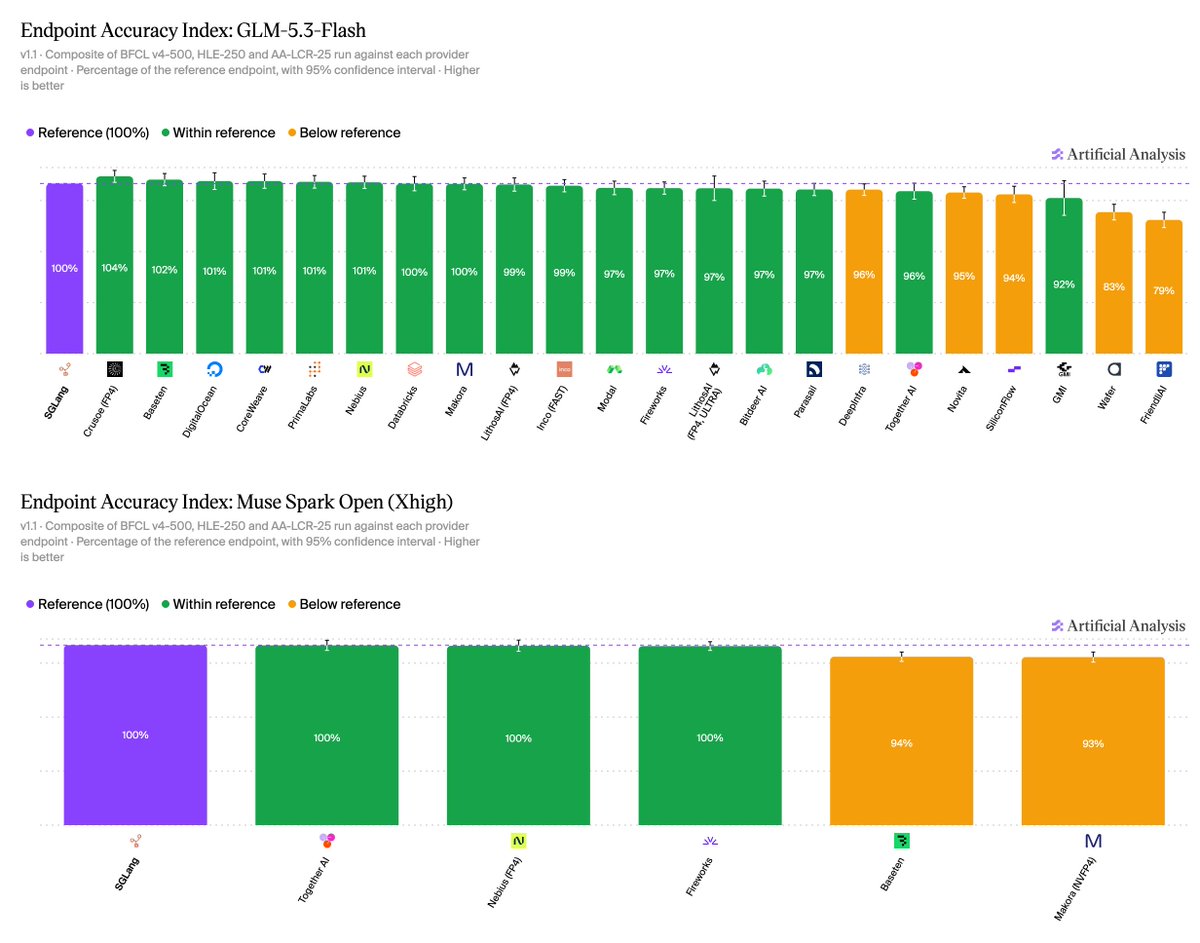
On 2026-11-06 Artificial Analysis launched Endpoint Accuracy Index v1.1: each serverless endpoint is scored as a percentage of a self-hosted official-weights reference across equally weighted BFCL-500, HLE-250, and AA-LCR-25. Vendor claim: nearly 1 in 4 of 100+ benchmarked endpoints score below the reference. AA-LCR-25 moved to v1.1 with repeats raised from 10 to 25 (average 95% CI ~±4.7 to ±2.6), and coverage expanded to six open-weights models including GLM-5.3 Flash and Muse Spark Open.
Artificial Analysis Ships Endpoint Accuracy Index v1.1: Nearly 1 in 4 of 100+ Serverless Endpoints Score Below Reference

Key Takeaways

  • Official: @ArtificialAnlys 2026-11-06 02:44 UTC; changelog 05 Nov 2026; methodology Endpoint Accuracy Index v1.1
  • Vendor claim: nearly 1 in 4 of 100+ serverless endpoints score below the self-hosted reference; providers often quantize, custom-kernel, tune stacks, or cap outputs
  • Equal-weight suite: BFCL v4-500 (3 repeats), HLE-250 (10), AA-LCR-25 (25); 95% CIs vs reference with significance flags
  • GLM-5.3 Flash: 16 of 22 endpoints statistically in line, one ~104.2; ~32K output caps scored ~22%/29% on HLE-250 vs 55% reference
  • Muse Spark Open: 3 of 5 endpoints ~99.5–99.9 (incl. FP4); two mainly lose on tool calling (BFCL-500 ~50%/51% vs 59%)
Read full story

Google AI Studio Opens Gemini 4 Argon in Build & Playground for Pro Users; Transformers v5.20.1 Adds Native Reflection AI Beam and Meta 816B Muse Spark Open

Google AI Studio launched Gemini 4 Argon access in AI Studio Build and Playground for Google AI Pro subscribers, while Hugging Face Transformers v5.20.0 and v5.20.1 added native support for Reflection AI's frontier coding model Beam, Meta's 816B-parameter (42B active, 1M context) multimodal agentic coding model Muse Spark Open, InclusionAI's Ling 3.0 Flash, and OpenBMB's MiniCPM-V 4.7.

Google AI Studio Opens Gemini 4 Argon in Build & Playground for Pro Users; Transformers v5.20.1 Adds Native Reflection AI Beam and Meta 816B Muse Spark Open

Key Takeaways

  • Google AI Studio opens Gemini 4 Argon in AI Studio Build and Playground (https://ai.studio/build) for Google AI Pro subscribers
  • Hugging Face Transformers v5.20.1 natively integrates Reflection AI's token-efficient coding model Beam and fixes DeepGEMM Mega MoE under expert parallelism
  • Adds native support for Meta's 816B-parameter (42B active, 1M context, BF16/NVFP4) omni-modal coding model Muse Spark Open and InclusionAI's KDA+MLA hybrid Ling 3.0 Flash
Read full story
Linked Models & Agents:

Meta open-sources Muse Spark Open: 816B-total / 42B-active MoE with 1M context, billed as the most capable US open-weight model to date

On 2026-10-15 Meta released weights for Muse Spark Open, a natively multimodal MoE (~816B total / ~42B active per token, 1M context) aimed at long-horizon coding and agents. Weights are on Hugging Face and peers; hosted APIs include Together, Fireworks, Groq and OpenRouter. Reported figures include DeepSWE 60%, MCP-Atlas 89.2% and JobBench 61.8% (see Meta’s evaluation methodology).

Meta open-sources Muse Spark Open: 816B-total / 42B-active MoE with 1M context, billed as the most capable US open-weight model to date

Key Takeaways

  • Scale: ~816B total / ~42B active per token; 256 experts/layer with top-8 routing; 62 layers, hidden 8192; context up to 1,048,576 (HF blog)
  • Coding/agents (Meta scorecard / AA, xhigh): DeepSWE 60.0%; SWE-Atlas Codebase QnA 58.0%; MCP-Atlas 89.2%; JobBench 61.8%; Toolathlon-Verified 72.8% (eval methodology)
  • Throughput (NVIDIA tech blog, agentic on GB300 NVL72): up to ~50K tok/s/GPU and ~600 tok/s/user; NVFP4 checkpoints published (NVIDIA blog)
  • Deploy: Muse Model License with limited commercial terms; SGLang / vLLM / TensorRT-LLM / MLX / llama.cpp; Meta demos two Apple M5 Ultra Mac Studios for on-desk local run
  • Third-party index: Artificial Analysis Intelligence Index ~38.9–39 (xhigh, as of 2026-10-07)—behind closed frontier, but a key open-weight reference (AA)
Read full story
Linked Models & Agents:
⚡ Muse Spark Open⚡ Muse Spark Open 816B-A42B🤖 Muse Code🌐 Meta🌐 NVIDIA🌐 Hugging Face🌐 Apple

Meta open-sources Muse Spark Open: 816B/42B natively multimodal US open-weight flagship, runs on two M5 Ultra Mac Studios

On 2026-10-15 Meta released Muse Spark Open open weights: an 816B-total / 42B-active MoE with a Perception Encoder, natively multimodal (text/image/video/audio in → text out), 1M context, aimed at coding and long-horizon agents. Weights are on Hugging Face (BF16/NVFP4), SageMaker, Model Garden and Foundry; APIs include OpenRouter, Together, Fireworks and Groq. Meta calls it the most capable US open-weight model to date and, with Apple, optimized it to run locally across two M5 Ultra Mac Studios via MLX.

Meta open-sources Muse Spark Open: 816B/42B natively multimodal US open-weight flagship, runs on two M5 Ultra Mac Studios

Key Takeaways

  • Specs: MoE 816B total / 42B active (256 experts, top-8), 62 layers, 1M context; text+image+video+audio in → text out (model card)
  • Local: NVFP4 needs ≥~700GB VRAM, BF16 ~2TB; or two Apple M5 Ultra Mac Studios via MLX (Meta blog)
  • Agentic benches (xhigh, official table): MCP-Atlas 89.2, JobBench 61.8, OSWorld Verified 80.4, Terminal-Bench 2.1 76.4, DeepSWE 1.1 60, AA Intelligence Index 39
  • Serve with SGLang / vLLM / TensorRT-LLM / Transformers / llama.cpp / Unsloth / MLX; Helion kernels claim 1.03–3.95× kernel speedups on NVIDIA/AMD
  • License: Muse Model License (display “Built with Muse Spark Open”; MaaS over $20M/yr needs a separate deal); OpenRouter ~$1.25/M in, $4.25/M out
Read full story
Linked Models & Agents:
ADSponsored

Meta Re-Architects Muse Spark 1.3: Linear Attention & Diffusion Decoding Yield 3.8x Speedup

Meta overhauled the inference engine for Muse Spark 1.3, combining sub-quadratic linear attention with lossless parallel diffusion decoding. The upgrade delivers a 3.8x throughput increase and 50% memory reduction during long-horizon agent coding workflows.

Key Takeaways

  • Pairs linear attention with diffusion decoding to achieve 3.8x generation throughput
  • Cuts VRAM footprints by half, enabling massive context generation on consumer GPUs
  • Cements Meta open-weights dominance across edge and high-concurrency developer systems
Read full story
Linked Models & Agents:

Vals: Tencent Hy4 Preview ranks #4 open-weight on Vals Index with standout Code Migration value

Vals benchmarked Tencent Hy4 Preview at #21 of 58 on the Vals Index (55.4%) and #4 among open-weight models at about $1.28 per test. It is the cheapest top-ten model on Code Migration (47.4%) versus much costlier Muse Spark and Opus 4.8 runs, leads open-weight models on three agentic benches, and ships with a 1M context window and 64k max output tokens.

Key Takeaways

  • #21 of 58 on Vals Index (55.4%) and #4 open-weight at roughly $1.28 per test, below median cost on most benches.
  • Code Migration 47.4% lands in the top ten at about $3.41 per test versus ~$14.21 Muse Spark and ~$30.51 Opus 4.8.
  • Top open-weight on three agentic benchmarks; 1M context and 64k max output; weaker on terminal work (~55% Terminal-Bench 2.1).
Read full story
Linked Models & Agents:

LMArena: Muse Spark 1.3 Max hits #13 on Agent Arena (+4.2%); Code to #15

LMArena reports Muse Spark 1.3 (Max) at #13 on Agent Arena with +4.2% net improvement across 8.7K+ real agentic sessions — a 17-rank climb from Muse Spark 1.2 (xHigh) at #30. Code, Work, and Chat all improved, with Code moving to #15 (+4.3%).

Key Takeaways

  • #13 on Agent Arena with +4.2% net improvement over 8.7K+ sessions.
  • 17-rank climb from Muse Spark 1.2 (xHigh) at #30.
  • Code reaches #15 (+4.3%); Work and Chat also improve.
Read full story

Cline adds free Meta Muse Spark 1.3 Contributor: near Opus 5, much cheaper

Cline says Meta’s Muse Spark 1.3 Contributor model is now free inside Cline. Benchmarks are described as similar to Opus 5 while remaining considerably more affordable for coding-agent workflows.

Key Takeaways

  • Muse Spark 1.3 Contributor is free in Cline.
  • Benchmarks described as near Opus 5 at much lower cost.
  • Practical high-value default for coding agents.
Read full story

Meta’s Muse Spark 1.3 is now available in Cursor

Cursor announced that Muse Spark 1.3 from Meta is now available in the Cursor coding agent, so users can select the model directly in the product.

Key Takeaways

  • Cursor announced that Muse Spark 1.3 from Meta is now available in the Cursor coding agent, so users can select the model directly in the product.
Read full story
Linked Models & Agents:

Meta Rolls Out Muse Spark 1.3 With Frontier Coding Performance Almost Too Cheap to Meter

Mark Zuckerberg announced Muse Spark 1.3 in Muse Code and the Meta Model API, calling it Meta’s biggest jump yet on coding and agentic work, with frontier performance almost too cheap to meter. Meta Superintelligence Labs followed with a 1.3 max reasoning tier for even stronger coding agents, and teased upcoming open-weight releases.

Key Takeaways

  • Positioned as Meta’s most capable model yet, with the largest gain so far on coding and agentic workloads
  • Available now in Muse Code and the Meta Model API, and already a top-3 model by OpenCode usage
  • Muse Spark 1.3 max adds a higher-reasoning coding tier; a larger 🍉 model and open weights are next
Read full story
ADSponsored

Meta Releases Muse Spark 1.3 Max with Stronger Coding and Agents

Meta Superintelligence Labs chief Alexandr Wang publicly released Muse Spark 1.3 max reasoning. Meta reports significantly stronger coding and agentic performance versus 1.3 high and xhigh, after completing safety testing. It is available on Muse Code and the Meta Model API; users can set reasoning to max or install Muse Code from the terminal.

Key Takeaways

  • Max reasoning clearly outperforms 1.3 high and xhigh on coding and agent tasks
  • Released after safety testing on Muse Code and the Meta Model API
  • Try it by setting reasoning to max or installing Muse Code from the terminal
Read full story
Linked Models & Agents:
⚡ Muse Spark 1.3 Max🤖 Muse Code🌐 Meta

Command Code ships Muse Spark 1.3 Contributor: Opus 5 / GPT-5.6 Sol-class results at lowest cost

Command Code says Meta Muse Spark 1.3 Contributor is now live in its coding agent across GOAT, Pro, Max, and API. It calls the tier the most capable lowest-cost option yet, with benchmark results in the Opus 5 and GPT-5.6 Sol class.

Key Takeaways

  • Muse Spark 1.3 Contributor is live in Command Code (GOAT / Pro / Max / API).
  • Positioned as best price-performance in-class vs Opus 5 and GPT-5.6 Sol-tier results.
  • Lets coding-agent users cut long-horizon token spend without leaving the harness.
Read full story
Linked Models & Agents:

LMArena: Muse Spark 1.3 (xHigh) back in Code Arena WebDev top 10 at 1623 AutoEval

LMArena says Meta Muse Spark 1.3 (xHigh) lands ~#10 on Code Arena: WebDev with 1623 AutoEval pts, near Claude Fable 5 (#8, 1628) and GPT-5.6 Sol (#11, 1616). That is a large jump from Muse Spark 1.1 (#25, 1540) and 1.2 xHigh (#30, 1534). Scores are early AutoEval and may shift as live human votes arrive.

Key Takeaways

  • WebDev AutoEval ~1623, back in top 10, near Fable 5 and GPT-5.6 Sol.
  • ~80+ point jump vs Muse Spark 1.1 / 1.2 xHigh.
  • Early reward-model AutoEval; live human votes may move the rank.
Read full story
Linked Models & Agents:

Artificial Analysis: GPT-6 Astra ties Fable 5 on Coding Agent Index at ~half the cost

Artificial Analysis rated GPT-6 Astra: Coding Agent Index 67 in Codex, roughly matching Claude Opus 5 / Fable 5 in Claude Code and Muse Spark 1.3 in Muse Code, with ~70% better token efficiency vs GPT-5.6 Sol (max). List price rises to $10/$50 per 1M in/out (2.5× Sol), yet per-task cost stays well below Fable 5. Intelligence Index stays 61, tied with Sol.

Key Takeaways

  • Coding Agent Index: 67 in Codex, near Opus 5 / Fable 5 / Muse Spark 1.3; Fable 5.1 still leads at 70.
  • ~2/3 fewer tokens vs GPT-5.6 Sol (max); multiple effort levels sit on the token-efficiency Pareto frontier.
  • List price $10/$50 (90% cache-read discount); Intelligence Index 61; hallucination rate ~92%→~51%.
Read full story

Command Code FlappyBench: Muse Spark 1.3 and Grok-4.6 score 9/10, Muse costs least

Command Code ran FlappyBench with the same /design prompt across Muse Spark 1.3, Grok-4.6, and Gemini 3.8 Flash. Muse and Grok both scored 9/10, while Muse cost only $0.072; Gemini scored 7/10, cost $0.205, and did not fully finish.

Key Takeaways

  • Muse Spark 1.3: 9/10 at $0.072, completing the UI in two iterations at the lowest cost.
  • Grok-4.6: 9/10 at $0.095, matching Muse output quality, though the post describes it as roughly twice the cost.
  • Gemini 3.8 Flash: 7/10 at $0.205, the highest cost of the three and not fully finished.
Read full story
Linked Models & Agents: