AI Coding Live News

Artificial Analysis Ships Endpoint Accuracy Index v1.1: Nearly 1 in 4 of 100+ Serverless Endpoints Score Below Reference

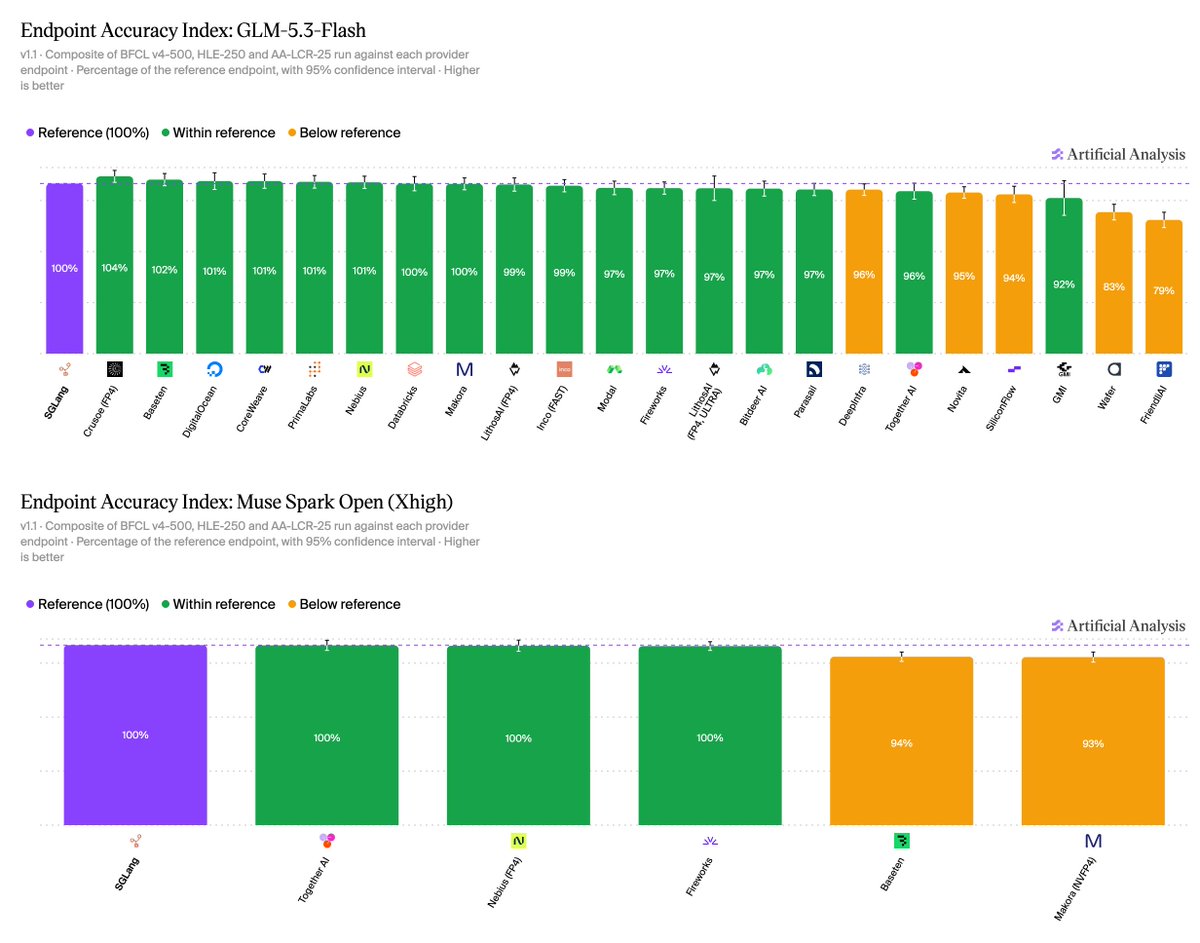
On 2026-11-06 Artificial Analysis launched Endpoint Accuracy Index v1.1: each serverless endpoint is scored as a percentage of a self-hosted official-weights reference across equally weighted BFCL-500, HLE-250, and AA-LCR-25. Vendor claim: nearly 1 in 4 of 100+ benchmarked endpoints score below the reference. AA-LCR-25 moved to v1.1 with repeats raised from 10 to 25 (average 95% CI ~±4.7 to ±2.6), and coverage expanded to six open-weights models including GLM-5.3 Flash and Muse Spark Open.
Artificial Analysis Ships Endpoint Accuracy Index v1.1: Nearly 1 in 4 of 100+ Serverless Endpoints Score Below Reference

Key Takeaways

  • Official: @ArtificialAnlys 2026-11-06 02:44 UTC; changelog 05 Nov 2026; methodology Endpoint Accuracy Index v1.1
  • Vendor claim: nearly 1 in 4 of 100+ serverless endpoints score below the self-hosted reference; providers often quantize, custom-kernel, tune stacks, or cap outputs
  • Equal-weight suite: BFCL v4-500 (3 repeats), HLE-250 (10), AA-LCR-25 (25); 95% CIs vs reference with significance flags
  • GLM-5.3 Flash: 16 of 22 endpoints statistically in line, one ~104.2; ~32K output caps scored ~22%/29% on HLE-250 vs 55% reference
  • Muse Spark Open: 3 of 5 endpoints ~99.5–99.9 (incl. FP4); two mainly lose on tool calling (BFCL-500 ~50%/51% vs 59%)
Read full story

Google AI Studio Opens Gemini 4 Argon in Build & Playground for Pro Users; Transformers v5.20.1 Adds Native Reflection AI Beam and Meta 816B Muse Spark Open

Google AI Studio launched Gemini 4 Argon access in AI Studio Build and Playground for Google AI Pro subscribers, while Hugging Face Transformers v5.20.0 and v5.20.1 added native support for Reflection AI's frontier coding model Beam, Meta's 816B-parameter (42B active, 1M context) multimodal agentic coding model Muse Spark Open, InclusionAI's Ling 3.0 Flash, and OpenBMB's MiniCPM-V 4.7.

Google AI Studio Opens Gemini 4 Argon in Build & Playground for Pro Users; Transformers v5.20.1 Adds Native Reflection AI Beam and Meta 816B Muse Spark Open

Key Takeaways

  • Google AI Studio opens Gemini 4 Argon in AI Studio Build and Playground (https://ai.studio/build) for Google AI Pro subscribers
  • Hugging Face Transformers v5.20.1 natively integrates Reflection AI's token-efficient coding model Beam and fixes DeepGEMM Mega MoE under expert parallelism
  • Adds native support for Meta's 816B-parameter (42B active, 1M context, BF16/NVFP4) omni-modal coding model Muse Spark Open and InclusionAI's KDA+MLA hybrid Ling 3.0 Flash
Read full story
Linked Models & Agents:

Meta open-sources Muse Spark Open: 816B-total / 42B-active MoE with 1M context, billed as the most capable US open-weight model to date

On 2026-10-15 Meta released weights for Muse Spark Open, a natively multimodal MoE (~816B total / ~42B active per token, 1M context) aimed at long-horizon coding and agents. Weights are on Hugging Face and peers; hosted APIs include Together, Fireworks, Groq and OpenRouter. Reported figures include DeepSWE 60%, MCP-Atlas 89.2% and JobBench 61.8% (see Meta’s evaluation methodology).

Meta open-sources Muse Spark Open: 816B-total / 42B-active MoE with 1M context, billed as the most capable US open-weight model to date

Key Takeaways

  • Scale: ~816B total / ~42B active per token; 256 experts/layer with top-8 routing; 62 layers, hidden 8192; context up to 1,048,576 (HF blog)
  • Coding/agents (Meta scorecard / AA, xhigh): DeepSWE 60.0%; SWE-Atlas Codebase QnA 58.0%; MCP-Atlas 89.2%; JobBench 61.8%; Toolathlon-Verified 72.8% (eval methodology)
  • Throughput (NVIDIA tech blog, agentic on GB300 NVL72): up to ~50K tok/s/GPU and ~600 tok/s/user; NVFP4 checkpoints published (NVIDIA blog)
  • Deploy: Muse Model License with limited commercial terms; SGLang / vLLM / TensorRT-LLM / MLX / llama.cpp; Meta demos two Apple M5 Ultra Mac Studios for on-desk local run
  • Third-party index: Artificial Analysis Intelligence Index ~38.9–39 (xhigh, as of 2026-10-07)—behind closed frontier, but a key open-weight reference (AA)
Read full story
Linked Models & Agents:
⚡ Muse Spark Open⚡ Muse Spark Open 816B-A42B🤖 Muse Code🌐 Meta🌐 NVIDIA🌐 Hugging Face🌐 Apple

Meta open-sources Muse Spark Open: 816B/42B natively multimodal US open-weight flagship, runs on two M5 Ultra Mac Studios

On 2026-10-15 Meta released Muse Spark Open open weights: an 816B-total / 42B-active MoE with a Perception Encoder, natively multimodal (text/image/video/audio in → text out), 1M context, aimed at coding and long-horizon agents. Weights are on Hugging Face (BF16/NVFP4), SageMaker, Model Garden and Foundry; APIs include OpenRouter, Together, Fireworks and Groq. Meta calls it the most capable US open-weight model to date and, with Apple, optimized it to run locally across two M5 Ultra Mac Studios via MLX.

Meta open-sources Muse Spark Open: 816B/42B natively multimodal US open-weight flagship, runs on two M5 Ultra Mac Studios

Key Takeaways

  • Specs: MoE 816B total / 42B active (256 experts, top-8), 62 layers, 1M context; text+image+video+audio in → text out (model card)
  • Local: NVFP4 needs ≥~700GB VRAM, BF16 ~2TB; or two Apple M5 Ultra Mac Studios via MLX (Meta blog)
  • Agentic benches (xhigh, official table): MCP-Atlas 89.2, JobBench 61.8, OSWorld Verified 80.4, Terminal-Bench 2.1 76.4, DeepSWE 1.1 60, AA Intelligence Index 39
  • Serve with SGLang / vLLM / TensorRT-LLM / Transformers / llama.cpp / Unsloth / MLX; Helion kernels claim 1.03–3.95× kernel speedups on NVIDIA/AMD
  • License: Muse Model License (display “Built with Muse Spark Open”; MaaS over $20M/yr needs a separate deal); OpenRouter ~$1.25/M in, $4.25/M out
Read full story
Linked Models & Agents:
ADSponsored