AI Coding Live News

Perplexity Cuts Agent API Effort-Level Costs and Adds Ultra: Medium Nearly 90% Cheaper; Ultra ~85.9% WANDR

On November 5 Perplexity Developers (@perplexitydevs) said every Agent API effort level now costs less per query with equal or better research quality, and added an ultra tier for broad long-running research. Vendor figures: medium rose from ~55% to ~77% on BrowseComp/DSQA with nearly 90% lower cost; xhigh held ~76.5% WANDR at ~25% of August 2026 cost; ultra runs three parallel researchers plus a consolidator at ~85.9% WANDR and about $21.71/task.

Perplexity Cuts Agent API Effort-Level Costs and Adds Ultra: Medium Nearly 90% Cheaper; Ultra ~85.9% WANDR

Key Takeaways

  • Official (@perplexitydevs + blog): every effort level cheaper with equal/better quality; new ultra
  • Vendor: medium BrowseComp/DSQA ~55%→~77% with nearly 90% lower cost
  • Vendor: xhigh WANDR ~76.5% at ~25% of August 2026 cost
  • ultra: 3 parallel research agents + consolidator; WANDR ~85.9% at ~$21.71/task on Claude Opus 5.5
  • Use effort="ultra" or pin [email protected]; background mode for long runs
Read full story

BoxWorks 2026: Box and NVIDIA Unveil Box Context Retrieval, Permission-Aware Retrieval for Enterprise Agents Built on Nemotron Retriever, Plus Box Architect and Box Mount

At BoxWorks 2026 on November 5, Box announced an expanded NVIDIA collaboration: Box Context Retrieval, a new engine built on NVIDIA Nemotron Retriever embedding models, combines keyword and semantic search to return the most relevant passages to AI agents while honoring existing file permissions, with general availability for Enterprise Advanced customers planned for early next year. Box's press release claims 20% better search accuracy (Recall@5), 90% fewer tokens and 4x faster answers. Open-weight Nemotron models, starting with Nemotron 3 Ultra, are available in Box AI now. Box also unveiled Box Architect, which designs workflows from a stated goal; Box Mount, which mounts Box folders inside agent sandboxes and works with NVIDIA OpenShell; and agent security controls including MCP Guardrails.

BoxWorks 2026: Box and NVIDIA Unveil Box Context Retrieval, Permission-Aware Retrieval for Enterprise Agents Built on Nemotron Retriever, Plus Box Architect and Box Mount

Key Takeaways

  • Box Context Retrieval uses NVIDIA Nemotron Retriever with hybrid keyword and semantic search, honoring existing file permissions
  • Vendor claims: +20% Recall@5 accuracy, 90% fewer tokens, 4x faster answers; GA for Enterprise Advanced early next year
  • Open-weight Nemotron models, starting with Nemotron 3 Ultra, are available in Box AI now
  • Box Mount puts Box folders inside agent sandboxes and works with the NVIDIA OpenShell secure runtime
  • New agent security controls include MCP Guardrails, classification-based access policies and audit trails
Read full story
Linked Models & Agents:
⚡ Nemotron 3 Ultra⚡ Nemotron Retriever🌐 box🌐 Nvidia (NIM)

Anthropic: Claude Helps Map the First Prokaryotic Vault Particle Structure; Purification in ~90 Minutes, First Model in ~34 Hours

On November 4 Anthropic's biology team reported that Claude helped determine the first 3D vault structure from a prokaryotic/phage system (protein L05). Vendor-reported timing: ~90-minute purification and a first model in ~34 hours, plus an open discussion of mistakes and the multi-agent research workflow.

Anthropic: Claude Helps Map the First Prokaryotic Vault Particle Structure; Purification in ~90 Minutes, First Model in ~34 Hours

Key Takeaways

  • Official Anthropic research: Claude helped determine the first 3D prokaryotic/phage vault structure (protein L05)
  • Vendor-reported timing: purification cut from ~3 days to ~90 minutes; first model ready in ~34 hours
  • L05 forms a ~9.5 MDa shell of 96 chains with ~25% more volume than mammalian vaults
  • Anthropic also discloses failures: a medium additive cost ~2 weeks; an early cryo-EM map was mirrored
  • For developers: a concrete case of a science multi-agent harness with human oversight, not biology trivia
Read full story
Linked Models & Agents:
⚡ Anthropic Claude🤖 claude🌐 Anthropic

Google Antigravity v2.29 Brings Remote Agents and a Gemini Live Voice Mode: Agent Sessions Run in a Google-Managed Cloud and Keep Working After You Close Your Laptop, Rolling Out to AI Pro and Ultra

Ivan Leo, who works on developer experience at Google DeepMind, shared the official docs for Antigravity's new Remote Agents feature on X on November 4. Per the docs, Remote Agents run agent sessions and tools in an isolated, Google-managed remote environment, so tasks keep going when you close your laptop or browser or switch between desktop and mobile. Sessions start from the Antigravity App, the Antigravity CLI (1.4.12+, agy --remote-agent) or the web at antigravity.google.com, and remote projects can attach GitHub repositories, Google Drive files and uploads. It is rolling out gradually to Google AI Pro and Ultra subscribers on personal accounts; it is not available on the free plan, AI Plus or business accounts. The official changelog shows this ships in Antigravity v2.29.0 (November 3), which also starts rolling out a voice mode powered by Gemini Live for handing requests to the agent by voice, redesigns the Automations page into Scheduled, Always on and Paused lists, and adds a native Jupyter notebook viewer.

Key Takeaways

  • Remote Agents run in an isolated Google-managed environment with no local machine required; Remote Control instead connects to your own computer or server, and the web sidebar switches between them.
  • Three entry points: a New Remote Project in the Antigravity App, agy --remote-agent in CLI 1.4.12+, or antigravity.google.com in any browser, including mobile.
  • Remote projects can attach GitHub repositories (cloned automatically), Google Drive files and uploads (8 MiB per file, 100 MiB per project, 2 GiB per account).
  • CLI remote sessions default to the always-proceed (turbo) permission preset, so commands run without approval; locally installed MCP servers, plugins and skills are not available remotely yet.
  • Also in v2.29.0 (November 3): a Gemini Live voice mode rolling out gradually, a redesigned Automations page, and native rendering of .ipynb notebooks.
Read full story
ADSponsored

AMD Q3 2026: Data Center Revenue Up 97% to $8.5B, First Helios Racks Running for Anthropic and OpenAI, Q4 Guide About $17B

AMD reported Q3 2026 results on November 3. Total revenue was $13.377B, up 45% year over year, and the Data Center segment hit a record $8.546B, up 97% year over year and 27% sequentially, driven by EPYC server CPUs and the newly launched Instinct MI450 Series GPUs. AMD says Anthropic, Meta, Microsoft, OpenAI and Oracle Cloud Infrastructure are running models and workloads on the first Helios rack-scale systems. It guided Q4 revenue to about $17B, plus or minus 3%, roughly 66% year-over-year growth at the midpoint.

Key Takeaways

  • Data Center revenue was $8.546B, up 97% year over year and 27% sequentially, about 64% of total revenue versus roughly 47% a year ago; segment operating income was $2.882B at a 34% margin
  • The first Helios racks (Instinct MI450 Series GPUs plus 6th Gen EPYC) are running models for Anthropic, Meta, Microsoft, OpenAI and Oracle Cloud, and MI455X began volume shipments this quarter
  • Total revenue was $13.377B (+45%), with 56% non-GAAP gross margin and $2.09 non-GAAP EPS; GAAP net income of $2.428B includes a $1.097B fair-value change on customer warrants
  • Q4 guidance is about $17B plus or minus 3%, roughly +66% year over year and +27% sequentially at the midpoint, with about 55% non-GAAP gross margin
  • AMD also released ROCm 10 with ROCm.AI, introduced the Helion reference architecture for rack-scale agentic systems, and announced agreements to acquire World Labs and Taalas
Read full story

Axion 1.0 Open Agent Foundation Model: Two SFT Stages Plus RL, 35B-A3B Reproduction Checkpoint Under Apache 2.0, Full Recipe Released

arXiv paper 2611.03233 by Yuqi Jia, Yunjie Tian and five co-authors introduces Axion 1.0, an agent foundation model that is open beyond its weights. It uses just two lightweight SFT stages plus reinforcement learning, with no dedicated mid-training, DPO or on-policy distillation, and about 18K SFT trajectories in total. Training code is hosted under the bytedance GitHub organization, and the training data and an Axion 1.0-35B reproduction checkpoint (Qwen3.6-35B-A3B base, 35B total / 3B active, Apache 2.0) are on Hugging Face; weights for the paper's 122B model are listed as coming soon.

Axion 1.0 Open Agent Foundation Model: Two SFT Stages Plus RL, 35B-A3B Reproduction Checkpoint Under Apache 2.0, Full Recipe Released

Key Takeaways

  • A minimal recipe: SFT stage one for self-contained scientific reasoning, stage two for tool use and information seeking, then RL for long-horizon interaction, with 18,363 SFT trajectories and 484 RL tasks
  • The release covers data construction, generation, filtering, verification, prompts and training code (GitHub), not just weights
  • The 35B reproduction checkpoint scores 52.8 on HLE, 60.4 on SEAL-0, 85.0 on FrontierScience Olympiad and 55.0 on FrontierScience Research (HF model card)
  • The paper's 122B model reports 59.0 on HLE with restricted website access and 66.7 on FrontierScience Research; 122B weights are not out yet
  • All scores are self-reported; the HF card lists Claude Opus 5 at 63.6 on HLE, so Axion still trails the strongest closed models
Read full story
Linked Models & Agents:
⚡ Axion 1.0-35B⚡ Axion 1.0-122B⚡ Qwen3.6-35B-A3B🌐 ByteDance🌐 Hugging Face

X Discussion: Grok Bot Engineer poteto Calls Adversarial Agent Code Reviews "Mostly a Waste of Tokens" and Argues for Empirical Plus Formal Verification Instead

On November 3, @poteto (lauren), whose bio says she works on Grok @bot at SpaceXSI, is on the React Compiler core team, and previously worked at Cursor, Meta and Netflix, posted what she called "maybe a hot take": she now considers adversarial reviews mostly a waste of tokens and thinks those tokens are far better spent on empirical combined with formal verification. She says she has updated her agent skill pack pstack to use its interrogate (multi-model adversarial review) skill less and may eventually remove it. She adds that she has found very little value in code review in the abstract, because agents tend to get lost in nitpicks and YAGNIs. The post drew about 906K views, 9,227 likes and 5,538 bookmarks. It is a personal opinion that sparked debate over the value of AI code review.

Key Takeaways

  • Opinion (personal, not an official finding): adversarial reviews are "mostly a waste of tokens"; empirical plus formal verification is the better use of them
  • Action: the author says she has made pstack use the interrogate skill less and may remove it; at fetch time the public pstack folder in GitHub cursor/plugins had no commits after October 27, so the change is not visible there yet
  • What interrogate is: per its public SKILL.md, it spawns one read-only reviewer per configured model (defaults Claude Opus 5.5 xhigh and Grok 4.7 xhigh fast) to attack the diff, then sorts findings into Act on, Consider, Noted and Dismissed without auto-applying fixes
  • Author (per her X and GitHub bios): engineer on Grok Bot at SpaceXSI, React Compiler core team, previously at Cursor, Meta and Netflix
  • Reach: about 906K views, 9,227 likes, 5,538 bookmarks, 668 replies, 356 reposts and 210 quotes
Read full story

Grok Bot Rolls Out a New Shopping Experience: Find the Best Deal, Compare Product Cards, and Track Orders After You Approve the Buy

On November 3, the official Grok Bot account @bot posted a video promoting a new shopping experience: have the Bot find the best deal, compare items, and track all your orders. The features come from the official changelog for version 0.78.1 (which includes 0.78.0), dated October 27: products appear as cards with photo, rating, price and store plus up to two badges, and three or four results scroll in a carousel. Product pages list in-stock options first, and Buy now starts an order you approve. After purchase the Bot tracks shipping and delivery, with shipment cards showing carrier and stage. Shop Pay can be connected in the Vault Payments tab and set as the preferred method.

Grok Bot Rolls Out a New Shopping Experience: Find the Best Deal, Compare Product Cards, and Track Orders After You Approve the Buy

Key Takeaways

  • The official post went out at 21:50 UTC on November 3 with a 17-second demo video; about 1,687 likes, 122 reposts, 292 replies and 112K views at fetch time
  • Source of the features: the official 0.78.1 changelog entry (October 27, includes 0.78.0), titled Shopping cards and subscription templates
  • Product cards: photo, rating, price and store, up to 2 badges such as Top rated, 3 or 4 results in a carousel; product pages list in-stock options first and disable options no store has
  • Ordering and tracking: orders started with Buy now need your approval; afterward the Bot reports shipping and arrival, and shipment cards show carrier and stage
  • Payments: the Vault has had a Payments tab since 0.77.0 (October 26); 0.78.1 lets you connect Shop Pay and make it the method Bots use first
Read full story
Linked Models & Agents:

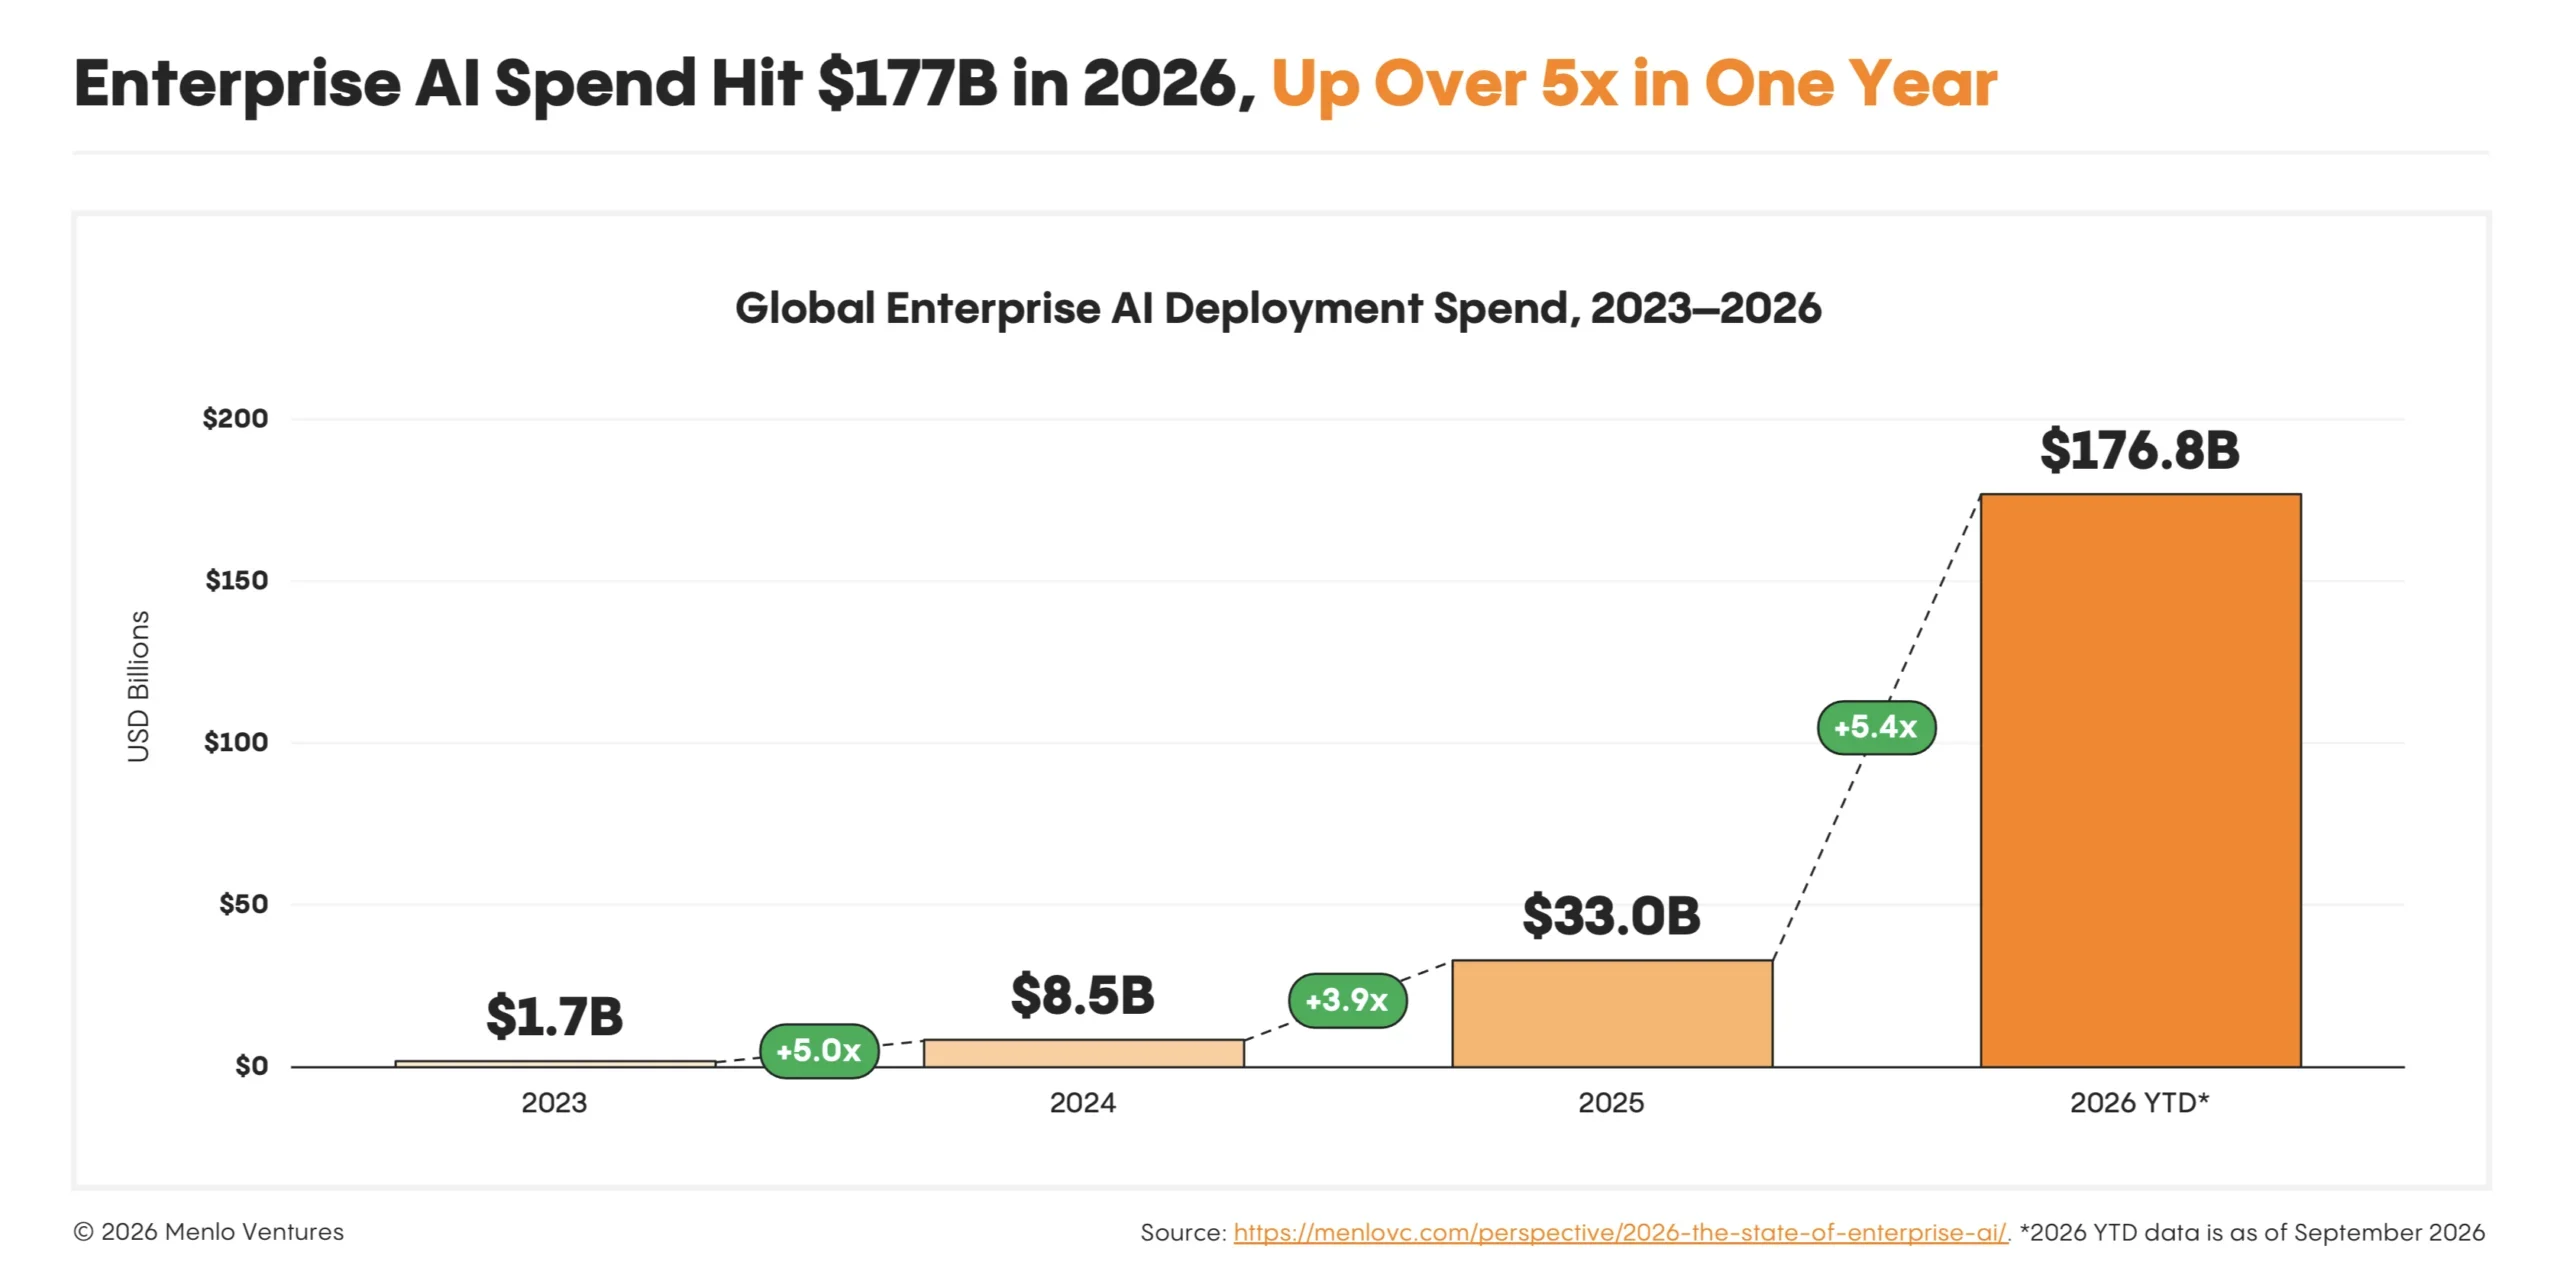
Menlo Ventures 2026 State of Enterprise AI: Enterprise AI Spend Hits $176.8B, Up 5.4x, as Anthropic Takes 55% of Enterprise API Spend

On November 3, Menlo Ventures released its fourth annual enterprise AI report. It estimates enterprise spending on using AI reached $176.8B by September 2026, up 5.4x from $33B in 2025. In enterprise LLM API spend, Anthropic rose from 40% to 55%, OpenAI from 27% to 31%, and Google fell from 21% to 9%. Coding is the largest app category at $34.0B. Figures come from a survey of about 400 US enterprise AI decision-makers plus third-party data, so they are estimates; Menlo is an Anthropic investor.

Menlo Ventures 2026 State of Enterprise AI: Enterprise AI Spend Hits $176.8B, Up 5.4x, as Anthropic Takes 55% of Enterprise API Spend

Key Takeaways

  • Enterprise AI deployment spend: $1.7B (2023) to $8.5B (2024) to $33B (2025) to $176.8B by Sep 2026, up 5.4x vs 3.9x last year (Menlo estimate)
  • Enterprise LLM API spend share: Anthropic 55% (from 40%), OpenAI 31% (from 27%), Google 9% (from 21%); open-source models are about 19% of usage but only 4% of spend
  • App-layer spend is about $77.3B: coding $34.0B and chatbots/productivity $25.0B make up 76%; Claude Code and Codex account for $24.0B (70%) of coding spend
  • On OpenRouter, agents generate 80% of tokens (about 130.9T per week), roughly 7x human usage, and have grown 37x since overtaking human traffic in February
  • 55% of incremental AI spend comes from net-new budgets and 22% from existing software budgets; the share of enterprises paying for AI rose only from 55% to 65%
Read full story

Flower Labs Releases Endeavor 1.1: Multimodal, EU-Only Inference and Private Deployment With Readable Thinking Traces, Claims Parity With OpenAI and Anthropic

Flower Labs, the company behind the Flower federated learning framework, released Endeavor 1.1 on November 3, its third model this year after the UK sovereign 7B model Lizzy in April and Endeavor 1.0 in September. The update adds image input, an optional EU-only GPU inference tier, and Flower-managed, private-cloud or on-premises deployment, and promises readable thinking traces plus ownership of outputs that customers may use to train their own models. Vendor-reported scores are GPQA 94.4, HumanEval 99.9, AIME 2026 99.9 and MMMU-Pro 81.1, but the comparison uses GPT-5.6 Sol and Claude Fable 5 rather than either lab's newest models, and access is request-only for now.

Flower Labs Releases Endeavor 1.1: Multimodal, EU-Only Inference and Private Deployment With Readable Thinking Traces, Claims Parity With OpenAI and Anthropic

Key Takeaways

  • Vendor-reported: GPQA rose from 92.0 in 1.0 to 94.4 (about 30% fewer errors), HumanEval from 98.2 to 99.9; IFEval is 94.5 and MMMU-Pro 81.1.
  • In the vendor table, GPT-5.6 Sol scores GPQA 94.1, IFEval 95.9 and MMMU-Pro 83.0, and Claude Fable 5 scores GPQA 92.6; Endeavor does not lead on IFEval or MMMU-Pro.
  • New EU-only GPU inference with SLAs, with UK, Middle East, Asia and Africa regions planned.
  • The pitch is control: raw thinking traces, ownership of outputs and traces, and the right to fine-tune or train your own models on them.
  • Flower says the model builds on mature open-weight models via continual pre-training, targeted post-training and model integration, without naming the base or parameter count; access is request-only.
Read full story
Linked Models & Agents:
⚡ Endeavor 1.1⚡ Endeavor 1.0⚡ GPT-5.6 Sol⚡ Claude Fable 5⚡ Kimi K3⚡ Nemotron 3 Ultra🌐 Flower Labs
ADSponsored

Anthropic Launches Message Threads in Public Beta on the Messages API: Server-Side Conversations Cut Claude Code TTFT About 35% on 500K-1M Token Requests

On November 2 (US time) Anthropic put message threads into public beta on the Messages API (beta header message-threads-2026-08-12). The API keeps the conversation on the server: the first request sends the full conversation and creates a thread, and each later request sends only new messages plus the previous response id. Anthropic says threads are on by default for most Claude Code users, cutting median time to first token by about 35% on 500K-1M token requests, while the median long-conversation request shrank from about 800 KB to 1.8 KB. Threads expire after 5 idle minutes; pricing and rate limits are unchanged.

Anthropic Launches Message Threads in Public Beta on the Messages API: Server-Side Conversations Cut Claude Code TTFT About 35% on 500K-1M Token Requests

Key Takeaways

  • Per Anthropic, median time to first token on 500K-1M token Claude Code requests is about 35% lower.
  • The median long-conversation request fell from about 800 KB to about 1.8 KB, since each turn uploads only new messages plus previous_message_id.
  • A thread expires 5 minutes after its last request and is deleted within 1 hour; an expired thread returns 404 thread_not_found and must be replayed in full.
  • Pricing and rate limits are unchanged; Message Batches, token counting and on-demand compaction are unsupported, and threads are not ZDR or HIPAA eligible.
  • Available on the Claude API, Claude Platform on AWS, Google Cloud (Anthropic managed) and Microsoft Foundry, with a thread helper in the SDKs.
Read full story
Linked Models & Agents:

Deep Principle Open-Sources Hydrogen-1.0, a 753B Science Model Post-Trained From GLM-5.3 on Lab Records, MIT Licensed

Hangzhou-based AI-for-science company Deep Principle released Hydrogen-1.0 on November 2, its first general-purpose scientific model. It post-trains Zhipu's GLM-5.3 with SFT and RL on chemistry, materials and life-science data plus its own lab records and discovery trajectories, and ships about 753B parameters of BF16 weights on Hugging Face under the MIT license. By the vendor's own evaluation it scores 38.3% on FrontierScience-Research versus 33.3% for GPT-6 Astra; none of the results have been independently reproduced yet.

Deep Principle Open-Sources Hydrogen-1.0, a 753B Science Model Post-Trained From GLM-5.3 on Lab Records, MIT Licensed

Key Takeaways

  • Scale: Hugging Face lists about 753B total parameters (BF16, roughly 1.5 TB of weights), glm_moe_dsa architecture, 1M-token context and 128K max output, MIT licensed (download requires accepting HF terms).
  • Benchmarks (vendor-reported): 38.3% on FrontierScience-Research vs 33.3% for GPT-6 Astra; 93.0% on GPQA Diamond, which the company says roughly matches Kimi K3.
  • Internal scenarios (vendor-reported): leads max-thinking GPT-6 Astra by 5.13 points on scientific computing and 4.76 points on forward reaction prediction, but trails it by 3.33 points on NMR structure elucidation.
  • Materials discovery: after five rounds of transition-metal-complex search, the mean best HOMO-LUMO gap reached 4.318 eV vs 3.689 eV for GPT-6 Astra and 3.353 eV for Kimi K3 (official blog).
  • Access: weights on HF and ModelScope, plus NVFP4 (B200/B300) and MXFP4 (MI350X/MI355X) quantized repos; API via NeuroSpark and in-app use in the Mira AI Scientist; tested with SGLang on 8 GPUs.
Read full story

X discussion: an indie developer compiles an NPU into Qwen3.5-4B weights and runs Karpathy's stories260K, an LLM inside an LLM

A widely discussed experiment on X: on Oct 31 indie developer div (@divagr1925) showed QwenPU, which compiles a 32-bit RISC-V CPU plus a vector unit directly into the weights of Qwen3.5-4B and runs Andrej Karpathy's 260K-parameter stories260K inside the model's own forward passes, matching a reference implementation token for token. None of the added weights are trained; a compiler computes them all. The post drew about 1,540 likes, 163 reposts and 85K views and became an X trending story. It is a personal, self-described work-in-progress project: the checkpoint is 26.7 GB and one story token takes about 16 seconds on an L4. This is a write-up of the discussion, not an official announcement from any company.

X discussion: an indie developer compiles an NPU into Qwen3.5-4B weights and runs Karpathy's stories260K, an LLM inside an LLM

Key Takeaways

  • Buzz: the @divagr1925 post has about 1,540 likes, 163 reposts, 71 quotes and 85K views (public X metrics as of Nov 1); the earlier Qwenputer post (Oct 28) has about 5,880 likes and was quote-posted by Shopify CEO Tobi Lutke
  • Method: 13 compiled computer layers (RV32IM + Zba + a bignum unit + the vector unit) sit in front of Qwen's 32 layers, widening the hidden size from 2560 to 5120 while Qwen's own weights stay unchanged (GitHub README)
  • Efficiency: trace tokens per story token drop from 2.43M for plain C to 53K; at about 3,300 trace tokens per second on an L4, one story token takes about 16 seconds (author-reported)
  • Verification: the story program runs free on a GPU executor for all 3,184,920 steps, checked against a reference CPU model at every step, which the author says is exact; no independent reproduction has been published yet
  • Open source: code is MIT and weights are Apache-2.0 as a modified Qwen3.5-4B, on Hugging Face and ModelScope; the 26.7 GB checkpoint needs a 40 GB or larger GPU
Read full story
Linked Models & Agents:
⚡ Qwen3.5-4B⚡ stories260K🌐 Alibaba Qwen
O
OpenAIhelp.openai.com·
👀74
🔥83

OpenAI will pool ChatGPT and Codex into one token-based usage allowance starting in December for Plus, Pro, and Business; Instant chat is excluded

On Oct 31, OpenAI's Help Center added a page titled "Understanding ChatGPT and Codex usage limits": starting in December, the usage allowance on Plus, Pro, and Business plans will be shared across ChatGPT and Codex as OpenAI brings the agentic capabilities of Work into the main ChatGPT experience. Usage will be measured in tokens, so stronger models and more complex tasks use more; Instant chat will not draw from the allowance. Users will see combined remaining usage and reset times in Settings > Usage, and can wait for a reset, upgrade, or buy credits when they run out. OpenAI says it expects most users will not need to wait for resets more often than they do now, but it has not given an exact start date or per-plan allowances. The news drew strong concern from Plus users on X.

Key Takeaways

  • Timing: takes effect in December, exact date not announced; covers Plus, Pro, and Business plans (OpenAI Help Center)
  • Metering: everything is measured in tokens and Instant chat is excluded; the Business pricing page now also notes that plan usage will have a shared limit across ChatGPT and Codex starting in December (Business pricing)
  • Today's baseline: only Work and Codex share an allowance now; Plus is estimated at 5-45 local messages per 5 hours on GPT-6 Astra, 15-160 on GPT-6.1 Sol, and 350-3,000 on GPT-6 Luna (official estimates, help article)
  • Pro 100/200/500 currently have no 5-hour limit in Work and Codex; per-plan allowances after the merge have not been published
  • OpenAI's position: most users should not wait for resets more often than today; when out, wait, upgrade, or buy credits
Read full story

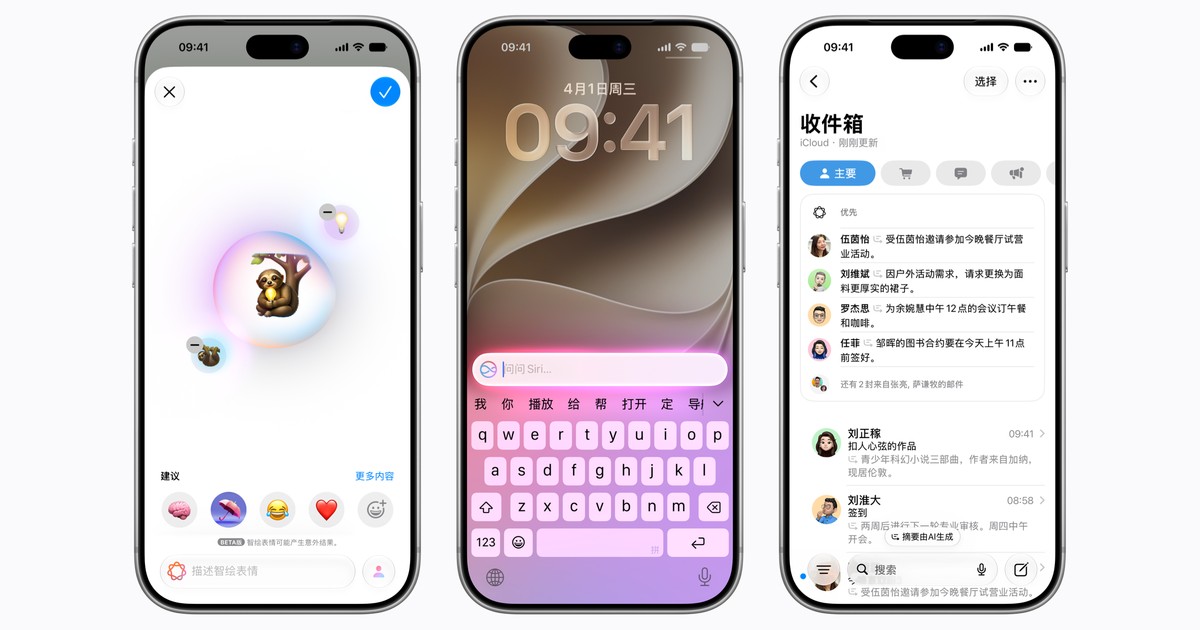
Apple Intelligence is coming to China: iOS 27.3 developer beta starts Nov 4, public release in December, with Alibaba Qwen inside Siri, Writing Tools and Visual Intelligence

In a press release on its China newsroom, Apple said the first Apple Intelligence features will open for testing in the latest iOS developer beta starting November 4 and reach users in China with the iOS 27.3 release in December. The features run on Apple-built generative models and include Live Translation, Writing Tools, Visual Intelligence, Clean Up, Genmoji, notification and Mail summaries, and Type to Siri; Apple also partnered with Alibaba to bring Qwen into Siri, Writing Tools and Visual Intelligence. The first wave covers iPhone 15 Pro and newer only; Siri AI and the other next-generation features announced at WWDC 2026, plus Image Playground, are not included, and Mac, iPad and other platforms wait on further approvals.

Apple Intelligence is coming to China: iOS 27.3 developer beta starts Nov 4, public release in December, with Alibaba Qwen inside Siri, Writing Tools and Visual Intelligence

Key Takeaways

  • Timeline (Apple): testing in the latest iOS developer beta from November 4, public rollout with iOS 27.3 in December, no exact date given
  • First-wave features include Live Translation (Messages, FaceTime, Phone and AirPods), Writing Tools, Visual Intelligence, Clean Up, Genmoji, natural-language photo search, Priority Mail, notification summaries and Type to Siri
  • Alibaba Qwen is built into Siri, Writing Tools and Visual Intelligence: users can ask about photos, PDFs and presentations and use Qwen to compose original text, signing in with a Qwen account or Sign in with Apple
  • Supported devices: iPhone 16 and later, iPhone Duo, iPhone 15 Pro/Pro Max and iPhone Air, with Siri and device language set to English and Simplified Chinese
  • Siri AI and other next-generation WWDC 2026 features are excluded, MacRumors says Image Playground is also missing, and other platforms follow after the necessary approvals
Read full story
Linked Models & Agents:
⚡ Qwen⚡ Apple Foundation Models🤖 Siri🌐 Apple🌐 Alibaba