AI Coding Live News

Hugging Face Ships Ultimate MoE Training Handbook: ~500k–800k GPU-Hours Distilled into a Megatron-LM Guide

On 2026-11-05 Hugging Face released the free Ultimate MoE Training Handbook. Co-founder Thomas Wolf cited ~800k GPU-hours, ~70k words and 55 interactive figures; author Nouamane Tazi separately cited ~500k GPU-hours. The Megatron-LM guide covers routing, expert sizing, communication and debugging via the official Space.

Hugging Face Ships Ultimate MoE Training Handbook: ~500k–800k GPU-Hours Distilled into a Megatron-LM Guide

Key Takeaways

  • Official: Hugging Face Space “The Ultimate MoE Training Handbook” (2026-11-05)
  • Thomas Wolf (HF co-founder) on X: ~800k GPU-hours, ~70k words, 55 interactive figures
  • Author Nouamane Tazi separately cited ~500k GPU-hours; prefer the Space body over a reconciled figure
  • Covers Megatron-LM: routing, expert sizing, all-to-all, aux vs loss-free bias, upcycling and serving
  • Free and open; small teams can follow the runbook flag-by-flag against logs
Read full story
Linked Models & Agents:
⚡ DeepSeek-V4 (Next-Gen MoE)⚡ Nemotron 3 Super⚡ Nemotron 3 Ultra🌐 Hugging Face🌐 NVIDIA

Fireworks Forge Launches: Ultra-fast Inference Preview Hits 1,500 Tokens/s, Half-Price Background Mode, Nexus Desktop for Codex and Claude Desktop, Sovereign Private Preview

At its first Forge conference on November 3, open-model inference platform Fireworks launched a batch of products. Ultra-fast, powered by NVIDIA Blackwell, is in public preview at up to 1,500 tokens per second on DeepSeek V4.1 Flash, cutting a 30-turn agent task from 1 minute to 8 seconds. Background Mode runs deferrable work at half price, alongside multi-day prompt caching and higher rate limits. Nexus Desktop brings open-model routing into the Codex app, Claude Desktop and OpenCode, with Pro plans from $8 per month. Fireworks also announced No Eval, serverless LoRA inference, the Fireworks Sovereign private preview and a 60+ partner Frontier Ecosystem.

Fireworks Forge Launches: Ultra-fast Inference Preview Hits 1,500 Tokens/s, Half-Price Background Mode, Nexus Desktop for Codex and Claude Desktop, Sovereign Private Preview

Key Takeaways

  • Ultra-fast public preview: on NVIDIA Blackwell, up to 1,500 tokens per second on DeepSeek V4.1 Flash; in Fireworks' benchmark a 30-turn agent task fell from 1 minute to 8 seconds (Fireworks blog)
  • Cost options: Background Mode runs deferrable work at half price; multi-day prompt caching cuts the cost of resuming long context; higher serverless rate limits and Elastic Burst are generally available
  • Nexus Desktop launches: personalized routing across open and closed models inside the Codex app, Claude Desktop and OpenCode; Pro from $8 per month, Teams from $10 per seat per month
  • Training: No Eval (private preview) turns production traces into task evals; serverless LoRA inference (public preview) starts with GLM 5.3 Flash at per-token pricing with no idle charge; free training on Muse Glimmer 30B through November 30
  • Enterprise: Fireworks Sovereign (private preview) runs the inference engine in a customer's own cloud or data center; Fireworks says it already manages over 25,000 GPUs in customer environments; plus a 60+ partner Frontier Ecosystem
Read full story

Anthropic Open-Sources FlashProve: zkSNARK Proofs That a Reply Came From the Committed Model, About 110 Tokens/s for 400B Llama 4 Maverick on One H100

Anthropic's Frontier Red Team published a research post on November 2 and open-sourced FlashProve under Apache 2.0. A model provider commits to hidden weights once, then attaches a zero-knowledge proof to each reply, so a user without the weights can check on an ordinary CPU that the reply really came from that model. That targets routing services that quietly swap in cheaper models and tampered token streams. Anthropic reports about 110 tokens/s on one H100 for Llama 4 Maverick (400B MoE, 4-bit), proofs of about 19 MB per 1,024-token request, and roughly 70-95x the GPU time of vLLM inference. It is an unmaintained research prototype limited to 1,024-token contexts and greedy decoding of an integer version of the model. Anthropic engineer Steve Weis shared the release on X.

Anthropic Open-Sources FlashProve: zkSNARK Proofs That a Reply Came From the Committed Model, About 110 Tokens/s for 400B Llama 4 Maverick on One H100

Key Takeaways

  • Anthropic-reported: on Llama 4 Maverick (400B MoE, 4-bit) one H100 proves about 110 tokens/s (prefill, 24 requests per batch), with proofs of about 19 MB per 1,024-token request.
  • It is costly: roughly 70-95x the GPU time of vLLM inference; the performance page lists about 270 GB of host memory for serving and about 39 minutes to commit to a set of weights.
  • Verification needs no GPU: the C++ verifier checks a proof in about 21 seconds on one thread, and a slower Lean verifier plus Lean 4 proofs of the security theorem are included.
  • Against prior work: VerInf proved the same model at about 0.02 tokens/s; the commercial Attestable reached 53-77 tokens/s on Gemma 4 31B but has no open-source release.
  • Limits: v0.16.0 is an unmaintained research prototype with 1,024-token contexts, greedy decoding of an integer model only, and no architecture hiding.
Read full story
Linked Models & Agents:
A
Anthropic@AICoder·
👀106
🔥80

Claude Code 2.1.314 adds a block on writes outside working directories, IdP group routing for the apps gateway, and idle compaction in VS Code and Desktop

Anthropic published Claude Code v2.1.314 on GitHub at 01:06 UTC on Oct 30. The official CHANGELOG lists 119 entries, more than half of them fixes. The new features lean enterprise: permissions.blockWritesOutsideWorkingDirectories makes Write, Edit and NotebookEdit refuse paths outside the working directories in every permission mode; Claude apps gateway upstreams can be limited to IdP groups, and Bedrock upstreams can log which guardrail fired; idle compaction now also runs in VS Code and the Code tab of Claude Desktop. It also fixes sessions failing repeatedly when an admin caps effort, and claude -p exiting 0 with no output when startup failed.

Key Takeaways

  • Size: the official v2.1.314 CHANGELOG has 119 entries, more than half of them fixes; released at 01:06 UTC on Oct 30
  • Safety: the new permissions.blockWritesOutsideWorkingDirectories setting stops Write, Edit and NotebookEdit from writing outside the working directories in every permission mode
  • Enterprise gateway: upstreams take an optional groups list so only developers in those IdP groups are routed there, failover included; Bedrock upstreams gain guardrail_trace
  • Experience: idle compaction now runs in VS Code and the Claude Desktop Code tab, summarizing idle conversations above 200K tokens
  • Fixes: when an admin caps effort, Claude Code lowers it and retries; a failed claude -p startup now prints the error and exits 1
Read full story
Linked Models & Agents:
ADSponsored

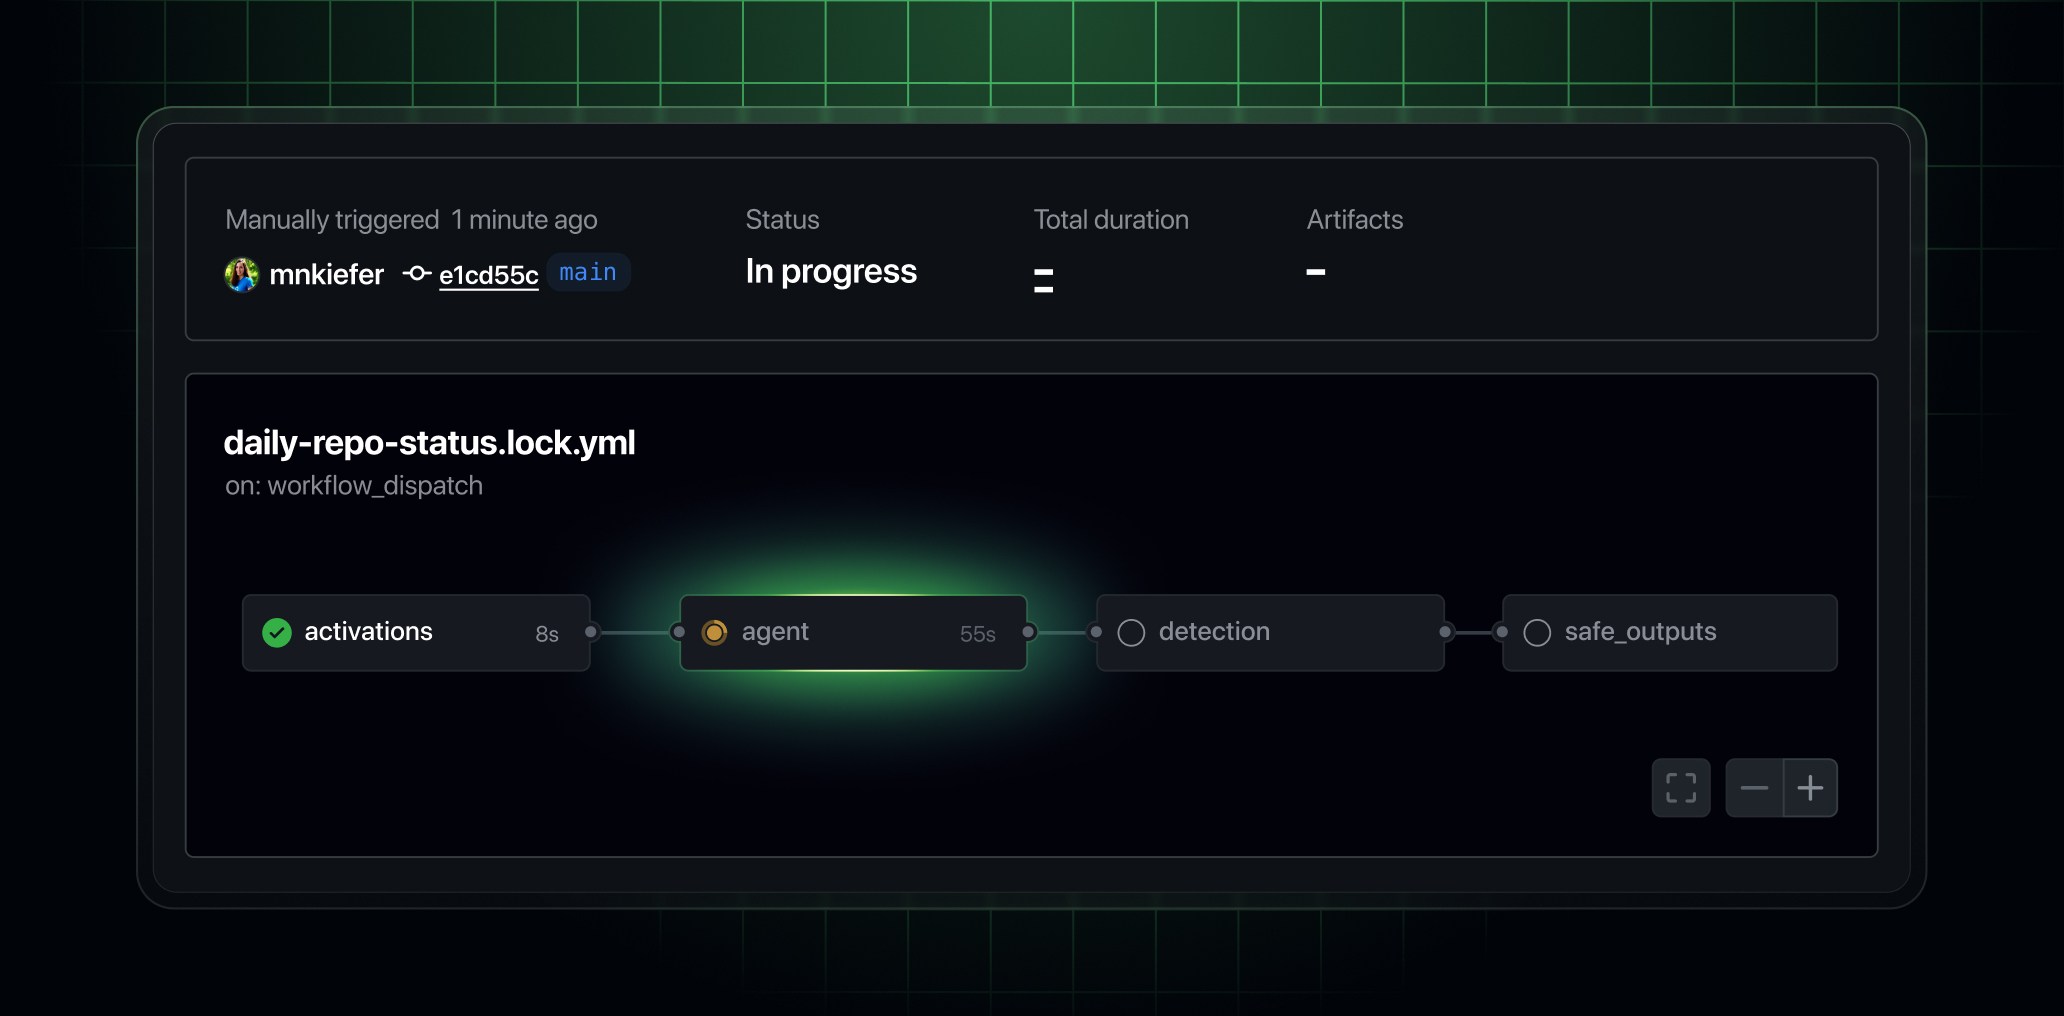
GitHub Agentic Workflows is generally available: write automation in Markdown, compile it to Actions YAML, run Copilot or your own coding agent, now with ARC self-hosting and micro-VM isolation

At Universe 2026 on Oct 28, GitHub made GitHub Agentic Workflows, an open source GitHub Next project, generally available on GitHub Free, Team and Enterprise. Developers describe tasks such as issue triage, CI failure analysis, documentation updates and test writing in natural-language Markdown, and gh aw compiles them into standard Actions YAML run by Copilot or a coding agent of their choice. GA adds self-hosted ARC runners with Docker-in-Docker, a non-experimental gh aw forecast cost estimate, per-workflow model providers and model routing, and Cloud Hypervisor or NVX micro-VM isolation.

GitHub Agentic Workflows is generally available: write automation in Markdown, compile it to Actions YAML, run Copilot or your own coding agent, now with ARC self-hosting and micro-VM isolation

Key Takeaways

  • Availability: GitHub Free, Team and Enterprise on github.com; using the default Copilot CLI engine requires a Copilot license
  • How it works: requirements in Markdown, compiled to standard Actions YAML that reuses existing runner groups and policies; run with Copilot or your own coding agent
  • Safe defaults: read-only permissions, a sandboxed container behind the Agent Workflow Firewall, safe-outputs validation, and a threat detection job before changes are applied
  • New at GA: self-hosted ARC runners with Docker-in-Docker, gh aw forecast out of experimental (with threat detection credits and monthly ranges), per-workflow model providers, model routing, micro-VM isolation and cross-repo enclaves
  • Customer story (Accenture's figures): one lead saved about 29 hours a week, AI authors 91% of the team's commits, and production errors fell from about 11,000 a day to under 1,000
Read full story

GitHub Universe 2026: Copilot Fusion is generally available, routing and orchestrating models automatically, with Fusion Max scoring 60 on the Artificial Analysis Coding Agent Index at about half the cost of Claude Code with Opus 5.5 Max

At GitHub Universe 2026 on Oct 28, GitHub made Copilot Fusion generally available. It merges the multi-model orchestration of the Project HydraFusion research preview with Copilot auto model selection: users pick Copilot Fusion and an effort level (Standard, High or Max) in the model picker, and the system decides which models to use and whether to run a Single, Cascade or Critique workflow. GitHub says Fusion Max scored 60 on the Artificial Analysis Coding Agent Index, two points below Claude Code with Opus 5.5 Max, at about half the API cost per task, about half the tokens and about 40% less time. Each underlying model is billed at its standard rate, and paid plans get 30% off through Nov 30.

GitHub Universe 2026: Copilot Fusion is generally available, routing and orchestrating models automatically, with Fusion Max scoring 60 on the Artificial Analysis Coding Agent Index at about half the cost of Claude Code with Opus 5.5 Max

Key Takeaways

  • Scores (Artificial Analysis Coding Agent Index v2.0): Fusion Max 60 versus 62 for Claude Code with Opus 5.5 Max; $5.59 per task versus $11.42, while the Devin Fusion pairing scores 62 at $8.00
  • Breakdown: a slight lead on Terminal-Bench 4.0 at 71, third on FrontierCode at 51 (Claude Code 56, Devin Fusion 54), and a weaker 57 on SWE-Atlas-QnA-AA
  • Efficiency: about 7.2M tokens per task, roughly half of Claude Code with Opus 5.5 and 30% fewer than Devin Fusion; GitHub reports about 40% less time per task
  • The pool includes Claude Opus 5.5, Claude Sonnet 5.5, GPT-6 Astra and GPT-6 Sol; admins can disable individual models for Fusion only and set Fusion as the default
  • Availability: all Copilot plans in VS Code, the Copilot app, Copilot CLI and JetBrains IDEs; existing auto, HydraFusion and HydraFusion Max selections migrate to matching effort levels
Read full story

Baseten open-sources decision models mammoth-1 (27B) and elephant-1 (9B): per-option probabilities instead of text, #1 on the Jev Decision Index

On Oct 21, Baseten's research team Base Labs released open decision models mammoth-1 (27B) and elephant-1 (9B), full fine-tunes of Qwen3.5 that skip text generation and return per-option probabilities in one forward pass for routing, classification and scoring. Per Baseten, mammoth-1 tops the Jev Decision Index 0.4 at 71.24 and elephant-1 ties for #1 on the Artificial Analysis Decision Index. Weights are on Hugging Face and the Baseten API is free through Oct 27.

Baseten open-sources decision models mammoth-1 (27B) and elephant-1 (9B): per-option probabilities instead of text, #1 on the Jev Decision Index

Key Takeaways

  • Benchmarks (vendor): mammoth-1 scores 71.24 on Jev Decision Index 0.4, #1 of 208 decision models; 65.9 on AA Decision Index
  • elephant-1 (9B): 62.6 on Jev, best 9B; 65.2 on AA Decision Index, tied #1 with d1-ultra
  • Training: full fine-tunes of Qwen3.5-27B / 9B on 6.21M decision examples incl. abstention and safety data
  • Mechanism: block-bidirectional attention plus shared-prefix caching, one forward pass for many questions; up to ~10x faster than a reasoning model (vendor claim)
  • Try it: Hugging Face weights (MIT); Baseten API free until Oct 27 11:59 PM PT with zero data retention
Read full story
Linked Models & Agents:
⚡ Mammoth 1⚡ Elephant 1⚡ Qwen3.5-27B⚡ Qwen3.5-9B🌐 Baseten🌐 Base Labs

llm-d 1.0 ships: the Kubernetes-native open-source distributed inference stack led by Red Hat, IBM and Google hits production readiness, with vendors reporting 3,000 self-hosted coding agents at 5-10x lower cost than commercial APIs

At PyTorch Conference North America on Oct 20, the CNCF Sandbox project llm-d released version 1.0. It turns inference engines such as vLLM and SGLang into one coordinated serving pool, and 1.0 adds multi-tenant priority and fairness scheduling (flow control), router high availability with zero-downtime rolling upgrades (DisaggregatedSet), a v1 configuration API, and agent-aware session routing with Responses API state. Founded in 2025 by Red Hat, IBM, Google Cloud, CoreWeave and NVIDIA, the project has 500+ contributors, and JetBrains, DigitalOcean and Mistral already run it in production.

llm-d 1.0 ships: the Kubernetes-native open-source distributed inference stack led by Red Hat, IBM and Google hits production readiness, with vendors reporting 3,000 self-hosted coding agents at 5-10x lower cost than commercial APIs

Key Takeaways

  • Scale (Red Hat press release, vendor-reported): GLM 5.2, roughly 753B parameters, on NVIDIA GPUs peaked at 6.6M output tokens per minute and served up to 3,000 concurrent coding agents with zero preemptions, 5-10x cheaper per token than equivalent commercial API pricing at cloud rental rates
  • Cache reuse: IBM says the prefix-aware router captured 97% of available cache reuse on an agentic coding workload; an IBM Research quantum error correction project saw ~98% prefix hits, ~$0.11 per million tokens, and 11.5x lower cost than an all-proprietary setup
  • Google Cloud figures: on Ironwood TPU, prefix-aware routing plus host memory offload cut median time-to-first-token by more than 85% and raised throughput 2.4x on an agentic coding workload; the Gemini platform doubled its prefix cache hit rate from 35% to 70%
  • New in 1.0: flow-control multi-tenant QoS, router hot-standby HA, DisaggregatedSet for coordinated prefill/decode rollouts, a v1 config API, and previous_response_id support in the Responses API
  • Ecosystem: 500+ contributors from 25+ organizations; JetBrains' free Junie Lite, DigitalOcean Serverless Inference and Mistral's tiered commercial traffic run on it; the GitHub v1.0.0 notes admit not every tracked goal shipped
Read full story

ETH Zurich and HKU Resolve MoE Routing Exploration Dilemma with MirrorMoE: Adaptive Suppression Counteracts Shared Expert Homogenization

Modern Mixture-of-Experts architectures increasingly combine fine-grained expert segmentation with shared experts. However, ETH Zurich and HKU researchers identified an 'Exploration Dilemma' (arXiv:2610.22353, GitHub: BingcongLi/MirrorMoE): shared experts homogenize token representations, suppressing routing exploration just as fine-grained segmentation combinatorially enlarges the routing space. MirrorMoE resolves this via token-adaptive suppression of unnecessary experts, cutting pretraining perplexity across all model scales.

ETH Zurich and HKU Resolve MoE Routing Exploration Dilemma with MirrorMoE: Adaptive Suppression Counteracts Shared Expert Homogenization

Key Takeaways

  • ETH Zurich and HKU introduced MirrorMoE (arXiv:2610.22353) to solve the exploration dilemma between shared experts and fine-grained routing
  • Employs token-adaptive expert suppression to shrink the combinatorial routing space without adding runtime latency
  • Consistently reduces pretraining perplexity across scales from 100M to 2.4B (slashing 2.4B PPL from 21.17 to 20.50)
  • Lifts downstream benchmark averages by +1.64 points on the 2.4B model, highlighted by a +4.03 pt boost on BoolQ (58.53% vs 54.50%)
Read full story
Linked Models & Agents:

Rule-Governed World Modeling Breakthroughs: OmniVerifier-C1 Graded Verifier, Meituan's WorldCast (72.8 vs 20.1 Open-Source Gap), and NUS's 4x Faster RPO Diffusion RL

Three new studies tackle verification, evaluation, and RL alignment for rule-governed generative world models: OmniVerifier-C1 (arXiv:2610.22355, 32 upvotes) uses Decoupled RL to train a decomposed graded visual verifier that reaches 0.684 on ViVerBench and boosts FLUX.1-dev GenEval from 0.68 to 0.79 while enabling Maze and Sudoku world modeling; Meituan's WorldCast benchmark (arXiv:2610.20731, 30 upvotes) evaluates 12 models across 320 multi-step world state prediction cases, finding GPT-Image-2.5 System at 72.8 vs. 42.8 for Nano Banana Pro and 20.1 for the top open model; and NUS's Routing Policy Optimization (RPO, arXiv:2610.22282, 23 upvotes) turns attention routing into an internal exploration action to train video/image diffusion RL 3.1x–4.2x faster than Flow-GRPO and DanceGRPO.

Rule-Governed World Modeling Breakthroughs: OmniVerifier-C1 Graded Verifier, Meituan's WorldCast (72.8 vs 20.1 Open-Source Gap), and NUS's 4x Faster RPO Diffusion RL

Key Takeaways

  • OmniVerifier-C1 uses Decoupled RL (DAPO) to jointly optimize sub-question binary judgments and global continuous scoring, reaching 0.684 on ViVerBench and boosting FLUX.1-dev GenEval from 0.68 to 0.79
  • Meituan's 320-case WorldCast benchmark reveals a massive gap in multi-step visual state prediction: GPT-Image-2.5 System scores 72.8 vs. 42.8 for Nano Banana Pro and 20.1 for the best open-source model
  • NUS's Routing Policy Optimization (RPO) uses internal attention routing exploration to align Wan2.2-TI2V-5B in just 24.1 GPU-hours—3.1x faster than Flow-GRPO and 4.2x faster than DanceGRPO
Read full story
Linked Models & Agents:
ADSponsored

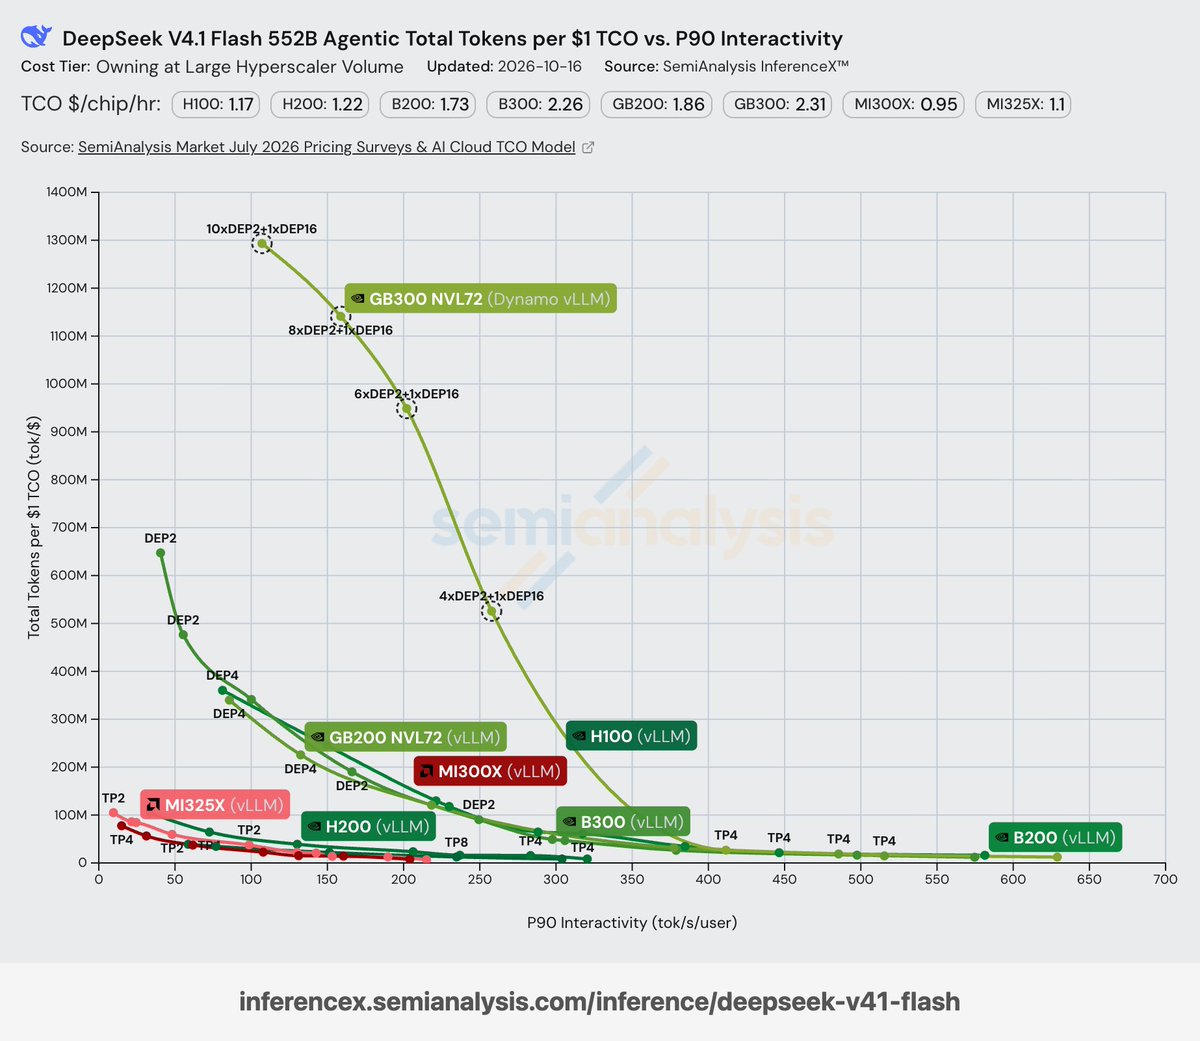
vLLM and OpenRouter Launch Day-0 Serving for DeepSeek-V4.1-Flash-1017: 830K tok/s per GPU and 1.3B Tokens/$ TCO on SemiAnalysis AgentX

Following the release of DeepSeek-V4.1-Flash-1017, vLLM announced Day-0 serving optimization delivering 1.3B tokens per dollar TCO and 830K tok/s per GPU at 100 tok/s/user on SemiAnalysis AgentX (5x agentic throughput gain since Day 0), while OpenRouter launched live multi-provider routing starting at $0.10/M input and $0.50/M output tokens.

vLLM and OpenRouter Launch Day-0 Serving for DeepSeek-V4.1-Flash-1017: 830K tok/s per GPU and 1.3B Tokens/$ TCO on SemiAnalysis AgentX

Key Takeaways

  • vLLM delivers 830K tok/s per GPU (cached + input + output) at 100 tok/s per user and 1.3B tokens/$ TCO on SemiAnalysis AgentX for DeepSeek-V4.1-Flash-1017 (5x faster since Day 0)
  • DeepSeek-V4.1-Flash-1017 reaches 77.0% on DeepSWE v1.1 (beating Claude Opus 5 at 74.0%), 68.2% on NL2Repo-Bench, and 72.1% on Apex Bench with shorter agentic outputs
  • Live on OpenRouter from $0.10/M input and $0.50/M output tokens, while DeepSeek's official API alias deepseek-flash remains at $0.15/M input and $0.60/M output
Read full story
Linked Models & Agents:

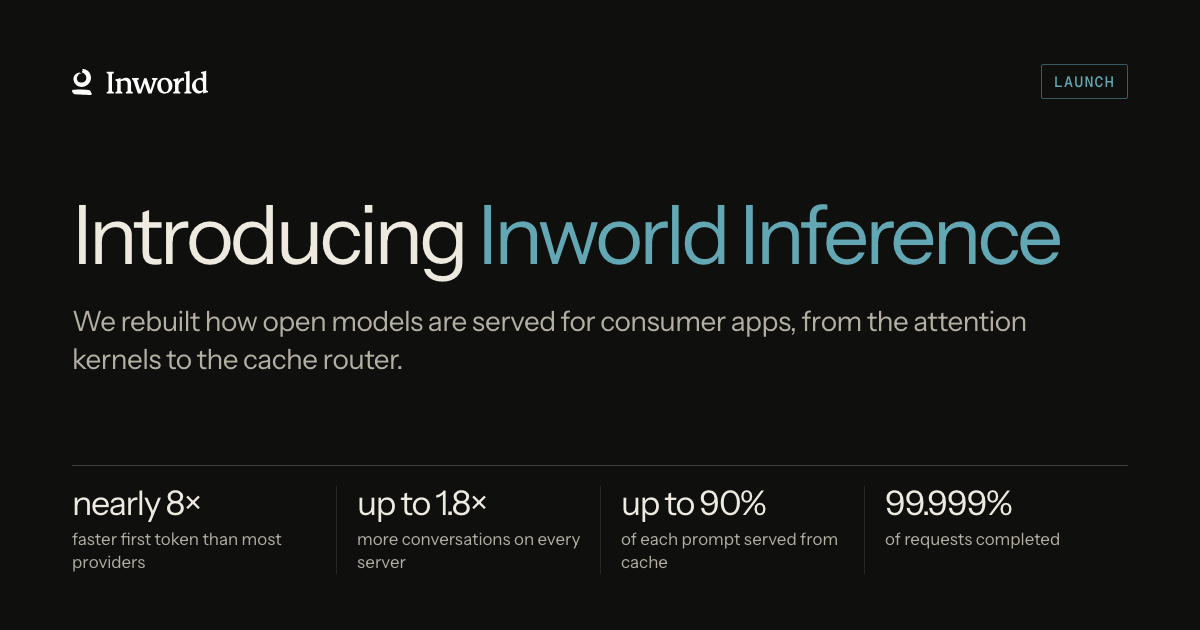
Inworld Inference opens to all developers: an open-model inference API built for consumer AI, with Gemma 4 26B p95 first token 7.8x faster than the median OpenRouter provider

On 2026-10-14 Inworld AI opened Inworld Inference to every developer, positioning it as an inference service for consumer apps (companions, tutors, voice, interactive fiction). Instead of listing thousands of models it builds a per-model serving stack for open models such as Gemma 4, GLM 5.3 Flash, DeepSeek and MiMo: draft-and-verify (speculative) decoding, a rewritten split-KV verify attention kernel, KV-aware routing and eval-gated low precision. Vendor-reported: Gemma 4 26B p95 first token of 0.31 s, 7.8x faster than the median OpenRouter provider; up to 90% of prompts from cache; 99.999% success over 20M+ GLM 5.3 Flash requests in 30 days. The API is OpenAI-compatible with Flex/Default/Priority/Fast tiers per request.

Inworld Inference opens to all developers: an open-model inference API built for consumer AI, with Gemma 4 26B p95 first token 7.8x faster than the median OpenRouter provider

Key Takeaways

  • Gemma 4 26B first token: p50 0.17 s / p95 0.31 s, 3.6x / 7.8x faster than the median OpenRouter provider (blog, vendor-reported snapshot, not a matched workload)
  • Pricing: Gemma 4 26B at $0.07 input, $0.035 cached, $0.34 output per 1M tokens, nearly 40% below the median no-training provider
  • Rewritten verify attention: 3.4–7.5x faster per layer, attention share of a decode step 27.5%→16.5%, p50 TTFT 154→117 ms at equal eval scores
  • KV-aware routing: GLM 5.3 Flash cache hits 25%→47%, DeepSeek V4.1 Flash 11%→33%; cached MiMo 2.6 Pro input costs 99% less
  • Reliability: 98 failures across 20M+ GLM 5.3 Flash requests in 30 days (~4.8 per million); per-request service_tier of Flex/Default/Priority/Fast
Read full story

Subquadratic launches SubQ Snap: a 384K-context decision model for agent routing, tool picks and checks at $0.05/M input

On Oct 12 Subquadratic released SubQ Snap (public preview, subq-snap-preview), a decision model that scores a fixed answer set instead of generating text. Built on Subquadratic Sparse Attention, it reads up to 384K tokens of text and images, returns a decision on 100K tokens in about a second, and—per vendor numbers—scores 61.7 on Decision Index 0.2.1 vs Jev's 57.9. Input costs $0.05/M tokens; output is free.

Subquadratic launches SubQ Snap: a 384K-context decision model for agent routing, tool picks and checks at $0.05/M input

Key Takeaways

  • 384K multimodal context (text + images), 12x Jev per vendor
  • Decision Index 0.2.1: 61.7 vs Jev 57.9 (vendor-reported)
  • 16 enterprise tasks: 67.6 vs 61.6 avg, leads 13/16; trails on When2Call by 7.6
  • Decision LCR (72K–115K multi-doc): 74.0 one-shot vs Jev 48.0 chunked
  • $0.05 per M input tokens, output free; ~1s for 100K tokens
Read full story
Linked Models & Agents:
⚡ SubQ Snap⚡ SubQ⚡ Jev🌐 Subquadratic🌐 TypeSafe

TokenRouter: Tsinghua Unveils NeurIPS 2026 Serving System for Token-Level LLM Routing, Boosting Throughput by up to 64x

Token-level LLM routing—routing easy tokens to small models and switching to frontier models for critical reasoning tokens—presents an optimal trade-off between output quality and inference cost. However, current LLM serving engines (such as vLLM and TGI) are architected for single-model execution, suffering severe step desynchronization, batch admission latency, and extreme orchestration complexity when handling high-frequency token transfers across heterogeneous models. Researchers from Tsinghua University's NICS Lab present TokenRouter (arXiv:2610.12242, accepted at NeurIPS 2026, code: github.com/thu-nics/TokenRouter), an efficient and developer-friendly serving system engineered for token-level routed LLM inference. TokenRouter introduces a 'request-centric programming and model-centric execution' paradigm, enabling developers to write routing logic intuitively per request while the runtime handles asynchronous execution across subservers. Incorporating a Delayed-Batching Scheduler parameterized via discrete-time Markov chain modeling, a decoupled tri-loop architecture, and an instant handoff-resume mechanism, TokenRouter achieves 2.01x to 64.15x higher decoding throughput compared to existing serving platforms across diverse routing workloads, with complete code open-sourced.

TokenRouter: Tsinghua Unveils NeurIPS 2026 Serving System for Token-Level LLM Routing, Boosting Throughput by up to 64x

Key Takeaways

  • Tsinghua University open-sources TokenRouter (NeurIPS 2026), an optimized serving architecture for token-level LLM routing
  • Introduces request-centric programming and a delayed-batching scheduler, delivering 2.01x to 64.15x higher decoding throughput
  • Decoupled tri-loop execution cuts P99 inter-token latency by 43.6%, reducing enterprise cloud GPU costs by 50% to 70%
Read full story
Linked Models & Agents:

Ant Group Open-Sources Mara Chain: Rethinking Failure as a Stepping Stone for Autonomous Agent System Evolution

Modern AI agent systems and autonomous frameworks rely heavily on greedy search or reinforcement learning for self-evolution (such as harness synthesis, workflow routing, and prompt optimization). However, in non-convex and deceptive optimization landscapes, greedy pruning prematurely discards mutations that temporarily underperform, stranding systems in local optima. Researchers from Ant Group Research, Peking University, and Beijing Academy of Artificial Intelligence (BAAI) unveil Mara Chain (arXiv:2609.35855), an evolutionary optimization framework that rethinks failures as essential stepping stones. Mara Chain operates via three interconnected mechanisms: a stepping-stone archive combining semantic embeddings and execution traces for novelty preservation, a hierarchical mutator driven by backward failure attribution, and a Pareto-optimal non-dominated sorting selection module. On the AppWorld benchmark, Mara Chain achieves up to a 20.5% performance improvement over leading baselines (GEPA, ACE, SkillOpt-Lite) while requiring 65.5% fewer rollouts. On TerminalBench 2.1, it outstrips AHE and Meta-Harness by 20.2 and 22.5 percentage points respectively. The team has open-sourced the implementation under the AntOmniEvo repository.

Key Takeaways

  • Ant Group, PKU, and BAAI unveil Mara Chain, rethinking failed mutations as stepping stones to bypass local optima in agent self-evolution
  • Outperforms GEPA and ACE by up to 20.5% on AppWorld with 65.5% fewer rollouts, and beats AHE by 20.2 percentage points on TerminalBench 2.1
  • Open-sources the complete AntOmniEvo framework with AST-aware stepping-stone buffering and hierarchical failure mutators
Read full story