On November 5 Meta AI (@AIatMeta) said Muse Realtime Avatar, previewed at Connect, is rolling out in the US Muse app, turning Muse Realtime Voice into interactive live avatars. The research blog describes an audio-driven Diffusion Transformer that shares the speech-token stream with voice for lip-sync and expression; a single GB200 session streams 448×768 at 25 fps with about 870 ms from end of user turn to first synchronized audio-video byte, with Meta Video Seal invisible watermarking. Muse is for users 18+; no global schedule or developer API was announced.
Zoom
Key Takeaways
US Muse app rollout of Realtime Avatar after the Connect preview (@AIatMeta)
Shared speech VQ tokens drive audio decode and avatar video; causal chunks with self-forcing distillation cut ~120 teacher NFEs to 2 student NFEs (~60x)
Vendor perf: 448×768@25fps, ~870ms first-byte latency; ~8x serving capacity vs BF16 baseline, up to 12 concurrent sessions on one GB200
Vendor preference study favored Muse over Runway Characters and HeyGen LiveAvatar on overall and most axes
Safety: Video Seal invisible watermark; blog demos are not the full in-app avatar set; no public developer API stated
On November 5 Google made Gemini Omni 1.2 Flash (gemini-omni-1.2-flash) generally available in AI Studio and the Gemini API: video generate/edit length rises to 15 seconds, vendor pricing cuts video output about 30% (~$12 per 1M tokens, roughly $0.07/s at 720p), with stronger multi-reference consistency and more natural speech. The changelog states that from December 3, 2026, requests to gemini-omni-1.1-flash will automatically route to 1.2 at 1.2 rates.
Zoom
Key Takeaways
Model id gemini-omni-1.2-flash live in AI Studio and Gemini API (changelog Nov 5)
Clips 3–15s at 360p/720p/1080p/4K; vendor notes consistency across up to 6 reference images
Vendor pricing: ~30% lower video output; ~$0.07/s at 720p (~$1.04 for 15s)
From 2026-12-03, gemini-omni-1.1-flash auto-routes to 1.2 at 1.2 rates
Consumers: Flow, Google Vids, and Gemini App support up to 15s clips and multi-turn edits
On November 2 voice AI company Hume launched the Audio Decision API, which it calls the first audio-native model that answers questions about speech and sound. Developers upload raw audio, write each question as a sentence with candidate answers, and get back a probability for each answer, with no transcription step. It supports yes/no, multiple-choice, rating-scale and time-span questions, such as how many speakers there are, whether someone laughs, whether a caller sounds frustrated, or whether a siren is in the background. Per Hume, it was trained on more than 10 million human judgments and in an initial evaluation reached 70.7% agreement with a human panel's average judgment, versus 56.5% for an individual rater. Access is currently by request or waitlist.
Zoom
Key Takeaways
Per Hume: 70.7% agreement with a human panel's average judgment in an initial evaluation, versus a 56.5% individual-rater baseline; sample size and languages were not disclosed.
Trained on more than 10 million human perceptual judgments (per Hume's X post); the blog cites tens of millions of listener ratings overall.
Four question types (yes/no, choice, scale, span); adding a question is one line of JSON, with no labeling or retraining.
The endpoint is POST /v0/decisions/file, plus an input-token estimate endpoint, with Python and TypeScript SDKs.
Hume says work that used to take 10+ models now takes one call; pricing has not been published.
Voice model company Cartesia launched Managed Agents on Oct 29, an end-to-end voice agent platform for enterprise phone calls that tunes its own speech-to-text and text-to-speech models together with the agent harness, and bundles telephony, knowledge bases, tool calls and outbound batches. Cartesia says it ranks #1 on Artificial Analysis's Speech Agent Arena with a 1115 Elo and scores 87.4% accuracy and 90.7% experience on ServiceNow's EVA-Bench (vendor-reported, with GPT-5.5 as the reasoning model). Launch pricing is 50% off at $0.03 per minute.
Zoom
Key Takeaways
On Artificial Analysis's Speech Agent Arena blind preference test, Managed Agents ranks #1 of 30 agents with a 1115 Elo, ahead of Gemini 3.1 Flash Live Minimal (1099), Grok Voice 3.0 (1064) and GPT-Live-1 (1041) (Cartesia blog, as cited by the vendor)
First-attempt results on ServiceNow EVA-Bench across 200+ customer service, IT service and HR scenarios: 87.4% accuracy and 90.7% experience, versus 73.7%/71.2% for Grok Voice 3.0 and 59.0%/61.6% for GPT Realtime 2.1 (EVA-Bench)
All these benchmark runs use GPT-5.5 as the reasoning model; Cartesia's internal evaluation says 85% of calls had no turn-taking issues, versus 67% for other agents
Launch pricing is 50% off at $0.03 per minute; Cartesia says the platform has already handled tens of millions of conversations in finance, retail, hospitality and healthcare
It supports 44 languages; English, Spanish, Hindi, French and Japanese can switch mid-call today, with the rest coming soon
NVIDIA AI announced Nemotron 3.5 Transcribe on Oct 28, with weights on Hugging Face and ModelScope. It is an offline, instruction-driven speech model whose single checkpoint covers transcription in 40 languages, translation between 31 languages and English, speaker attribution in 13 languages, and audio question answering, on recordings up to an hour long with up to eight labeled speakers. NVIDIA says it ranks first among open-weight models on the Hugging Face Open ASR English leaderboard at 5.33% average WER, and Artificial Analysis measured a 2.8% AA-WER, tied for first among open models with Voxtral Small, which uses 24B active parameters. The weights, the Granary v2 training data and fine-tuning recipes are all released.
Zoom
Key Takeaways
Architecture: a speech encoder paired with a Mamba-2/Transformer hybrid MoE language model, about 30B total parameters (34B in the model card counting the audio encoder) and about 4B active per token (4.3B in the model card), shipped in BF16, FP8 and NVFP4
Capabilities: transcription in 40 languages, translation between 31 languages and English, speaker attribution in 13 languages, audio Q&A (trained in English only) and word-level timestamps, on recordings up to 1 hour with up to 8 speakers
Official and third-party figures: first among open models on the Open ASR English leaderboard (5.33% average WER), 4.62% mean WER across 7 languages and 10.98% on long-form; Artificial Analysis AA-WER 2.8% and 1.8% on its AA-AgentTalk voice-agent set (next-best open model 2.3%)
Artificial Analysis measured DeepInfra's hosted endpoint at a 75x speed factor, transcribing a minute of audio in under a second, priced at $2.00 per 1,000 minutes
Licensed under OpenMDW-1.1 for commercial use; Granary v2 data and NeMo Speech fine-tuning tools are released too, and in NVIDIA's medical case study fine-tuning cut WER a further 45.8% relative to the best prompt
On Oct 26 Tencent Hunyuan (Tencent Hy) open-sourced Hy-SimulMT, a real-time simultaneous interpreting model for bidirectional Chinese-English speech-to-speech translation. It translates while the speaker talks, outputs both translated text and speech, and can clone the speaker's voice in real time. Six checkpoints landed on Hugging Face (30B-A3B translation-only and source-plus-translation Interleave variants, each in BF16, FP8 and GGUF), with the model card listing Apache-2.0; GitHub ships the SimulInfer serving stack and SimulTrain training tools. Vendor-reported: about 3s StreamLAAL on RealSI long-form audio, the lowest among compared systems.
Zoom
Key Takeaways
Size and variants: 30B-A3B MoE (about 3B active), six checkpoints: translation-only and Interleave (source plus translation), each in BF16, FP8 and GGUF (Hugging Face collection)
Latency (vendor-reported): about 3s StreamLAAL on RealSI long-form audio, the lowest among compared systems, with a GEMBA quality score above the compared open models and 4 of 5 commercial APIs
Short-form (vendor-reported): FLEURS 90.3, CoVoST2 75.5, ACL6060 81.2, RealSI-Sentence 84.7, the last being the top score in the table; Qwen3.8-LiveTranslate scores 88.4/82.1/80.5/84.4 in the same table
Human comparison: 18 real Chinese and English recordings of about 6 minutes each against 6 CATTI Level 1/2 interpreters; Tencent says quality was on par with often lower latency, and notes the result only covers this small test
Deployment: one SimulInfer deploy.sh command starts vLLM (>=0.31) plus a web/WebSocket service; speech output and voice cloning need a separate TTS service; llama.cpp support is not yet merged upstream (SimulInfer docs)
On 2026-10-23 (16:53 UTC) the official @blocks account unveiled Dessa, and Jack Dorsey called it the most authentic full-duplex speech model ever built. The official page block.xyz/dessa says Dessa is a true speech-to-speech model trained only on recordings of human conversation, with no text and no pretrained models. It is full-duplex, so it listens and talks at the same time, cuts in and backchannels naturally, runs faster than real time, and runs locally on a MacBook Pro M4 Max or better. Block says it was trained on a single NVIDIA GB200 NVL72 and learned language from hundreds of times fewer words than LLMs. There is no public API or weights yet; a small group of AI safety researchers is getting early access.
Zoom
Key Takeaways
Trained only on human conversation audio, from scratch, with no text and no pretrained models (official page)
Full-duplex speech-to-speech: listens while talking, cuts in and backchannels, and natively hears and expresses emotion, sarcasm and laughter
Inference runs faster than real time and runs locally on a MacBook Pro M4 Max or better
Block says training used a single NVIDIA GB200 NVL72 and needed hundreds of times fewer words than LLMs
No public API, weights or third-party benchmarks yet; early access is limited to a small group of AI safety researchers
The Google AI Studio team released an experimental preview of the Gemini API CLI (command name gemini-api). It is a stateless, zero-dependency Go binary for macOS, Linux and Windows, open source under Apache 2.0. Any coding agent with shell access and a GEMINI_API_KEY can call text reasoning, image, video, music and speech generation, file and YouTube analysis, audio and video transcription, and managed agents such as Deep Research with one command. Media is written straight to disk and only the file path goes to stdout, so base64 payloads never land in the context window. Google labels it experimental and not a supported Google product.
Zoom
Key Takeaways
Default models (official README): gemini-3.8-flash for generate, analyze and transcribe; gemini-nano-banana-2.1 for image; gemini-omni-1.1-flash for video; lyria-3.5 for music; gemini-3.8-flash-tts for speech
Install with a one-line curl script on macOS/Linux, a PowerShell script on Windows, or go install; the latest GitHub release is v0.4.3 (published 2026-10-19)
Built for agents: --usage prints the command tree as KDL, --schema prints JSON Schema, --dry-run validates offline with credentials redacted, plus --output-format json/toon and inline --jq
It also manages sandbox environments, server-side credentials, webhooks and cron triggers for managed agents; files uploaded via the Files API are kept for 48 hours
On Oct 20, French voice AI company Gradium open-sourced Phonon, a family of on-device text-to-speech models: the English Phonon 31m (64 MB q8 weights, Apache 2.0) and Phonon 40m (single-language English, French, German, Spanish and Portuguese variants plus a five-language model, CC BY-NC non-commercial). Built on Kyutai's Pocket TTS and the Mimi codec, it ships its own runtime for CPU, Metal, CUDA, Vulkan, WebGPU, Core ML and Snapdragon, running offline on phones, browsers and a Raspberry Pi. Gradium reports 7 ms to first audio on a MacBook Air M5 CPU versus 517 ms for Kokoro.
Zoom
Key Takeaways
Check the license: only the English Phonon 31m is Apache 2.0 for commercial use; every Phonon 40m variant, including multilingual, is CC BY-NC 4.0 and needs a deal with Gradium for commercial use
Size (official): 64 MB q8 weights for 31m and 74.6 MB for 40m; 37 built-in English voices, 102 in the multilingual model, plus voices cloned or designed with Gradium
Speed (vendor-measured): 6.9 ms to first audio and 29.9x real time on a MacBook Air M5 CPU with 4 threads, versus 517 ms for Kokoro (which does not stream); 38 ms and 3.7x real time on a Raspberry Pi 5; 7.5 ms on Snapdragon 8 Elite Gen 5
Accuracy (vendor-built hard-sentence set, 500 per language, public on HF): English WER of 1.70% for 31m and 2.22% for 40m versus 3.50% for Kokoro and 8.71% for NeuTTS Nano, with text normalization for numbers, dates and version strings
Get started with uvx ptts or pip install ptts, the phonon-tts npm package for browsers, or the gradium-ai/xn-ptts runtime on GitHub
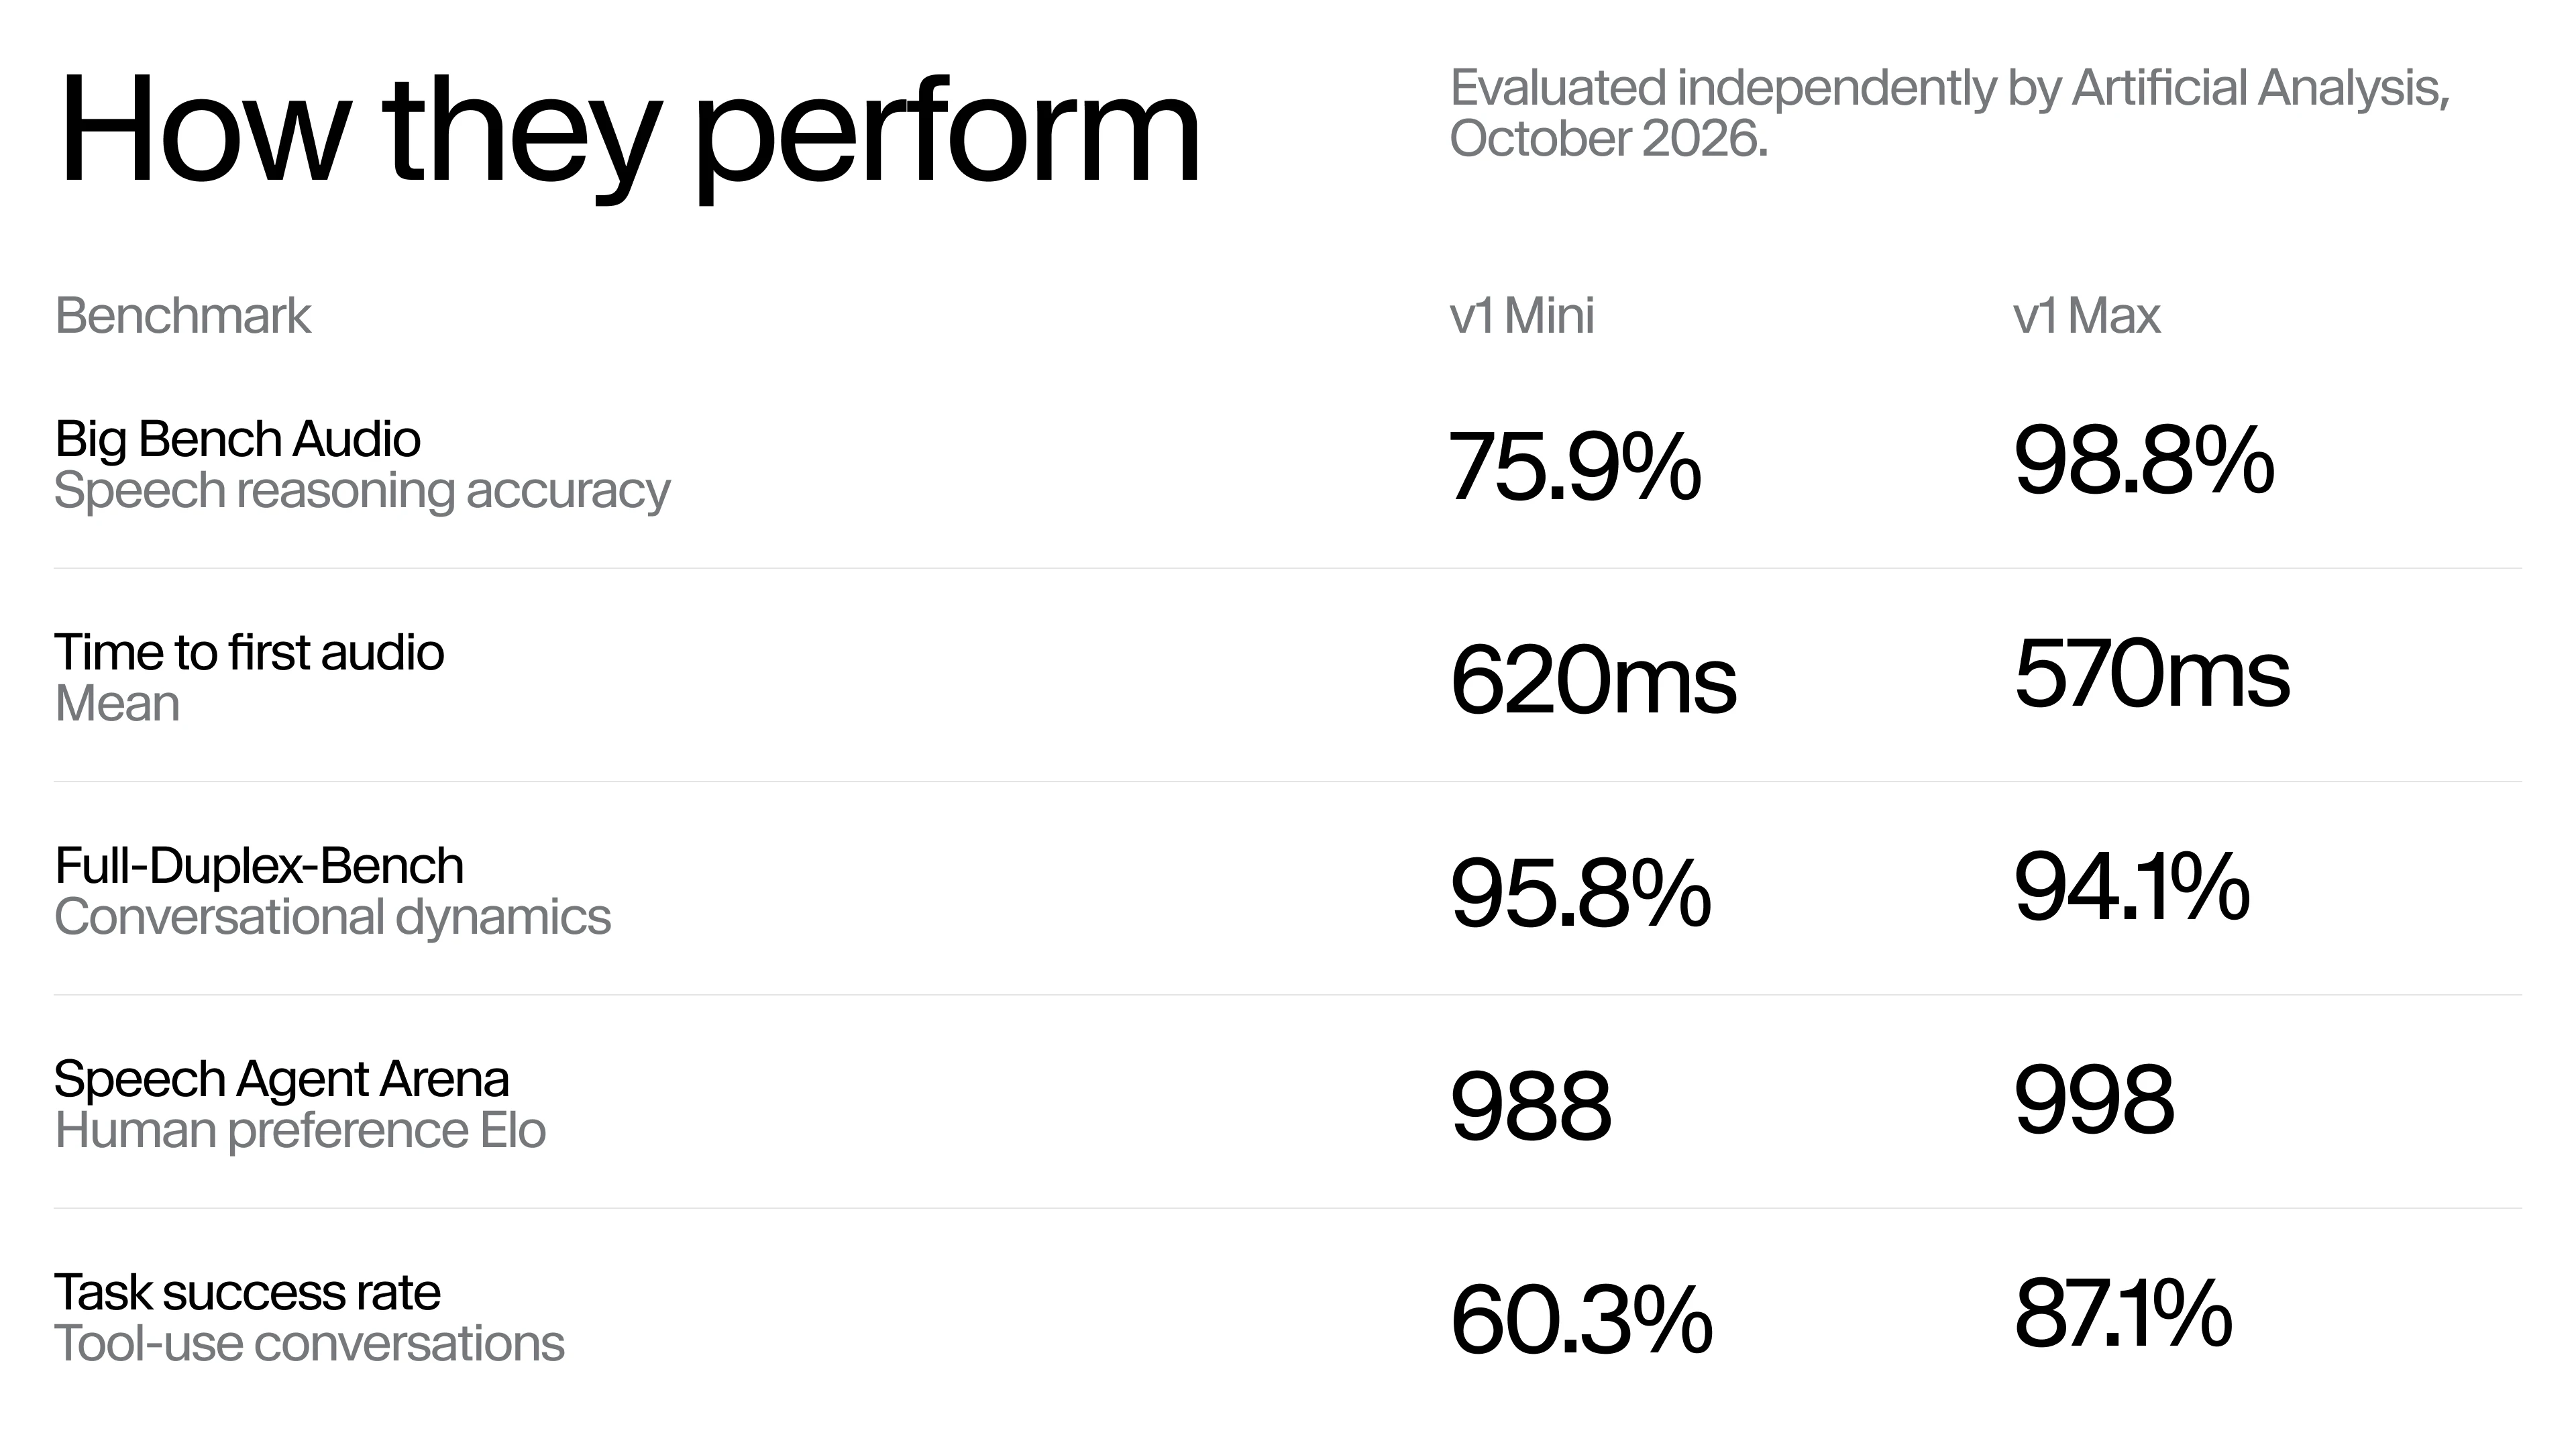
On Oct 20 ElevenLabs released Eleven Realtime, end-to-end speech-to-speech models where each model is a complete voice agent, removing the need to wire up speech recognition, an LLM and text-to-speech yourself. v1 Mini targets low-cost natural conversation and v1 Max targets support and multi-step tool use. Both cover 90+ languages and 17,000+ voices. Citing independent Artificial Analysis evals, Max answers 98.8% of Big Bench Audio correctly and starts speaking in 0.57s on average. The API is OpenAI Realtime compatible, so migrating means changing the endpoint and model name.
Zoom
Key Takeaways
Speech reasoning (independent Artificial Analysis eval cited by ElevenLabs): on 1,000 Big Bench Audio questions, v1 Max scores 98.8% and v1 Mini 75.9%
Speed (vendor-stated): Max starts speaking in 0.57s on average and Mini in 0.62s; the launch post says "half a second", slightly faster than the blog figures
Conversation dynamics and preference: Full-Duplex-Bench Mini 95.8%, Max 94.1%; Speech Agent Arena blind tests Max 998, Mini 988
Tool-use task completion: Max 87.1% vs Mini 60.3%, which is why ElevenLabs recommends Max for heavy tool calling
90+ languages and 17,000+ voices; the Realtime API is WebSocket-only at wss://api.elevenlabs.io/v1/convai/realtime and works with the OpenAI SDK; pricing was not in the launch post
On Oct 20 Mistral released Voxtral 3: the Voxtral Small/Mini Transcribe 3 speech-to-text models, Voxtral Mini Transcribe Realtime 3, the Voxtral Mini TTS 3 (Voxtral Speech 3) text-to-speech model, and a LiveKit-based voice agent SDK that streams listening, reasoning with tool calls, and speaking as one pipeline, with each turn completing in under a second per Mistral. Transcription covers 50+ languages with diarization and context biasing; TTS covers 35+ languages and 50+ dialects, plus Pro Voice cloning from 30 minutes of audio. It is live on the Mistral API (EU, US and global endpoints) and can be self-deployed.
Zoom
Key Takeaways
Multilingual transcription (vendor-reported): macro WER over 45 FLEURS languages is 4.1% (language forced) / 4.0% (inferred) for Voxtral Small Transcribe 3, tied with Microsoft AI Transcribe 2 and ahead of Scribe v2 (4.9%) and Whisper large-v3 (16.0%/14.9%)
Diarization (vendor-reported): cpWER of 18.4% for Small and 18.6% for Mini, vs 30.9% for the previous Voxtral Mini Transcribe 2 and 38.4% for Gemini 3.5 Transcribe
Pricing: Voxtral Mini Transcribe 3 is 4B parameters at $0.0035/min (docs list it as Public Preview with 32k context); Voxtral Speech 3 costs $13 per 1M characters
Realtime: Voxtral Mini Transcribe Realtime 3 runs below 500 ms latency; in Mistral's 35-language FLEURS chart the 480 ms setting scores 6.4% WER, still behind Gemini 3.5 Realtime Transcribe at 4.2%
The voice agent SDK is built on LiveKit with SIP telephony and WebRTC; each stage (LLM, voice, language) is swappable, and Pro Voice clones a voice from 30 minutes of audio
In the latest independent Text-to-Speech (TTS) evaluations published by Artificial Analysis, Ant Group's open-source Ming-3.0-tts achieved a 93.2% pronunciation accuracy score, ranking #1 among all 31 evaluated models (outperforming commercial leader ElevenLabs v4 at 91.7%). Offering both a dense 0.5B parameter variant and a 7.9B mixture-of-experts (MoE) model, it delivers voice cloning and preset voices with a Controlled Voice Elo score of 1,069 (#1 among open-weight models), fully released under the permissive MIT license.
Zoom
Key Takeaways
Ant Group open-sourced Ming-3.0-tts, achieving a chart-topping 93.2% pronunciation accuracy on Artificial Analysis speech benchmarks
Surpasses commercial leader ElevenLabs v4 (91.7%) and ranks #1 among open-weight models on the Controlled Voice leaderboard (1,069 Elo)
Provides both a lightweight 0.5B dense model for edge inference and a 7.9B MoE flagship with zero-shot voice cloning
Released under the permissive MIT license for unrestricted commercial deployment, hosted on Hugging Face
On October 19 Ant Ling (inclusionAI) open-sourced five Ming-3.0 models under MIT, spanning speech synthesis (tts-0.5B; tts-tiny, 7.9B total/1.3B active), audio understanding (audio-flash, 126B/6.5B active; audio-tiny, 9.3B/2.7B active) and speech recognition (asr-tiny, 8.6B/2B active). Per the vendor, tts-0.5B ranks #1 among open-weight models on Artificial Analysis Controlled Voice at 1069 Elo and ties #1 overall on pronunciation robustness at 93.2%; asr-tiny averages 4.41% error across four ASR categories. Weights are on Hugging Face and ModelScope, with day-0 SGLang and vLLM support.
Zoom
Key Takeaways
Lineup: five models in three families, two TTS, two audio-understanding and one ASR, all MIT-licensed.
TTS results: tts-0.5B scores 1069 Elo on AA Controlled Voice, #1 among open weights; 1188 Elo and #3 on Provider Voice; ties #1 overall on pronunciation robustness at 93.2% (vendor figures).
TTS features: 7 languages plus Sichuanese and Cantonese, 14 inline paralinguistic tags (laughter, sighs, coughs and more), 44.1 kHz output, built on Qwen2.5-0.5B.
Audio understanding: audio-flash has 126B total and 6.5B active parameters, and handles long-recording summaries, spoken Q&A, audio reasoning and tool-call generation.
ASR: asr-tiny accepts hotwords and dialogue context, is evaluated on 15 dialect test sets, and averages 4.41% error across four categories (vendor figures).
On Oct 16 OpenAI made prompt-to-voice generally available to all API customers. Developers describe accent, pitch, timbre and pace in plain text and create a saved custom voice through /v1/audio/voices or the voice Playground, then reuse it in GPT-Live sessions. Creating a voice is free; speech uses regular GPT-Live session billing, with up to 100 prompt-generated voices per organization. OpenAI also added nine natural GPT-Live voices in German, French, Hindi, Japanese and Korean.
Zoom
Key Takeaways
Generally available to all API customers from Oct 16; no reference or consent recording needed
Creating a voice is free; speaking in GPT-Live and previewing in the Playground use regular session billing (per OpenAI)
Up to 100 prompt-generated voices per organization; optional script_hint of up to 2,000 characters
Nine new natural voices: 3 German, 2 French, 2 Japanese, 1 Hindi and 1 Korean
Limits: prompt voices work only with GPT-Live, not TTS, Realtime or Chat Completions; voice creation is not Zero Data Retention compatible
On 2026-10-15, MBZUAI’s Institute of Foundation Models (IFM) and Inception42 released Jais 3—the first language adaptation of the open K2 Horizon fleet. Six open-weight sizes run from a 0.9B dense phone model to a 375B-A23B sparse MoE (≈23B active), plus Jais Speech for Arabic ASR. Models share one training recipe and agent stack, with up to 512K context (128K on 0.9B), Apache-2.0 weights and stage checkpoints on Hugging Face, and day-0 vLLM support.
Vendor Arabic average: 375B leads open peers at 84.0 (Qwen3.5-397B 82.0); 7B scores 79.4 vs K2 Horizon base 56.4→79.6 (tech blog)
Agents: 3.7B/7B lead their size class by ~20 points; 375B agentic average 60.2 with SWE-Bench Verified 70.2 and Terminal-Bench 2.1 73.8 (same-harness vendor runs)
Speech: Jais Speech macro-average WER/CER 22.85/8.37 across six public ASR sets, ahead of Audar, Cohere Transcribe Arabic, omniASR (Jais page)