Google DeepMind announced Genie 4 on Oct 27, calling it its most realistic and interactive world model yet. Built on Gemini Omni, it improves physics and human motion, natively generates ambient audio and interactive character dialogue for the first time, and uses Gemini 3.8 Flash in the loop to plan complex events. It is a research preview for trusted testers for now, coming soon to Google AI Ultra (Project Genie) and early access partners in the Gemini API and AI Studio; no quantitative benchmarks were published.
Zoom
Key Takeaways
Per Google DeepMind, Genie 4 is its most realistic and interactive world model yet, with Gemini Omni anchoring real-world appearance and behavior
It is DeepMind's first real-time world model with native audio: ambient sound, music and character dialogue are generated with the world, and characters respond live
Gemini 3.8 Flash acts as a guiding agent in the loop, splitting goals into steps and checking frames; a demo pairs Gemini 4 Argon with Genie 4 to simulate an Apollo humanoid
Official limitations: only a few minutes of continuous interaction and drift over longer sessions; no quantitative benchmarks were published
Trusted testers only for now; coming soon to Google AI Ultra (Project Genie) and Gemini API / AI Studio early access partners, with SynthID on all outputs
Microsoft Research (MSRA) researchers published and open-sourced WildAWM (arXiv:2610.26828, GitHub: MSR-Orchard/WildAWM), a generalist agent world model designed for open-ended 'in the wild' digital environments. Traditional computer-use agents rely on slow, brittle, and expensive live web/OS sandboxes for training and evaluation. WildAWM establishes a scalable multimodal world model that accurately predicts visual screen transitions and DOM mutations conditioned on agent actions (click, type, scroll). By replacing live execution environments with a high-fidelity neural simulator, WildAWM unlocks safe, accelerated offline reinforcement learning for GUI agents.
Zoom
Key Takeaways
Microsoft Research open-sources WildAWM (arXiv:2610.26828), establishing the first generalist world model for wild web and GUI domains
Eliminates dependency on fragile, expensive live web sandboxes that risk side-effects during agent trial-and-error training
Employs an action-conditioned multimodal autoregressive design predicting high-fidelity visual rollouts following clicks, typing, and scrolling
Decisively outperforms prior state-transition baselines across e-commerce, enterprise software, and desktop GUI simulations
Researchers introduced OverSeer in arXiv:2610.28554, pioneering a new class of multi-agent world models operating beyond the field of view of individual agents. Standard video world models collapse in multi-agent environments because individual agents operate under partial observability; naive frameworks feeding external global map inputs suffer severe spatial inconsistency and state hallucination. OverSeer resolves this by jointly predicting auxiliary spatial representation streams alongside the agents' first-person camera streams. In comprehensive Minecraft benchmarks, OverSeer achieves decisive state-of-the-art results across physical grounding, long-horizon spatial memory, and cross-view consistency.
Zoom
Key Takeaways
OverSeer introduced in arXiv:2610.28554, establishing the first scalable multi-agent video world model framework
During the GTC Berlin keynote, NVIDIA unleashed a sweeping array of open-weights domain-specific foundation models. The release highlights include the multimodal Nemotron 3.5 Super VL, the lightweight Nemotron 3.5 Bolt series, and the end-to-end Nemotron Retriever suite for embedding, reranking, and document OCR. For physical AI, NVIDIA debuted the Cosmos world models and Alpamayo 2 Edge autonomous driving models. In life sciences, NVIDIA and the Baker Lab released BioNeMo RFD4-Proteina, which establishes state-of-the-art accuracy across more than 10 protein design benchmarks while synthesizing 200-amino-acid binders roughly 13x faster than RFdiffusion3.
Zoom
Key Takeaways
NVIDIA released an extensive open-weights portfolio at GTC Berlin: Nemotron 3.5 Super VL, Bolt 4GB edge variants, and Cosmos world models
Unveils the full Nemotron Retriever suite for embedding, reranking, and multimodal document parsing, boosting enterprise RAG fidelity
Co-developed BioNeMo RFD4-Proteina with the Baker Lab, leading on over 10 structural protein design benchmarks
Synthesizes 200-amino-acid de novo proteins 13x faster than RFdiffusion3, dramatically shortening computational drug discovery timelines
Researchers introduced Matrix-Game 4.0 in arXiv:2610.27999, bridging the chasm between controllable video generation and genuinely playable, interactive virtual worlds. Current video world models suffer from severe state hallucination, inability to enforce rigid game mechanics (collision physics, inventory, win/loss rules), and sluggish response latency. Matrix-Game 4.0 resolves these barriers by decoupling game logic execution from visual synthesis through an executable game harness. A lightweight runtime tracks deterministic game states and rules, steering high-fidelity streaming video backbones to deliver playable, persistent, and low-latency virtual game environments.
Zoom
Key Takeaways
Matrix-Game 4.0 introduced in arXiv:2610.27999, architecting a decoupled paradigm separating game rule execution from generative video synthesis
Employs an executable game harness maintaining deterministic physics, collision boundaries, and game state, eliminating visual state drift
Transitions generative AI from passive controllable video playback to genuinely playable interactive game sandboxes
Maintains low-latency streaming inference, establishing an open blueprint for next-generation AI-native game design and interactive simulations
Researchers introduced ActionRoPE and Coordinate-Conditioned Noise Scheduling (CNS) in arXiv:2610.25861, solving spatial inconsistency in planar-camera game world models. In top-down and isometric gaming environments, naive feature-conditioned action mechanisms cause severe hallucination and revisit drift when players return to previously observed scenes. ActionRoPE directly converts action-induced camera displacements into world-coordinate rotary position embeddings (RoPE), ensuring identical physical world coordinates retain persistent token addresses across time. Benchmarks reveal that ActionRoPE cuts revisit drift by 66% over the strongest baseline while transferring across 1.3B to 33B parameter video backbones.
Zoom
Key Takeaways
ActionRoPE and Coordinate-Conditioned Noise Scheduling (CNS) introduced in arXiv:2610.25861, addressing spatial drift in planar game world models
Parameter-free action interface translates camera displacements into world-coordinate rotary embeddings, pinning physical regions to stable token addresses
Coordinate-Conditioned Noise Scheduling (CNS) stabilizes explored terrain early, slashing visual revisit drift by 66% over strong baselines
Demonstrates exceptional transferability across 1.3B to 33B parameter video diffusion backbones and out-of-distribution environments
Researchers from the Technical University of Munich (TUM) introduced TabWM (Tabular World Model) and the WorldRel benchmark generator in arXiv:2610.16763. Moving beyond traditional relational learning that only performs static prediction on database rows, TabWM formulates operational database environments as relational world models capable of simulating state transitions and downstream consequences under arbitrary business actions, unlocking offline reinforcement learning for enterprise decision agents.
Zoom
Key Takeaways
Technical University of Munich introduced TabWM and WorldRel (arXiv:2610.16763), formalizing relational databases as dynamic world models
Expands relational learning beyond static predictions to counterfactual simulations of state deltas under business actions
Achieves >0.84 correlation on state transition prediction from only 10-20 observed traces, improving decision-making utility by 28.4%
Provides enterprise teams with a differentiable simulation sandbox to train autonomous database and ERP agents via offline RL
Researchers from the University of Maryland, Google, and MBZUAI introduced BeliefWeaver (arXiv:2610.18082), an autonomous failure-recovery framework for long-horizon agents. Addressing cases where failures stem from root errors multiple steps earlier that local reflection cannot fix, BeliefWeaver maintains a persistent relational belief state across checkpoints and attempts, using an Implicit World Model (IWM) to evaluate hypotheses and gate repair execution. When distilled into a 9B model via on-policy distillation, it improves final benchmark scores by 9.8 percentage points while slashing teacher API costs by 54.8%.
Zoom
Key Takeaways
UMD, Google, and MBZUAI introduced BeliefWeaver (arXiv:2610.18082), an autonomous multi-step failure recovery framework for long-horizon agents
Maintains a persistent relational belief graph across attempts and employs an Implicit World Model (IWM) to gate repair execution
Improves terminal benchmark scores by +5.1 points; an on-policy distilled 9B student model beats baseline by +9.8 points
Slashes estimated teacher API costs by 54.8%, offering a highly economical blueprint for production-grade self-healing agents
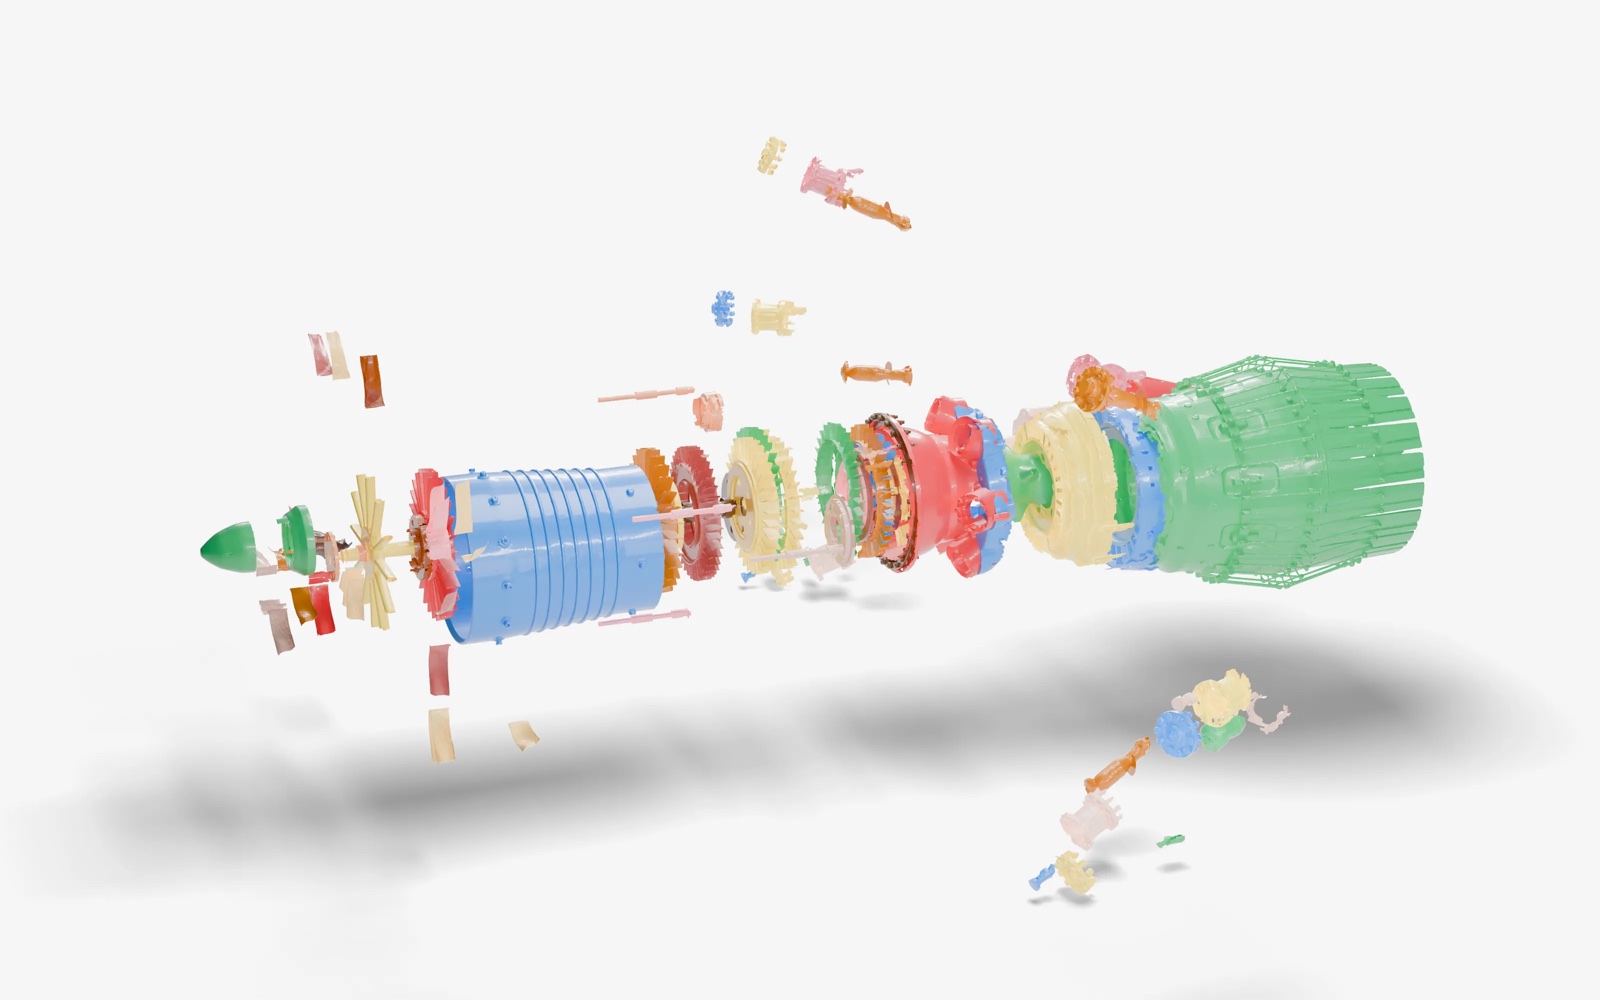
Skyfall AI, founded by the team behind Maluuba (acquired by Microsoft), released a research preview of SKY-001 on October 19, billing it as the first engineering world model. Instead of next-token prediction, it starts from text or a 2D image, generates several rough 3D options in parallel, recursively decomposes the chosen design into a parts tree, sketches and extrudes each part, then assembles them hierarchically for viewing in CAD tools such as Autodesk Fusion. On its own 3D CAD test it reports 79.7% IoU versus 79.1% for GPT-6 Astra, at 3.9 s and $0.005 per case versus 199 s and $0.75. Access is waitlist-only, with commercial deployment targeted for early 2027; all benchmarks are self-reported.
Zoom
Key Takeaways
3D CAD (self-reported): SKY-001 79.7% IoU, 3.9 s, $0.005 per case; GPT-6 Astra 79.1%, 199 s, $0.75; Opus 5.5 69.4%; Grok 4.7 completed none.
BIM (self-reported): SKY-001 43.6% IoU, 1.22 s, about $0.0024 per case; best LLM Gemini 3.8 Flash at 42.3%; 118x faster and 188x cheaper than GPT-6 Astra.
Four stages: parallel design exploration, recursive diffusion-based 3D decomposition, 2D-to-3D latent modeling, hierarchical assembly; the Jaguar E-Type demo yields 103 leaf parts and 139 nodes.
Availability: research preview behind a waitlist; the press release targets commercial deployment in early 2027; parameter count, training data and API pricing are not disclosed.
Team: Maluuba founders Sam Pasupalak, Kaheer Suleman and Sumit Pasupalak; backers include Fidelity, Touring Capital, M13 and iNovia Capital.
Current memory benchmarks for video world models conflate whether an action was carried out with whether the model remembered its outcome, incorrectly attributing action execution failures to cognitive memory loss. Researchers from HKU and Tsinghua introduced MIST (arXiv:2610.23542, 12 upvotes on Hugging Face). By decoupling physical execution from temporal memory, MIST reveals that up to 70% of apparent memory failures in leading models are actually execution failures. Correcting for execution raises true scene memory accuracy by +11.8 to +29.6 percentage points.
Zoom
Key Takeaways
HKU-MMLab and Tsinghua introduced MIST (arXiv:2610.23542, 12 upvotes on Hugging Face Papers)
Reveals that over 70% of apparent memory failures in video world models are actually action execution failures in intermediate frames
Proposes a decoupled three-stage causal pipeline separating scene establishment, action execution, and temporal memory retention
Improves true long-horizon memory consistency scores by +11.8 to +29.6 points across standard WRBench and MBench suites
Modern 3D world models typically use view-dependent features from geometry foundation models (GFMs) as predictive states, entangling camera-induced variations with physical scene dynamics. Tongji University and Tencent introduced GeoState (arXiv:2610.22343). By aggregating multi-view GFM features into a view-decoupled 3D scene state, GeoState models physical scene evolution independently of camera viewpoints, maintaining a single context-derived scale throughout rollouts without per-frame scale realignment.
Zoom
Key Takeaways
Tongji University and Tencent introduced GeoState (arXiv:2610.22343) for view-decoupled 3D world modeling
Separates physical scene evolution from camera-dependent observations via a dedicated scene tokenizer and ray-based geometry decoder
Maintains a single context-derived scale throughout multi-second rollouts on Waymo without per-frame scale alignment, outperforming VGGT-World and FR3D
Demonstrates robust zero-shot cross-sensor generalization across KITTI and nuScenes datasets
Robotic world models struggle to predict physics when key environmental properties (friction, mass, contact dynamics) cannot be directly seen. Researchers from Stanford, CMU, and Toyota Research Institute introduced T2-z (arXiv:2610.22364, GitHub: T2-z-latent-optimization/T2-z). By freezing the world model and optimizing a compact environment latent z_e at test time from as little as a single interaction trajectory, T2-z halves physical error and raises real-world robot task success from 33.73% to 72.96%.
Zoom
Key Takeaways
Stanford, CMU, and TRI introduced T2-z (arXiv:2610.22364) for test-time optimization of unobservable physical latents in robot world models
Freezes the world model and optimizes a compact environment latent z_e using as little as a single test trajectory
Reduces physical prediction error from 15.20 to 7.00 and elevates action success from 33.73% to 72.96% across 7 simulated tasks
Dramatically improves real-robot manipulation, raising Ball Friction success from 0% to 62.50% and Door Close from 22.22% to 55.56%
Addressing the representation gap between high-level VLM semantics, video world models, and low-level control in Vision-Language-Action (VLA) architectures, PINT (arXiv:2610.16355) introduces learnable chunk-level Predictive Intent Tokens to reach 15.5% on RoboTwin 2.0-Hard without embodied pretraining (4.8x over StarVLA's 3.2%). Alongside PAIR (arXiv:2610.09016) and PKU's SimForcing (arXiv:2610.06598), these frameworks bridge perception and action with zero inference overhead.
Zoom
Key Takeaways
PINT (arXiv:2610.16355) coordinates VLM, video world modeling, and action decoding via shared Predictive Intent Tokens, reaching 15.5% on RoboTwin 2.0-Hard without embodied pretraining (4.8x over StarVLA's 3.2%)
PINT achieves 79.5% on LIBERO-Plus and 68% ID / 24% OOD success across 5 real-world bimanual robot tasks, outperforming pretrained Motus (35% / 9%)
PAIR (arXiv:2610.09016) uses a training-only Masked Action Autoencoder and Bridge Module with zero inference overhead, lifting OpenVLA-OFT across 7 real-world robot tasks from 51.4% to 65.0% (+13.6 pts)
PKU's SimForcing (arXiv:2610.06598) distills simulation motion priors into real-domain robot world models, achieving SOTA video fidelity on Bridge and InternData-A1
Three new studies tackle verification, evaluation, and RL alignment for rule-governed generative world models: OmniVerifier-C1 (arXiv:2610.22355, 32 upvotes) uses Decoupled RL to train a decomposed graded visual verifier that reaches 0.684 on ViVerBench and boosts FLUX.1-dev GenEval from 0.68 to 0.79 while enabling Maze and Sudoku world modeling; Meituan's WorldCast benchmark (arXiv:2610.20731, 30 upvotes) evaluates 12 models across 320 multi-step world state prediction cases, finding GPT-Image-2.5 System at 72.8 vs. 42.8 for Nano Banana Pro and 20.1 for the top open model; and NUS's Routing Policy Optimization (RPO, arXiv:2610.22282, 23 upvotes) turns attention routing into an internal exploration action to train video/image diffusion RL 3.1x–4.2x faster than Flow-GRPO and DanceGRPO.
Zoom
Key Takeaways
OmniVerifier-C1 uses Decoupled RL (DAPO) to jointly optimize sub-question binary judgments and global continuous scoring, reaching 0.684 on ViVerBench and boosting FLUX.1-dev GenEval from 0.68 to 0.79
Meituan's 320-case WorldCast benchmark reveals a massive gap in multi-step visual state prediction: GPT-Image-2.5 System scores 72.8 vs. 42.8 for Nano Banana Pro and 20.1 for the best open-source model
NUS's Routing Policy Optimization (RPO) uses internal attention routing exploration to align Wan2.2-TI2V-5B in just 24.1 GPU-hours—3.1x faster than Flow-GRPO and 4.2x faster than DanceGRPO
Four new studies advance interactive video world models and streaming video agents: NUS's training-free Velox router (arXiv:2610.22311) uses 3D camera frustum-slab correspondences on H200 GPUs to accelerate chunk-48 attention by 4.36x and denoising by 2.43x with negligible quality loss; Nankai University's DeltaStreamer (arXiv:2610.19849, 39 upvotes) combines change-aware memory with targeted frame replay to reach 66.07% on OVO-Bench; HKPolyU's CoWorld Reasoner (arXiv:2610.21910) co-evolves a VLM-VWM tool harness for +13.0% relative gains on ERQA; and Zhejiang University releases the 260-case WorldMemBench (arXiv:2610.19063).
Zoom
Key Takeaways
NUS's training-free Velox router uses 3D camera frustum slabs on H200 to speed up chunk-48 attention by 4.36x and denoising by 2.43x within 0.15 points of dense attention on WBench
Nankai University's DeltaStreamer combines change-aware memory with targeted frame replay to achieve 66.07% on OVO-Bench and 59.53% on StreamingBench
HKPolyU's CoWorld Reasoner co-evolves a VLM-VWM imagination harness for +11.8% (MMSI) and +13.0% (ERQA) relative gains, alongside ZJU's 260-case WorldMemBench