AI Coding Live News

Kakao Open-Sources Kanana-2-v-decide-3b: 3.67B Multimodal Decision Model Returning Probabilities, Choices and Scores; Vendor Decision Index Avg 61.23

On 2026-11-06 Kakao open-sourced Kanana-2-v-decide-3b-2611 on Hugging Face (~3.67B), built on Kanana-2-v-3b: no text generation, only choice / noul / score with probabilities. Vendor: 72.50 on Kanana Decision Bench; 61.23 avg on Decision Index + Vision; mean <0.04s on one H200, claimed ~43x vs GPT-6 Luna. Commercial Kanana Open License.

Kakao Open-Sources Kanana-2-v-decide-3b: 3.67B Multimodal Decision Model Returning Probabilities, Choices and Scores; Vendor Decision Index Avg 61.23

Key Takeaways

  • Official: HF open weights kakaocorp/kanana-2-v-decide-3b-2611 (~3.67B), commercial Kanana Open License
  • Form: embedding similarity + softmax; choice / noul / score — no text generation
  • Vendor: 72.50 on Kanana Decision Bench; 61.23 avg on Decision Index + Vision
  • Vendor: mean <0.04s on one H200; claimed ~43x vs GPT-6 Luna
  • Try: transformers system_one / pipeline("decision") or HTTP System One server
Read full story
Linked Models & Agents:
⚡ Kanana-2-v-decide-3b-2611⚡ Kanana-2-v-3b⚡ GPT-6 Luna🤖 Agent decision / tool selection🌐 Kakao

AWS Kiro Crew Ships Bots GA: Named Long-Running Agents with Own Memory and Parallel Sessions — Delegate Processes, Not Tasks

On November 5 Kiro (@kirodotdev) announced Kiro bots GA in open-source multi-agent Kiro Crew. Each bot has persistent Notes, its own workspace and Dashboard; it launches parallel workers, redirects drift, consolidates results, and asks approval when needed — with schedules and per-role minimal tool permissions.

AWS Kiro Crew Ships Bots GA: Named Long-Running Agents with Own Memory and Parallel Sessions — Delegate Processes, Not Tasks

Key Takeaways

  • Primary: @kirodotdev 2026-11-05 post + official blog Introducing bots in Kiro Crew
  • Shape: named long-running bot = Notes memory + parallel workers + one ongoing chat
  • Capabilities: monitor/redirect/consolidate; schedules; Dashboards
  • Permissions: tools scoped per role; expansion needs approval; Notes editable
  • Start: Kiro Crew sidebar Bots → Add a bot (default or custom agent)
Read full story

Glasshand Launches: Monthly Real iPhone/Mac Rentals for AI Agents ($60/$90), Works with Claude Code, Codex, Cursor

On November 5, Solid founder Trevor Keith launched Glasshand: dedicated real iPhones and Macs hosted in a data center—not emulators—so agents can see the screen and tap or type via API. Works with Claude Code, Codex, Cursor and others; agents can install apps, sign into iCloud, add eSIM for SMS codes, run social workflows or build/test in Xcode. Official pricing is $60/mo for an iPhone and $90/mo for a Mac, month to month with cancel anytime and factory wipe on release. It ranked #1 on Product Hunt that day.

Glasshand Launches: Monthly Real iPhone/Mac Rentals for AI Agents ($60/$90), Works with Claude Code, Codex, Cursor

Key Takeaways

  • Form factor: real iPhones/Macs in a data center, not VMs or emulators; agents see the screen and tap via Glasshand API/controller
  • Compatibility: Claude Code, Codex, Cursor, OpenClaw, Hermes or any agent; start with “Tell your agent to rent”
  • Capabilities: App Store installs, iCloud sign-in, eSIM SMS verification and iMessage; Macs for Xcode build/test
  • Pricing (official site): iPhone $60/mo, Mac $90/mo (USD + tax), month-to-month cancel anytime; no hourly/daily rental
  • Security: dedicated device, user-set password; erase + factory reset on release (vendor)
Read full story

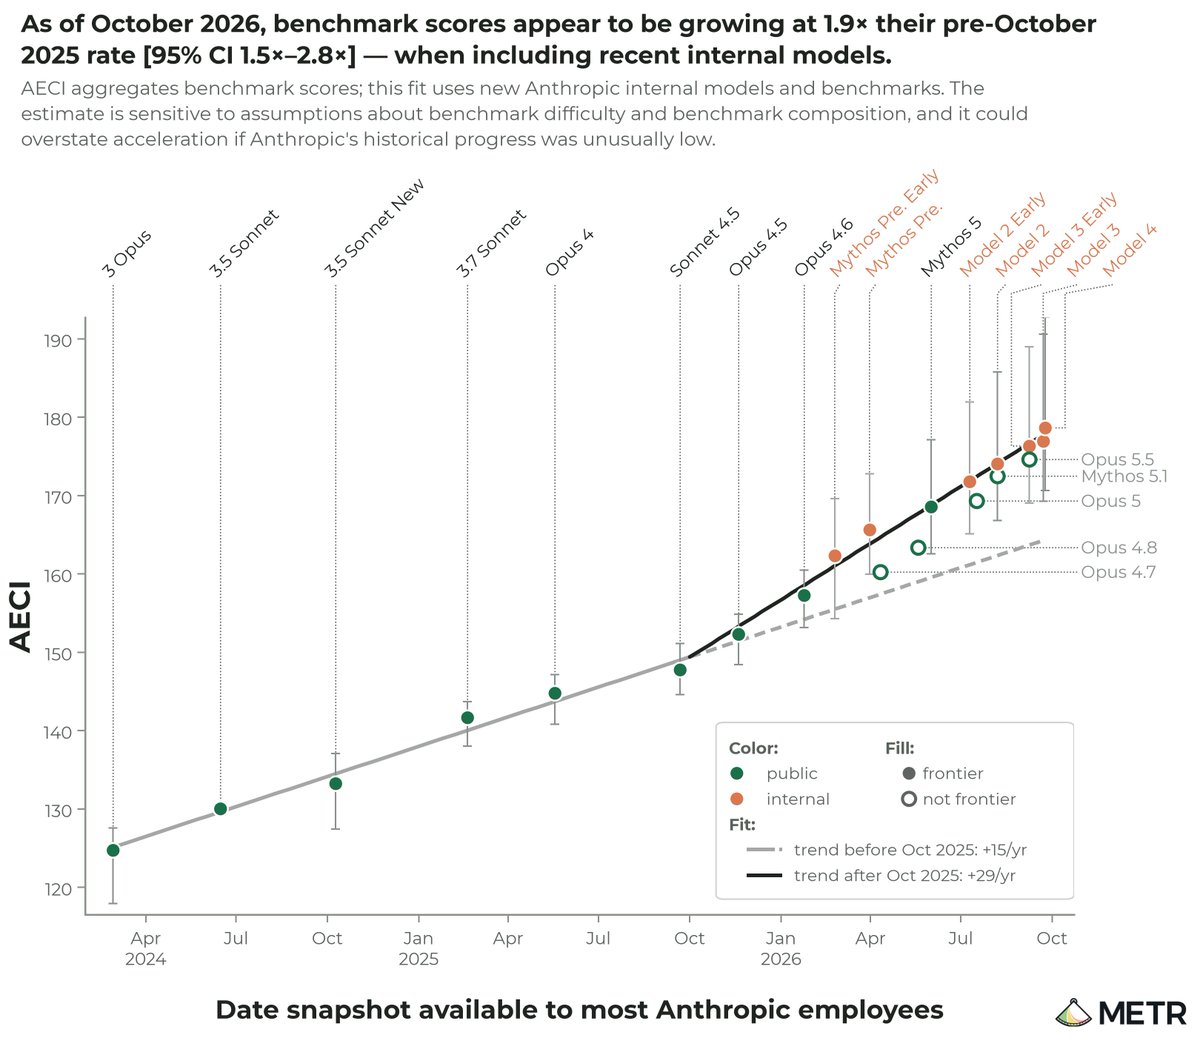
METR Assessment: Anthropic Capability Progress on Well-Specified Tasks ~2x Historical Rate; AECI ~1.9x Faster Since Oct 2025

On November 5, independent evaluator METR published a high-access assessment at Anthropic (Aug 12–Oct 29, 2026). As of October 2026, Anthropic is likely improving model capabilities on well-specified tasks at about twice the March 2024–October 2025 historical rate. Since October 2025, AECI scores grew at an estimated 1.9x the prior rate [95% CI 1.5–2.8]. METR judges that a majority of current acceleration is attributable to AI-assisted R&D, not faster training-compute scaling; Anthropic redacted much of the most informative evidence.

METR Assessment: Anthropic Capability Progress on Well-Specified Tasks ~2x Historical Rate; AECI ~1.9x Faster Since Oct 2025

Key Takeaways

  • Subjective call: ~2x historical rate on well-specified tasks (high uncertainty; ~1.3x–3x plausible; METR)
  • AECI: ~1.9x faster growth since Oct 2025 [95% CI 1.5–2.8], ~two years of prior progress in one year (includes unreleased models)
  • Attribution: confident not from faster training-compute growth; majority of current acceleration from AI-assisted R&D (~80% subjective guess), not fully autonomous contributions
  • Risk: no clear bottlenecks observed for next 12 months, so further acceleration risk; much key evidence redacted by Anthropic
  • Process: separate from the Oct 15 employee-like access pilot; compute-allocation verification was canceled mid-engagement
Read full story
Linked Models & Agents:
ADSponsored

Perplexity Launches Teammates: Persistent Work Agents on Computer with Slack, Research Preview for Max on Web

On November 5 Perplexity (@perplexity_ai) and CEO Aravind Srinivas (@AravSrinivas) launched Teammates: persistent personal agents on Computer that own ongoing responsibilities, inherit Projects, Skills, Memory and tool permissions, run in isolated desktops and browsers, collaborate with other teammates, and proactively monitor Slack. Official help docs call it a research preview for individual Max subscribers on the web; Enterprise Pro/Max are not included by default; native mobile and desktop apps are coming later.

Perplexity Launches Teammates: Persistent Work Agents on Computer with Slack, Research Preview for Max on Web

Key Takeaways

  • Shift from one-shot prompts to high-level goals; a teammate keeps its role until you reassign it (vendor/CEO)
  • Multi-agent orchestration, isolated desktop/browser, proactive monitoring of Slack/GitHub/Linear connectors
  • Individual Max (~$200/mo, ~10k Computer credits/mo) web research preview; Enterprise not included by default (help center)
  • Internal adoption: CEO says ~10k teammates in 30 days (~20x headcount) with ~1k active yesterday (personal claim, not an audit)
  • Setup on web: assign role and escalation, take over the desktop, or redirect; shared chats are read-only for others
Read full story

Mistral Studio Adds Managed Agents and Apps: Durable Background Agents, Natural-Language Workflow Builder, HTTP Connectors and Online Evals

On November 5 Mistral expanded Mistral Studio. Managed Agents, built with the Agents SDK (mistralai-agents), run the same code in-process, self-hosted (agents serve) or Mistral-managed (agents deploy), with durable execution for hours or days, crash resume and human approvals. Mistral also shipped a Vibe-powered workflow builder, the mistral apps CLI, HTTP API connectors, webhooks and triggers, a managed search index, and offline and online evaluations, mostly in Public Preview.

Mistral Studio Adds Managed Agents and Apps: Durable Background Agents, Natural-Language Workflow Builder, HTTP Connectors and Online Evals

Key Takeaways

  • One agent codebase, three run modes: in-process, self-hosted agents serve, or managed agents deploy
  • Durable background execution for hours or days, resuming from the last finished step; Mistral stores sessions
  • Connectors now speak HTTP APIs with no MCP server needed; webhooks and triggers start workflows or agents
  • Managed agents emit agent, model and tool spans by default, and traces can become eval datasets in one click
  • Observability and evaluations are Enterprise-tier; most new features are Public Preview (vendor statement)
Read full story

Claude Launches Personal Finance Beta in the US: Read-Only Bank Linking via Plaid, Up to 16 Banks and 24 Months of Transactions

On November 5 Anthropic announced a US beta of Personal Finance in Claude via @claudeai. Users link bank, card, loan and investment accounts through Plaid, see balances, cash flow, subscriptions and bills on one page, and ask questions in plain language. The official help article says access is read-only, so Claude cannot move, manage or invest money. It is limited to US Pro, Max and Ultra personal plans (not Free, Team or Enterprise) and is rolling out gradually.

Claude Launches Personal Finance Beta in the US: Read-Only Bank Linking via Plaid, Up to 16 Banks and 24 Months of Transactions

Key Takeaways

  • Read-only: balances, credit limits and up to 24 months of transactions; no money movement (vendor statement)
  • Up to 16 linked banks, US banks only; sign-in via Plaid so Claude never sees bank passwords
  • Pro, Max and Ultra personal plans only, on web, Desktop, iOS and Android, rolling out gradually
  • Chats inside the Personal Finance hub are not used for training; chats using account data are kept out of memory
  • Linked accounts cannot yet be used in Cowork, scheduled tasks or Claude Code
Read full story

OpenAI Launches GPT-6 Cyber: ExploitGym 48.5%, Out-of-Scope Rate Down to 0.07%, Daybreak Red Select Access, Critical Preparedness

On November 5 OpenAI launched GPT-6 Cyber for authorized security research: ExploitGym rose from GPT-5.6 Cyber's 32.1% to 48.5% (about 51% relative), out-of-scope exploitation fell to 0.07% without deployment prompts and 0% with them. The model helped find 81 novel high-severity Firefox bugs and develop exploits for 948 Linux privilege-escalation cases, and OpenAI raised its Preparedness Framework cyber rating from High to Critical. It is initially available via API and Codex to select Daybreak Red customers, with expansion to all Red customers planned.

OpenAI Launches GPT-6 Cyber: ExploitGym 48.5%, Out-of-Scope Rate Down to 0.07%, Daybreak Red Select Access, Critical Preparedness

Key Takeaways

  • ExploitGym 48.5% vs GPT-5.6 Cyber 32.1% (~51% relative gain; vendor figures)
  • Scope alignment: 99.93% avoided out-of-scope services without deployment prompts; 100% with them
  • Real-world: 81 novel high-severity Firefox vulns; 1,724 Linux vulns reproduced, 948 exploits developed
  • Preparedness raised to Critical; RemoteExploitBench 95% completion (Astra refused 100%)
  • Select Daybreak Red via API/Codex first; Daybreak Blue alpha for Astra defensive use expanding
Read full story
Linked Models & Agents:

Gemini API Computer Use Tool Goes GA: Browser, Mobile and Desktop Agents Production-Ready, No Breaking Changes from Preview

The Gemini API changelog shows the Computer Use tool reached general availability on October 30 across both the Interactions and GenerateContent APIs; @GoogleAIStudio announced on November 4 that there are no breaking changes from preview and it is production-ready for browser, mobile and desktop control agents. Official docs list supported models: Gemini 4 Argon, the recommended Gemini 3.8 Flash, Gemini 3.5 Flash-Lite and Gemini 3 Flash Preview. Actions carry an intent field, responses may include a safety_decision requiring user confirmation, and opt-in screenshot prompt-injection detection is available.

Key Takeaways

  • Computer Use is GA on both the Interactions and GenerateContent APIs as of October 30
  • Google says there are no breaking changes from preview, so existing code carries over
  • Three environments: browser, mobile and desktop; Gemini 3.8 Flash is the recommended model
  • Every action includes an intent field; safety_decision can require user confirmation or block
  • Opt-in screenshot prompt-injection detection (Gemini 3.5 Flash-Lite and later, off by default)
Read full story

OpenAI Publishes National Community Compact: Pays Full Campus Power Costs, No NDAs With Officials, Public Impact Reporting

On November 5 OpenAI published a National Community Compact for U.S. compute campuses it owns and operates: no NDAs with public officials except narrow security carve-outs, public construction and impact reporting (noise, water, energy), Ratepayer Protection Pledge to pay full electricity and incremental grid costs with stranded-asset assurances, Grid Protector peak curtailment (up to 1,000 MW in Effingham, Georgia), and community investments already listed at $80M in Effingham and $40M in Pike County, Ohio. A PDF of the Compact is on openai.com.

OpenAI Publishes National Community Compact: Pays Full Campus Power Costs, No NDAs With Officials, Public Impact Reporting

Key Takeaways

  • On November 5 OpenAI published a National Community Compact as the baseline for campuses it owns and operates
  • It pledges no NDAs with public officials (narrow carve-outs) and public reporting on noise, water, energy and sustainability
  • Ratepayer Protection Pledge: OpenAI pays full campus power and incremental grid costs, with assurances against stranded assets
  • Grid Protector continues: up to 1,000 MW peak demand response at Effingham, Georgia
  • Community investments cited: $80M Effingham and $40M Pike County; each campus still gets a local Compact
Read full story
Linked Models & Agents:
ADSponsored

Artificial Analysis: Tencent Hy4 Scores 35 on Intelligence Index v5, Ranked No.2 Among China Labs, 31% on FrontierCode 2.0

Independent evaluator Artificial Analysis published Tencent Hunyuan Hy4 results on the Intelligence Index v5 on November 5 (08:28 UTC): a composite score of 35, tying Grok 4.7 (xhigh) and one point behind Claude Haiku 5.5 (max). Among China-based labs it ranks second only to Kimi K3.1 Pro (46). On agentic coding it scores 31% on FrontierCode 2.0 and 37% on Terminal-Bench 4.0; cost per Intelligence Index task is about $0.78, roughly one-tenth of same-score Grok 4.7.

Artificial Analysis: Tencent Hy4 Scores 35 on Intelligence Index v5, Ranked No.2 Among China Labs, 31% on FrontierCode 2.0

Key Takeaways

  • Intelligence Index v5 composite 35: ties Grok 4.7 (xhigh), one point behind Haiku 5.5 (max, 36); No.2 China-lab model behind Kimi K3.1 Pro (46)
  • FrontierCode 2.0 at 31% (leads China labs; DeepSeek V4.1 Flash 1017 max 28%, Kimi K3.1 Pro 25%); Terminal-Bench 4.0 at 37%
  • AA-Omniscience v1.1 accuracy 50% but hallucination rate 89% (Kimi K3.1 Pro hallucination 37%); HLE-Diamond 33%
  • About $0.78 per Intelligence Index task: ~10x cheaper than same-score Grok 4.7, ~13x cheaper than Qwen3.8 Max (34), nearly 2x Haiku 5.5
  • Pricing about $0.834/$2.501 per 1M input/output tokens, cache reads $0.042; 1M context; text and image input
Read full story

Notion: MCP Shared Brain Lets ChatGPT, Claude, Muse and Bot Share Memories and Skills, With Official Agent Setup Prompts

On November 4 NotionHQ announced that via Notion MCP, ChatGPT, Claude, Muse and Bot can read and write the same Memories and Skills—one shared brain across agents. Official setup prompts (v0.0.6, Oct 30), help docs and a Nov 3 MCP use-cases blog corroborate the product push.

Notion: MCP Shared Brain Lets ChatGPT, Claude, Muse and Bot Share Memories and Skills, With Official Agent Setup Prompts

Key Takeaways

  • NotionHQ post (Nov 4, 19:14 UTC) had about 3,271 likes, 225 reposts, 4,560 bookmarks and ~589K views when fetched
  • Product claim: ChatGPT / Claude / Muse / Bot share Memories and Skills in Notion so switching agents does not reset context
  • Official setup prompt v0.0.6 (2026-10-30): walks agents through an Agent Operating Guide and custom-instruction paste for ChatGPT / Claude
  • Help center: Notion MCP works with Claude, Cursor, ChatGPT Pro and more; Enterprise can approve a whitelist and govern connections
  • Vendor blog (Nov 3): five team stories of MCP workflows as reusable SOPs; Skills via MCP are listed as coming soon
Read full story

Anthropic: Claude Helps Map the First Prokaryotic Vault Particle Structure; Purification in ~90 Minutes, First Model in ~34 Hours

On November 4 Anthropic's biology team reported that Claude helped determine the first 3D vault structure from a prokaryotic/phage system (protein L05). Vendor-reported timing: ~90-minute purification and a first model in ~34 hours, plus an open discussion of mistakes and the multi-agent research workflow.

Anthropic: Claude Helps Map the First Prokaryotic Vault Particle Structure; Purification in ~90 Minutes, First Model in ~34 Hours

Key Takeaways

  • Official Anthropic research: Claude helped determine the first 3D prokaryotic/phage vault structure (protein L05)
  • Vendor-reported timing: purification cut from ~3 days to ~90 minutes; first model ready in ~34 hours
  • L05 forms a ~9.5 MDa shell of 96 chains with ~25% more volume than mammalian vaults
  • Anthropic also discloses failures: a medium additive cost ~2 weeks; an early cryo-EM map was mirrored
  • For developers: a concrete case of a science multi-agent harness with human oversight, not biology trivia
Read full story
Linked Models & Agents:
⚡ Anthropic Claude🤖 claude🌐 Anthropic

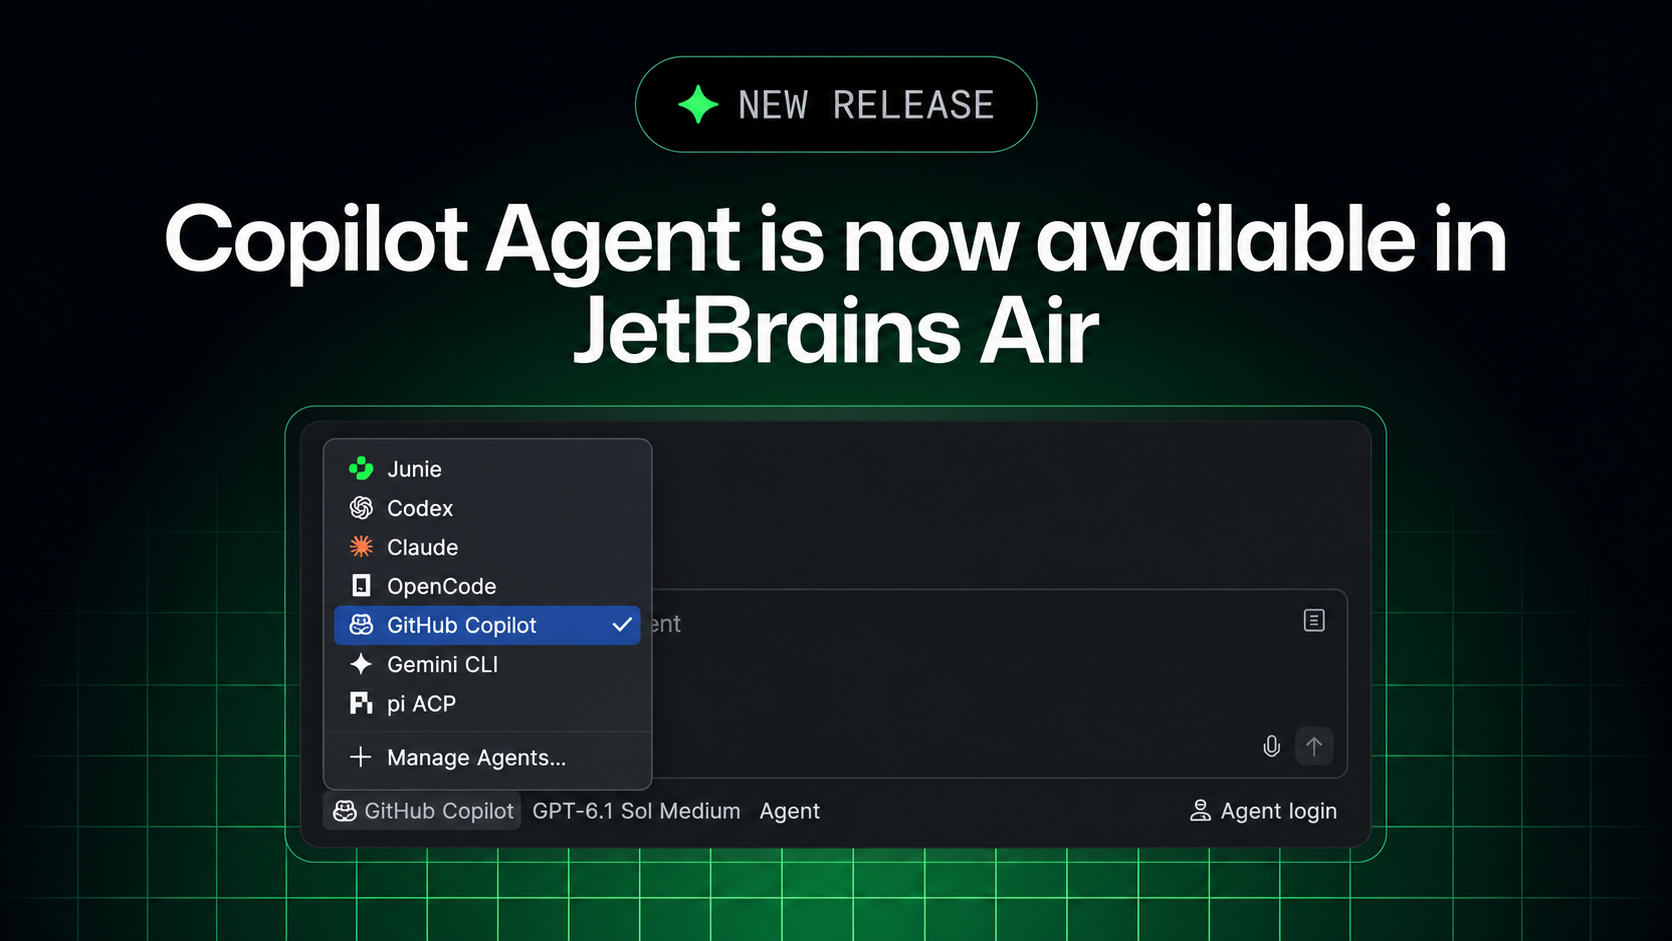
GitHub Copilot Comes to JetBrains Air: Run Coding Tasks Locally in the IDE or in Isolated Cloud Environments via ACP, Billed to Your Copilot Subscription

On November 3 GitHub announced on its official changelog that GitHub Copilot is now available in JetBrains Air. The integration is built on the Agent Client Protocol (ACP): developers pick Copilot in Air's agent picker, delegate coding tasks, track several sessions in parallel and review changes next to their code. Tasks can run locally in a JetBrains IDE or in isolated cloud environments through Air Teams, and they draw on the Copilot subscription rather than JetBrains AI credits.

GitHub Copilot Comes to JetBrains Air: Run Coding Tasks Locally in the IDE or in Isolated Cloud Environments via ACP, Billed to Your Copilot Subscription

Key Takeaways

  • Copilot now appears in JetBrains Air's agent picker and works with an existing Copilot account
  • The integration uses the Agent Client Protocol (ACP) and can be used alongside the existing GitHub Copilot plugin
  • Developers can track multiple agent sessions in parallel and review changes next to their code using project context and IDE tools
  • Cloud tasks run through Air Teams, each in a Docker container on a fresh virtual machine, with traffic through a proxy and no state kept between tasks
  • Cloud tasks use the Copilot plan rather than JetBrains AI credits, but Air analytics do not include Copilot usage and admins cannot set Copilot spending limits inside Air
Read full story

Claude Code Background Subagent Status Lines Now Written by Haiku 5.5: About 99% Cheaper per Update, About 6% More Prompts per Limit

On November 4 ClaudeDevs, Anthropic's official developer account, said the status line that a background subagent in Claude Code refreshes every 30 seconds used to re-read its whole conversation each time, and is now written by Haiku 5.5 from short notes, so each update costs about 99% less. Anthropic says sessions with background subagents used about 5% less of the limit, giving about 6% more prompts on the same limit. It is live for most Pro, Max and Ultra users and everyone on Team and Enterprise, on v2.1.316 or later.

Key Takeaways

  • A background subagent refreshes its status line every 30 seconds, and each refresh used to re-read the subagent's whole conversation
  • Haiku 5.5 now writes the status line from short notes, which Anthropic says makes each update about 99% cheaper
  • The subagent itself keeps its own model; only the status line is written by Haiku 5.5
  • Anthropic says sessions with background subagents used about 5% less of the limit, so the same limit gives about 6% more prompts
  • It is live for most Pro, Max and Ultra users and everyone on Team and Enterprise; update to v2.1.316 or later
Read full story